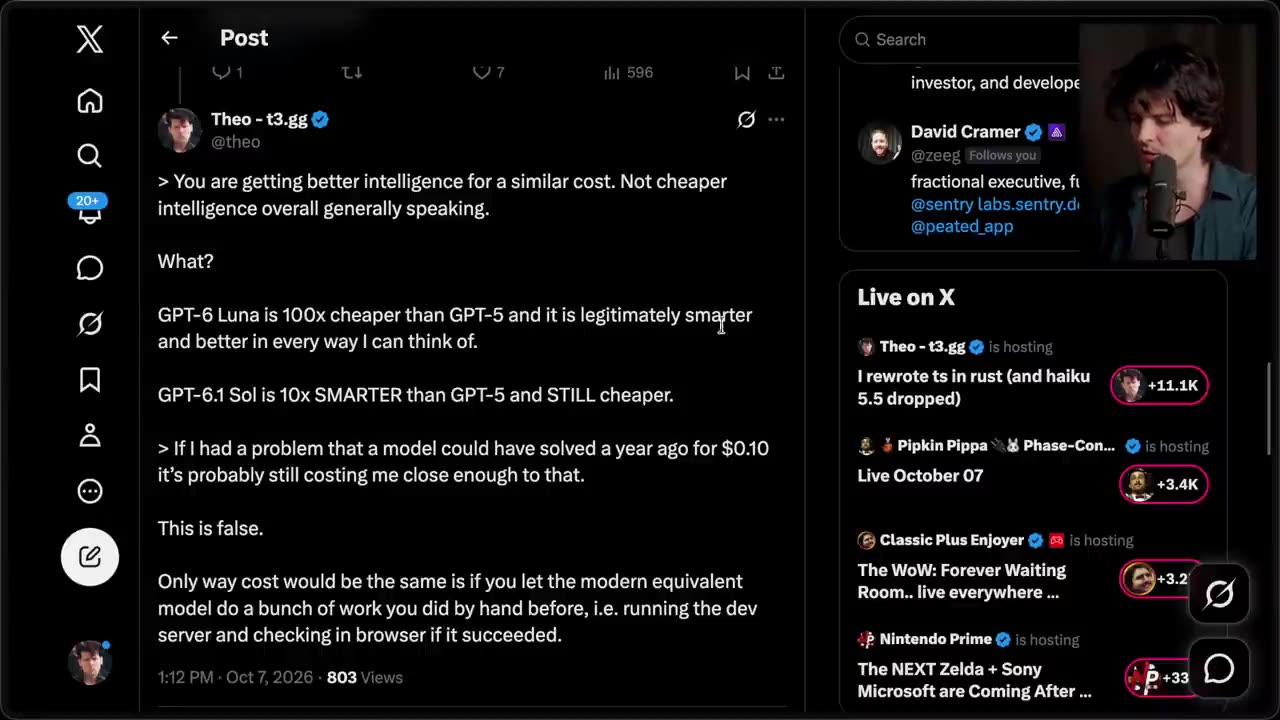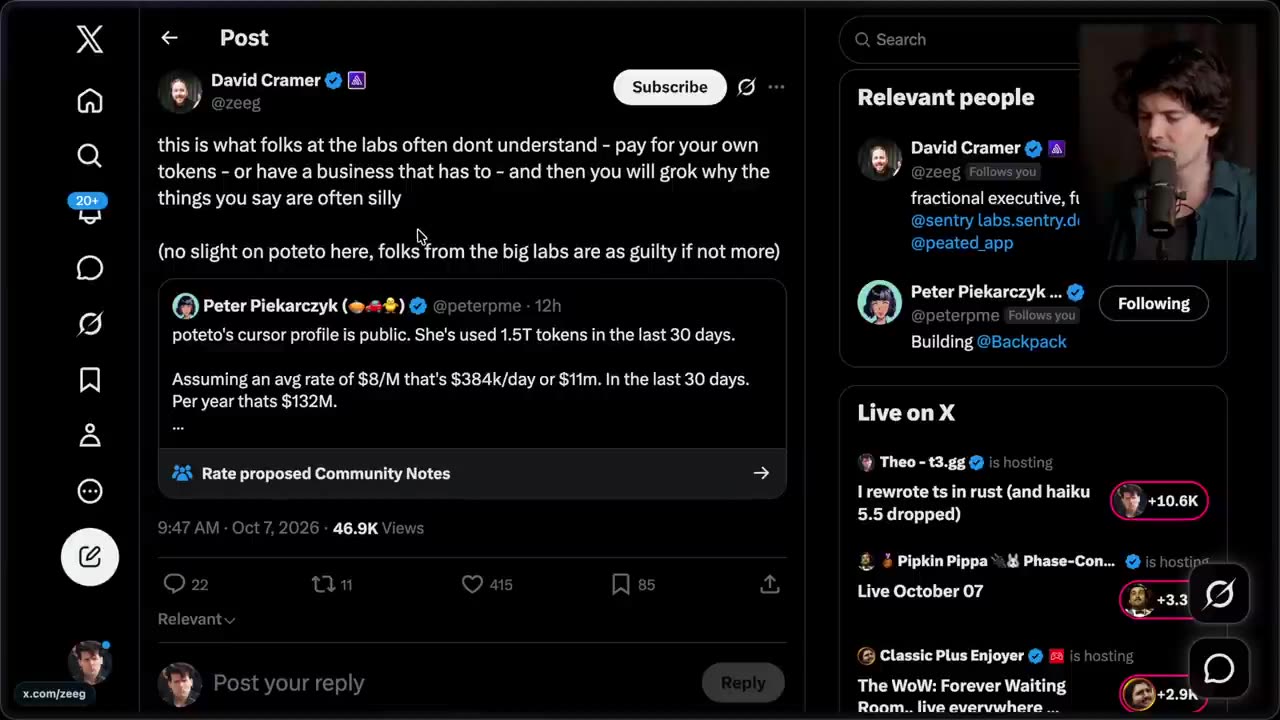
this is what folks at the labs often dont understand - pay for your own tokens - or have a business that has to - and then you will grok why the things you say are often silly (no slight on poteto here, folks from the big labs are as guilty if not more) That's only true to benchmarks though and you aren't actually getting net net cheaper intelligence everywhere. Old models get retired so there's no true price drop regularly. We have seen some (Luna is the best example afaik), but largely costly to achieve outcomes using the tech have not gone done within a lot of prime use cases - at least not at the same rate. fractional executive, f @sentry labs.sentry.d @peated_app That's only true to benchmarks though and you aren't actually getting net cheaper intelligence everywhere. Old models get retired so there's no true price drop regularly. We have seen some (Luna is the best example afaik), but largely cost to achieve outcomes using the tech have not gone done within a lot of prime use cases - at least not at the same rate. Eg they're good at implementing a clone of prior art cheaply but not that cheap to do net new complex work - and we've gone from a mix of human hours and machine hours to lots of machine hours for similar outcomes in many scenarios. I agree it will get cheaper and my comment wasn't about Lauren's posts as much as it was the broader “this is what I do” narrative from a lot of labs interface employees where they burn six figures a month in interface Eg they're good at implementing a clone of prior art cheaply but not that cheap to do net new complex work - and we've gone from a mix of human hours and machine hours to lots of machine hours for similar outcomes in many scenarios. I agree it will get cheaper and my comment wasn't about Lauren's posts as much as it was the broader "this is what I do" narrative from a lot of labs employees where they burn six figures a month in interface You are getting better intelligence for a similar cost. Not cheaper intelligence overall generally speaking. Like often the old rates go away because there is no infra to run the models (or they don't want you to use them because it doesn't cover any costs). And the "10x better intelligence" is benchmarks which we all know how reliable they are. A 1% gain might be a "10x improvement". I'm not saying it's not getting cheaper but folks who quote those numbers do so without considering the practical rate of improvement and cost of applied AI. If I had a problem that the model could have solved a year ago for $0.10 it's probably still costing me close enough to that. That's what I mean by it's not actually gotten cheaper in a lot of scenarios. Certainly not hasn't gotten eg 30x cheaper for that kind of space. And then problems which models struggle to solve haven't gotten eg 30x more reliable to solve. They've gotten better at it but the numbers don't actually scale to outcomes.
Did  Theo
mention me?
Theo
We scan every video for X posts on screen, then check the transcript to see if they were read aloud. See everything Theo showed.
Every post with your handle on screen. A profile or post link works too.
Matches the text of one post, even if the handle was cropped out.
A few words you remember. Matches by words and by meaning.
@zeeg
Yes.
Theo showed your posts 9 times and read 4 aloud.
-
David Cramer@zeeg
Theo read it aloud at 2:08 In particular, I have to explain why what Zeeg said here about people working at the labs not understanding how no one can ever spend this much on tokens.
-
David Cramer@zeeg
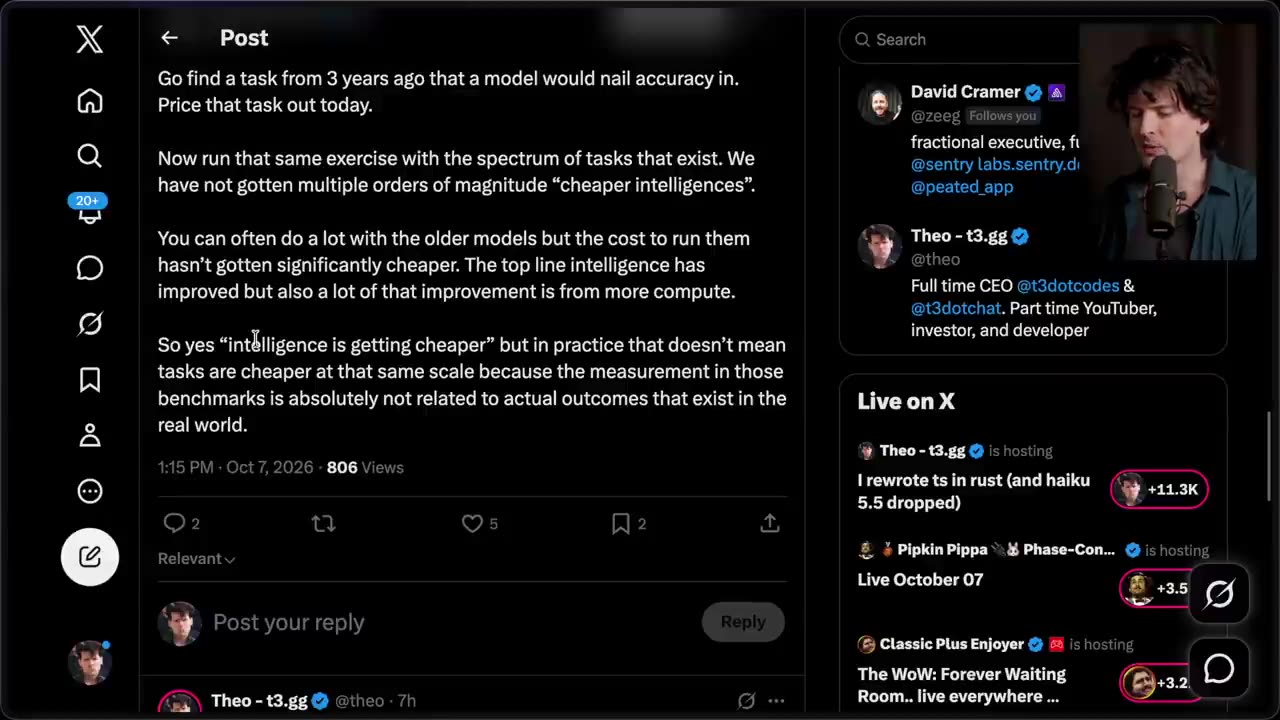
fractional executive, f @sentry labs.sentry.d @peated_app Go find a task from 3 years ago that a model would nail accuracy in. Price that task out today.
Theo read it aloud at 22:28 He challenged me to go find a task from three years ago that a model would nail in accuracy.
-
David Cramer@zeeg
Go find a task from 3 years ago that a model would nail accuracy in. Price that task out today. Now run that same exercise with the spectrum of tasks that exist. We have not gotten multiple orders of magnitude “cheaper intelligences”. You can often do a lot with the older models but the cost to run them hasn't gotten significantly cheaper. The top line intelligence has improved but also a lot of that improvement is from more compute. So yes “intelligence is getting cheaper” but in practice that doesn't mean tasks are cheaper at that same scale because the measurement in those benchmarks is absolutely not related to actual outcomes that exist in the real world. Go find a task from 3 years ago that a model would nail accuracy in. Price that task out today. Now run that same exercise with the spectrum of tasks that exist. We have not gotten multiple orders of magnitude “cheaper intelligences”. You can often do a lot with the older models but the cost to run them hasn't gotten significantly cheaper. The top line intelligence has improved but also a lot of that improvement is from more compute. So yes “intelligence is getting cheaper” but in practice that doesn't mean tasks are cheaper at that same scale because the measurement in those benchmarks is absolutely not related to actual outcomes that exist in the real world. Go find a task from 3 years ago that a model would nail accuracy in. Price that task out today. Now run that same exercise with the spectrum of tasks that exist. We have not gotten multiple orders of magnitude "cheaper intelligences". You can often do a lot with the older ? Show more
Theo read it aloud at 27:47 And this is the part that's hardest is David was very careful to frame things in ways where he is not angry or upset in his verbage, while also triggering me really
-
David Cramer@zeeg
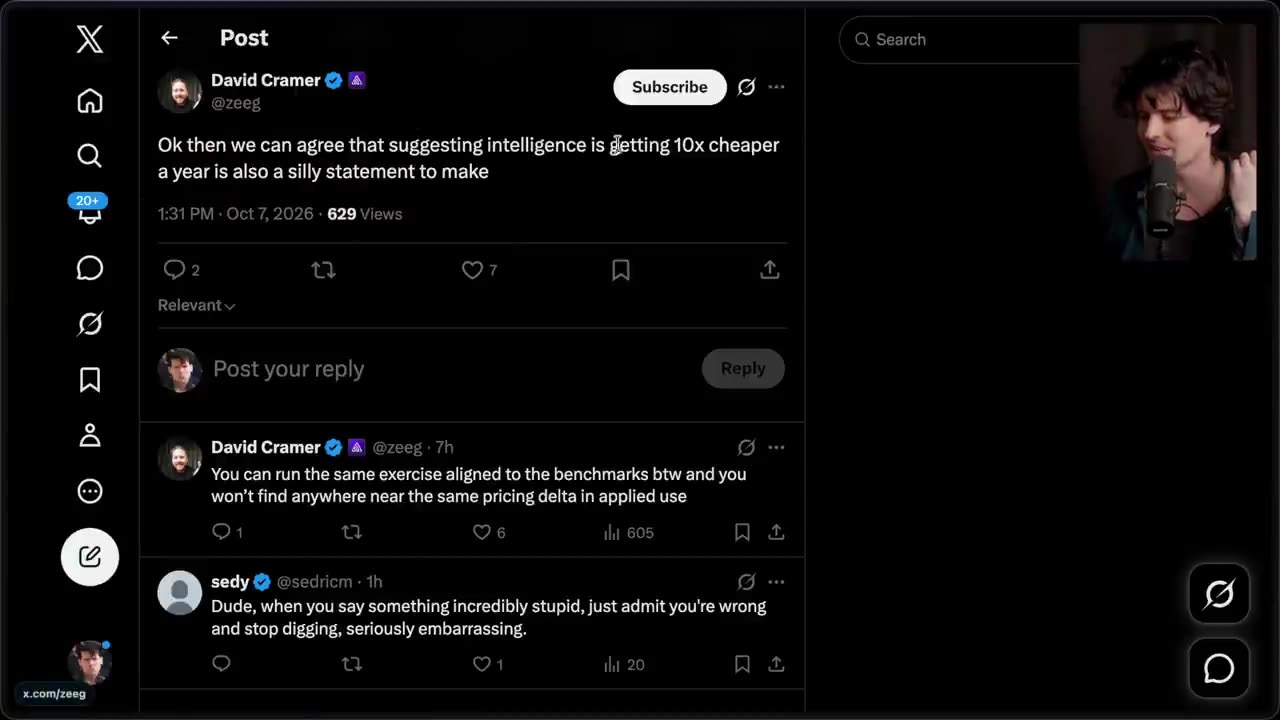
Ok then we can agree that suggesting intelligence is getting 10x cheaper a year is also a silly statement to make You can run the same exercise aligned to the benchmarks btw and you won't find anywhere near the same pricing delta in applied use Also this deserves an extra thank you Google for deprecating a model that works well for us and replacing it with a more expensive model we don't need. I'm particularly annoyed by the vendors these days. I'm hoping Jev was the launch of really bringing the price down for a set of things. I think we can do a lot more with absolute dollars being lower than we can with absolute intelligence being higher this is what folks at the labs often dont understand - pay for your own tokens - or have a business that has to - and then you will grok why the things you say are often silly (no slight on nobody here, folks from the big labs are as guilty if not more) Assuming an avg rate of $8/M that's $384k/day or $11m. In the last 30 days. Per year that's $132M... fractional executive, full time founder @sentry labs.sentry.dev like whisky? @peated_app
Shown on screen for about 65 seconds. Not read aloud.
-
David Cramer@zeeg
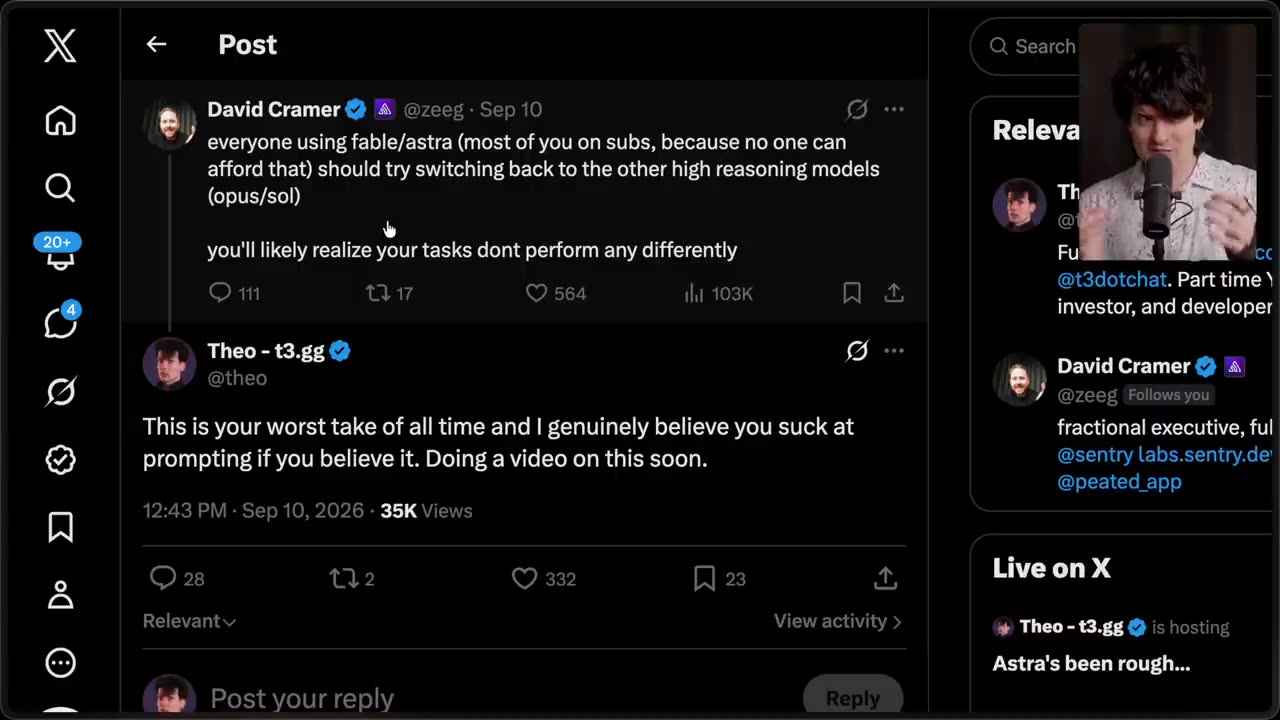
everyone using fable/astra (most of you on subs, because no one can afford that) should try switching back to the other high reasoning models (opus/sol) you'll likely realize your tasks dont perform any differently fractional executive, ful... fractional executive, ful ? sentry labs. sentry.de ? peated_app
Theo read it aloud at 0:40 From David Cramer, aka Zeeg, the founder of Sentry, "Everyone using Fable or Astra, which is most of us on subs because no one can afford it, should try switching back to the other high-reasoning models like Opus and Soul.