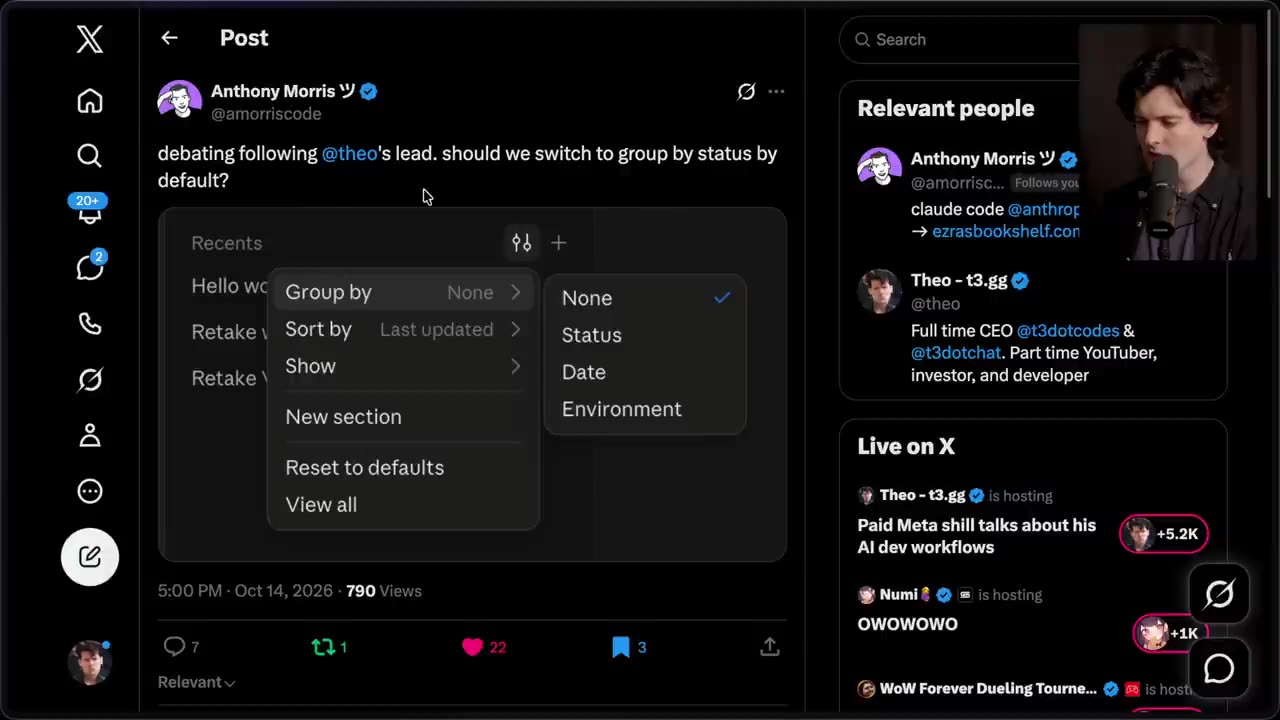
Did
Theo
mention me?

We scan every video for X posts on screen, then check the transcript to see if they were read aloud. See everything Theo showed.

@theo

Yes.

Theo showed your posts 106 times and read 31 aloud.

Post on X ↗
  1. Theo - t3.gg@theo

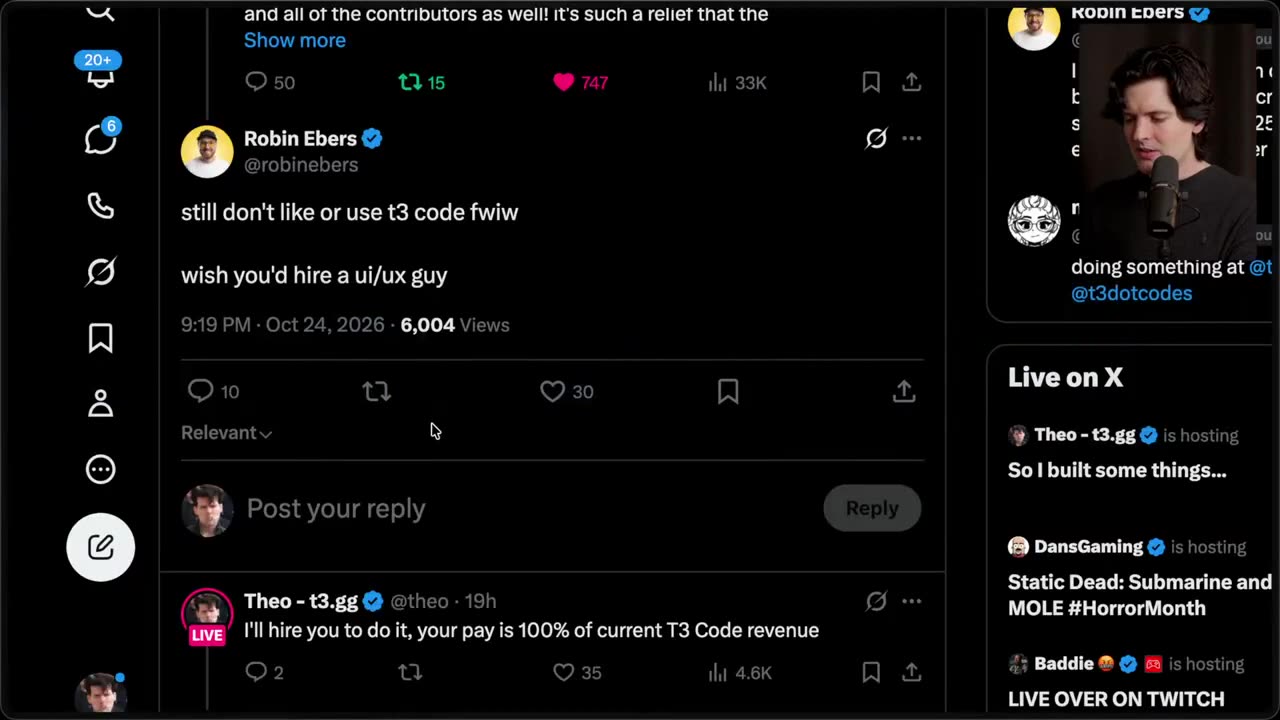
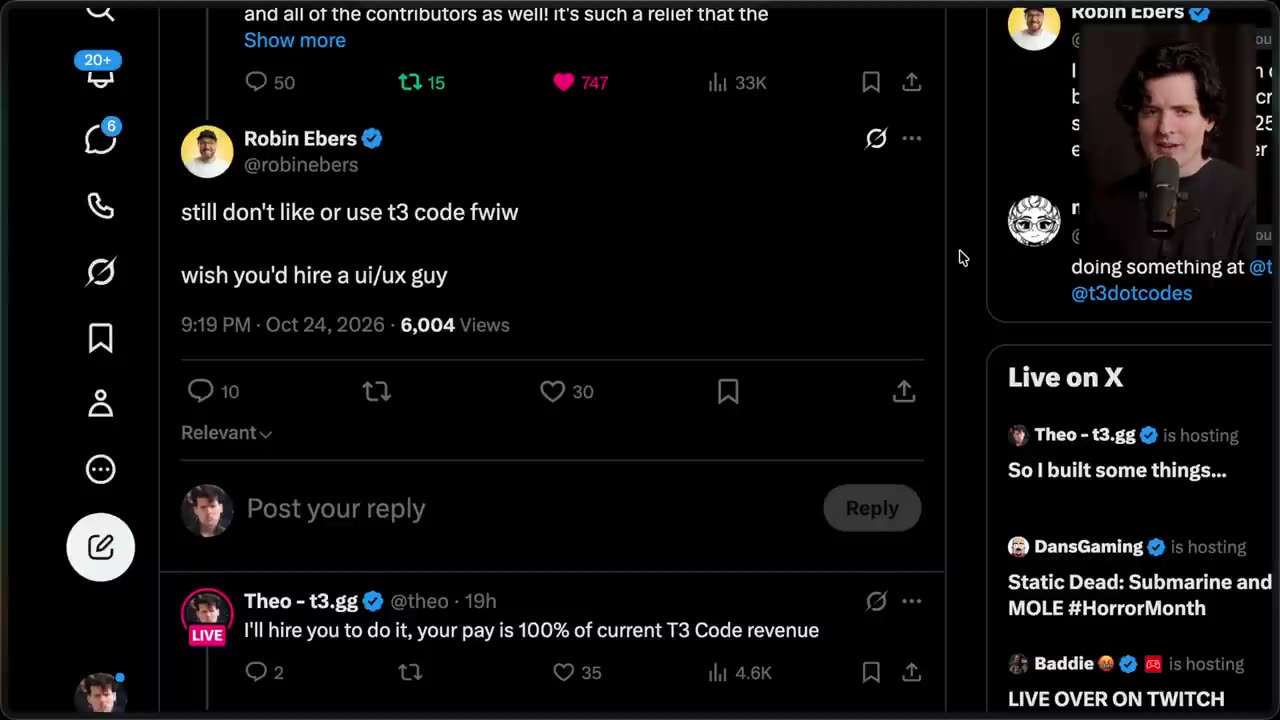
    I'll hire you to do it, your pay is 100% of current T3 Code revenue fwiw I know we can improve here, but I think you're catastrophizing pretty hard. All the ADE's have really rough UI patches, we're at least pretty consistent. PRs welcome Well let's see how this goes

    Theo read it aloud at 5:19
    I said all the agentic dev environments have rough UI patches.
  2. Theo - t3.gg@theo

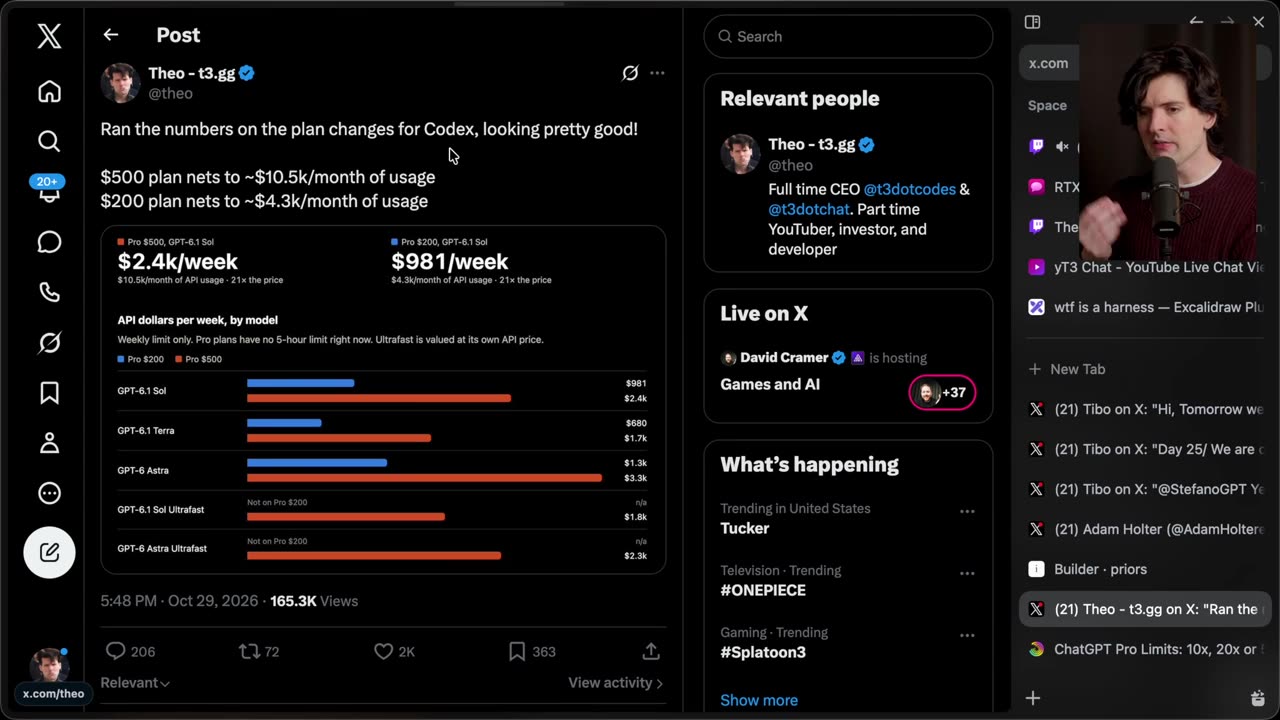
    Ran the numbers on the plan changes for Codex, looking pretty good! $500 plan nets to ~$10.5k/month of usage $200 plan nets to ~$4.3k/month of usage

    Theo read it aloud at 5:17
    And on the $200 plan, you get around 4.3K of usage.
  3. Theo - t3.gg@theo

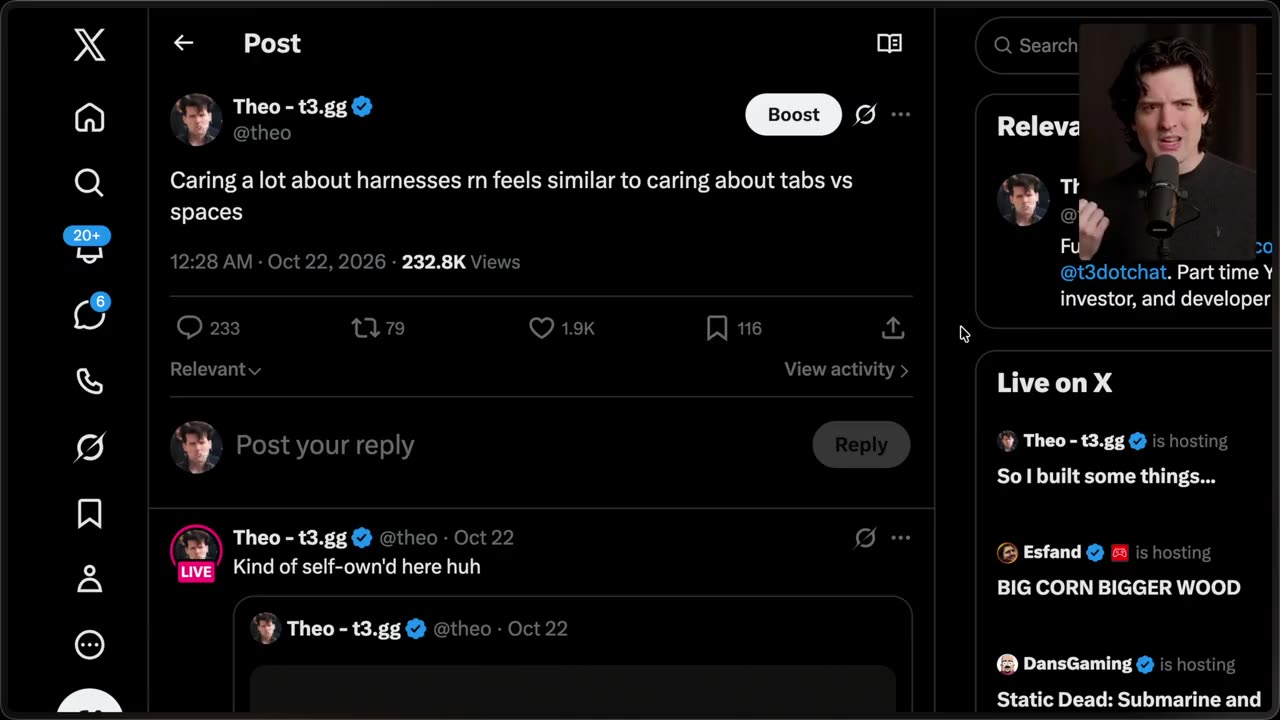
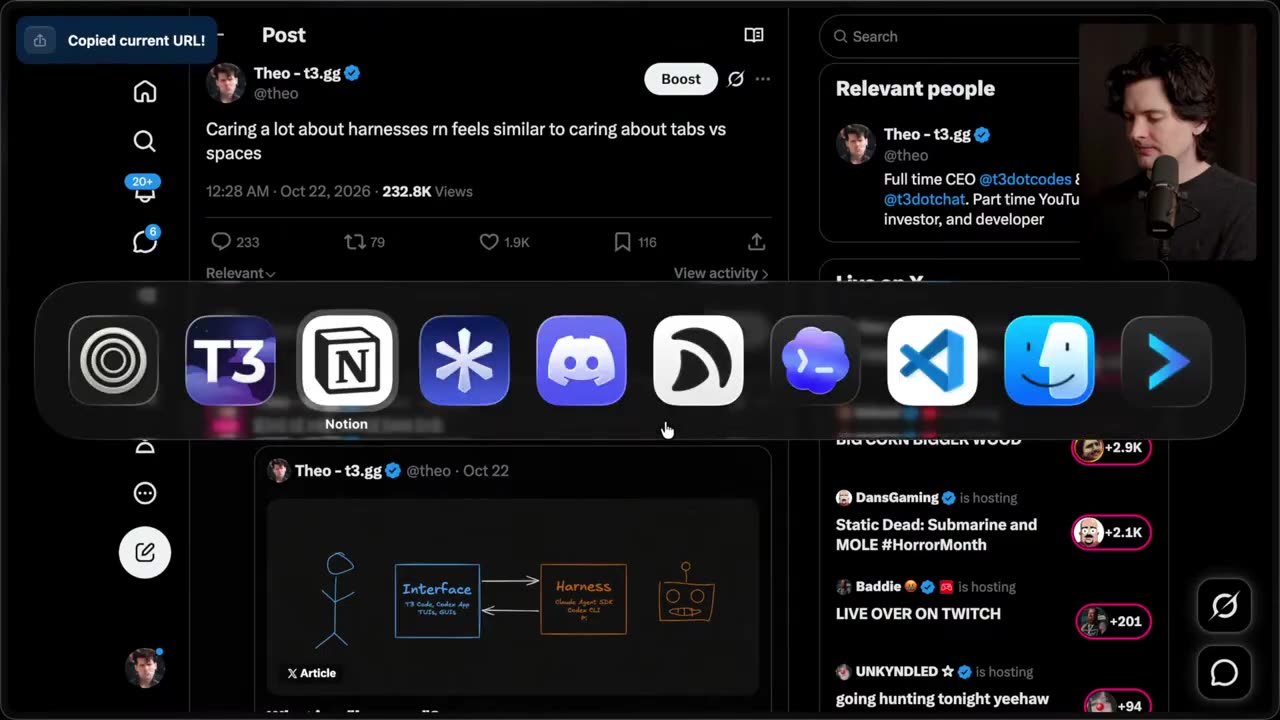
    Caring a lot about harnesses rn feels similar to caring about tabs vs spaces Kind of self-own'd here huh So I built some things...

    Theo read it aloud at 0:08
    They were trying to compare people's preferences in harnesses to fighting about tabs versus spaces.
  4. Theo - t3.gg@theo

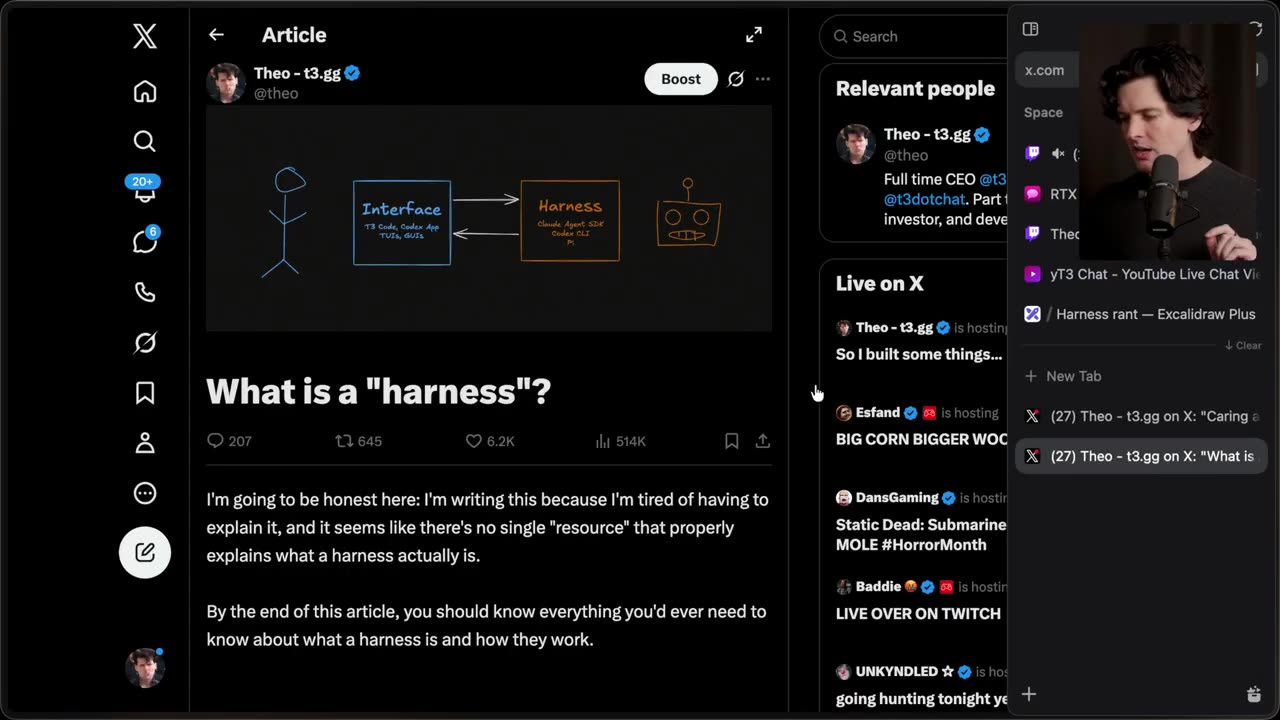
    Article Article Interface T3 Code, Coders App, T3CA, NEXT Harness Claude Agent SDK, Coders CLI What is a "harness"? 207 645 6.2K 514K I'm going to be honest here: I'm writing this because I'm tired of having to explain it, and it seems like there's no single "resource" that properly explains what a harness actually is. By the end of this article, you should know everything you'd ever need to know about what a harness is and how they work. Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer What is a "harness"? I'm going to be honest here: I'm writing this because I'm tired of having to explain it, and it seems like there's no single "resource" that properly explains what a harness actually is. By the end of this article, you should know everything you'd ever need to know about what a harness is and how they work.

    Shown on screen 2 times. Not read aloud.

  5. T3 Code broke me
    Theo - t3.gg@theo

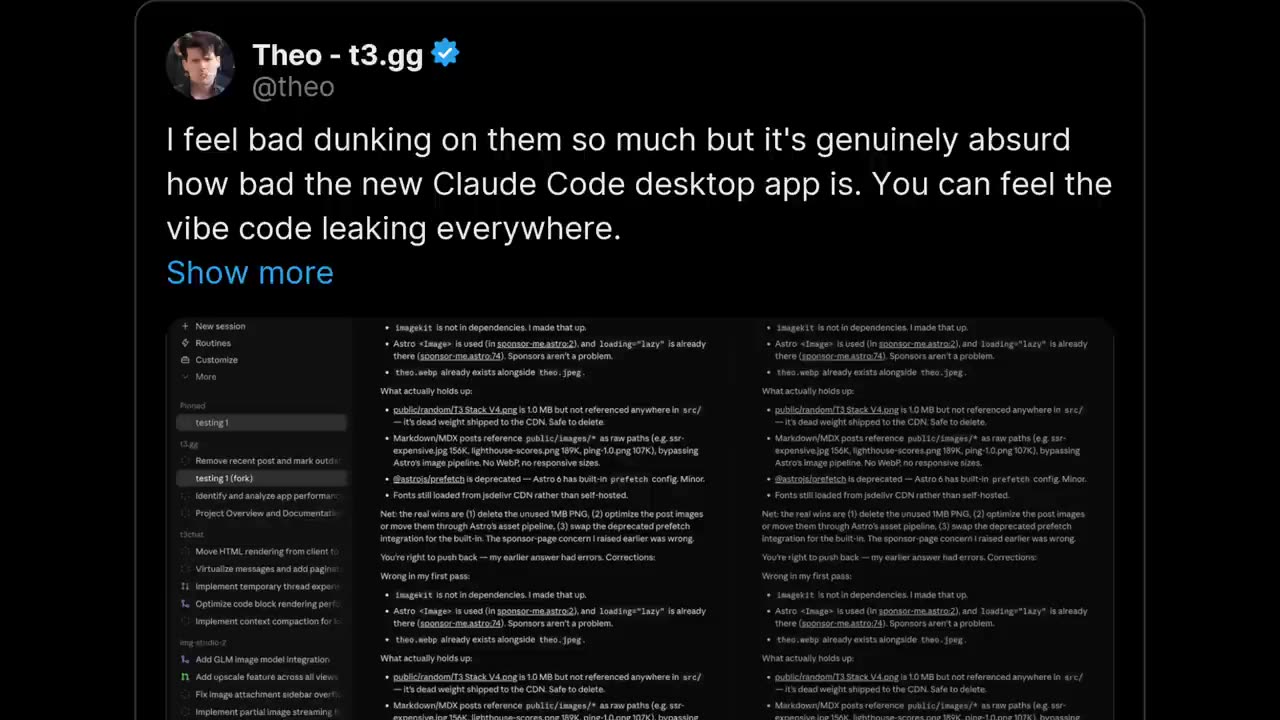
    I feel bad dunking on them so much but it's genuinely absurd how bad the new Claude Code desktop app is. You can feel the vibe code leaking everywhere.

    Shown on screen for about 5 seconds. Not read aloud.

  6. Theo - t3.gg@theo

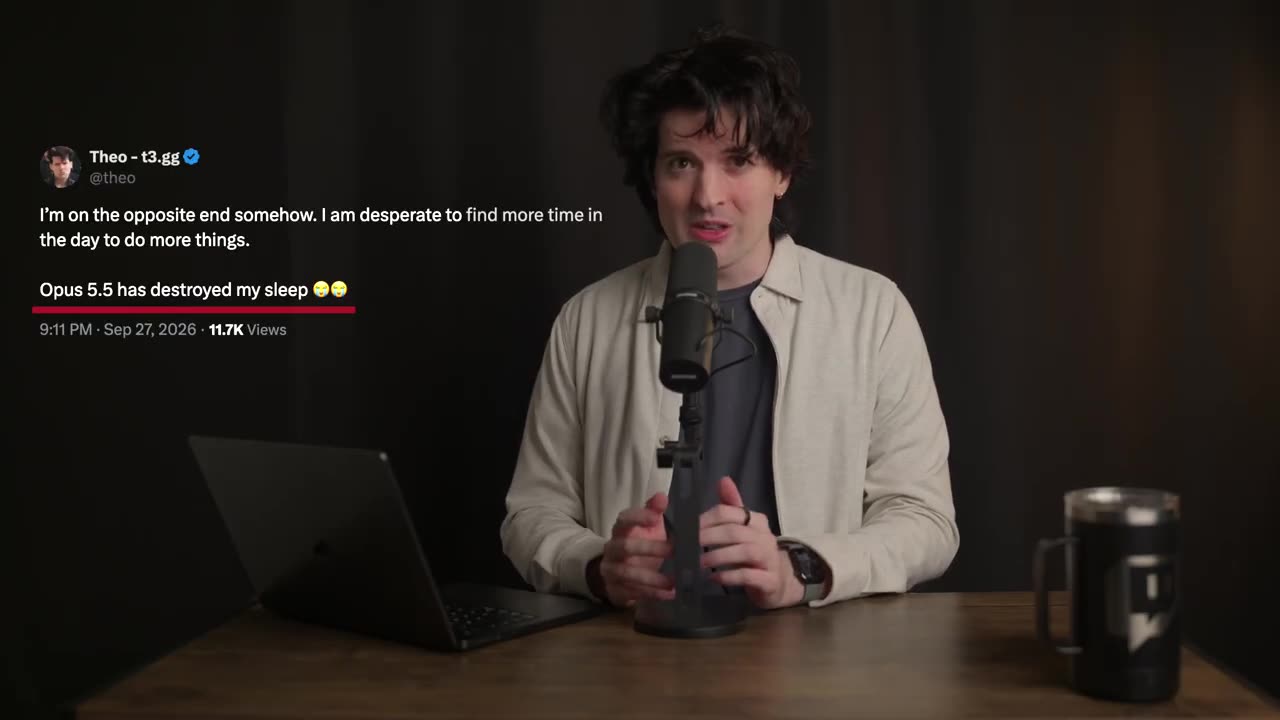
    I'm on the opposite end somehow. I am desperate to find more time in the day to do more things.

    Shown on screen for about 5 seconds. Not read aloud.

  7. Theo - t3.gg@theo

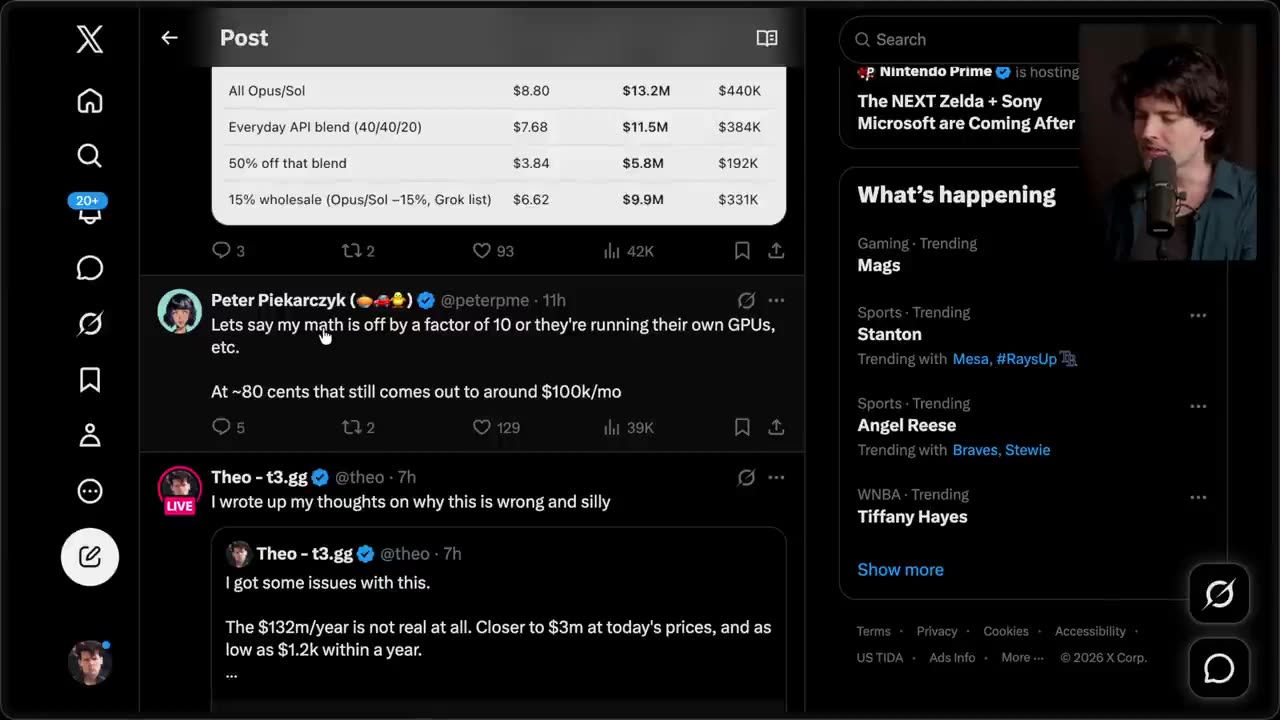
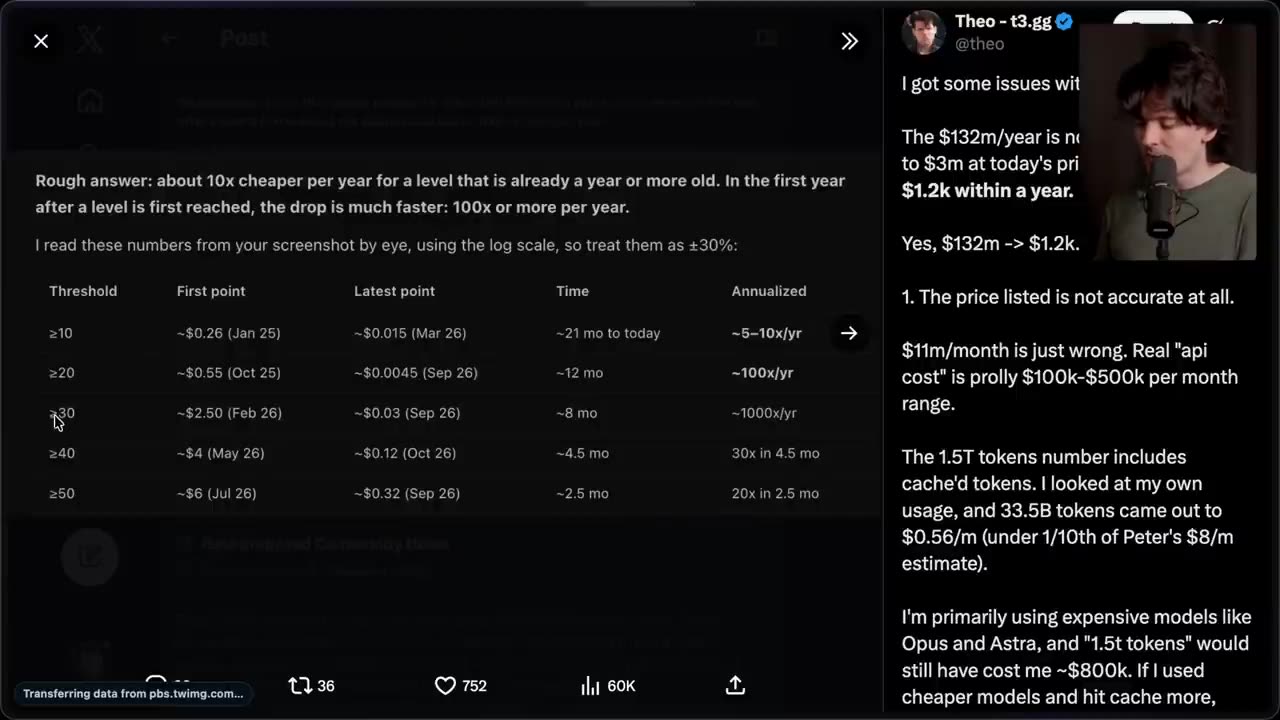
    I wrote up my thoughts on why this is wrong and silly I got some issues with this. At ~80 cents that still comes out to around $100k/mo I got some issues with this. The $132m/year is not real at all. Closer to $3m at today's prices, and as low as $1.2k within a year. ... I got some issues with this. The $132m/year is not real at all. Closer to $3m at today's prices, and as low as $1.2k within a year. ... Rough answer: about 10x cheaper per year for a level that is already a year or more old. In the first year after a level is reached, the drop is much faster: 100x or more per year. I read these numbers from my screenshot by eye, using the log scale, so treat them as ±30%. The $132m/year is not real at all. Closer to $3m at today's prices, and as low as $1.2k within a year. Yes, $132m -> $1.2k. Hear me out. 1. The price listed is not accurate at all. $11m/month is just wrong. Real "api cost" is prolly $100k-$500k per month range. The 1.5T tokens number includes cache'd tokens. I looked at my own usage, and 33.5B tokens came out to $0.56/m (under 1/10th of Peter's $8/m estimate). I'm primarily using expensive models like Opus and Astra, and "1.5t tokens" would still have cost me ~$800k. If I used cheaper models and hit cache more, easily could get as low as $100k. 2. Intelligence is getting cheaper incredibly quickly

    Theo read it aloud at 11:33
    The $132 mil a year that he started with is just it's not real at all.
  8. Theo - t3.gg@theo

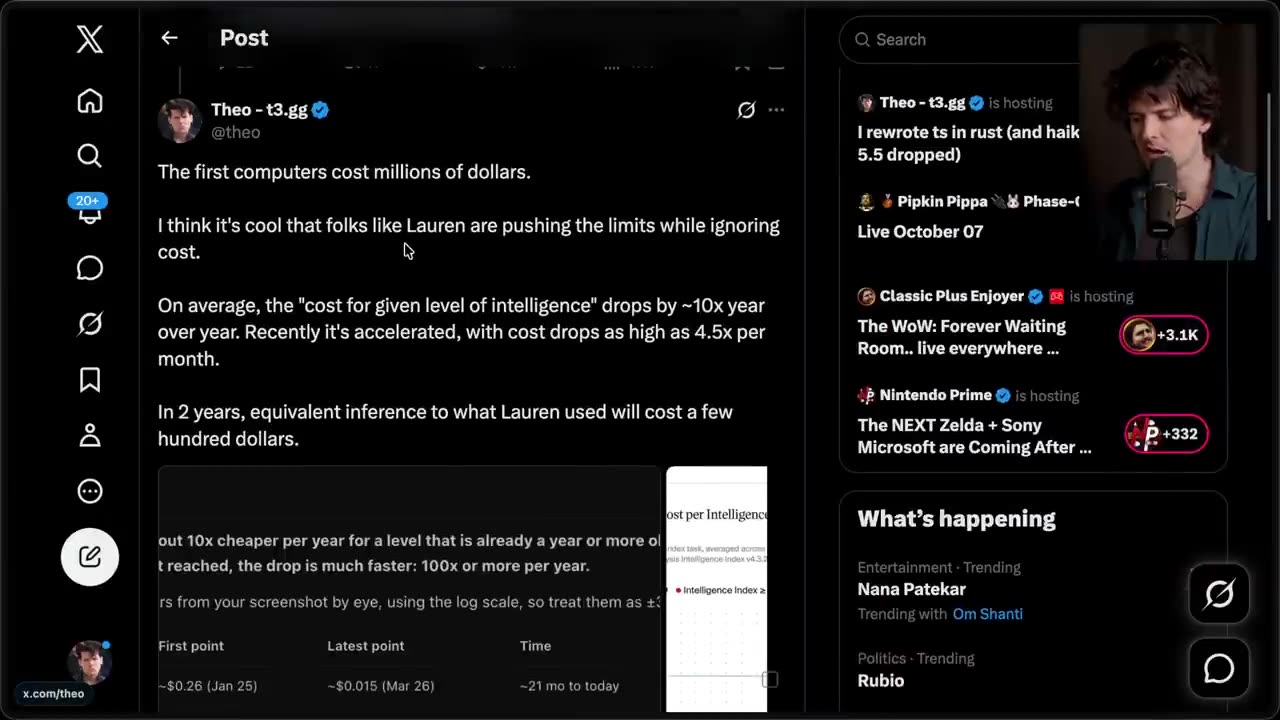
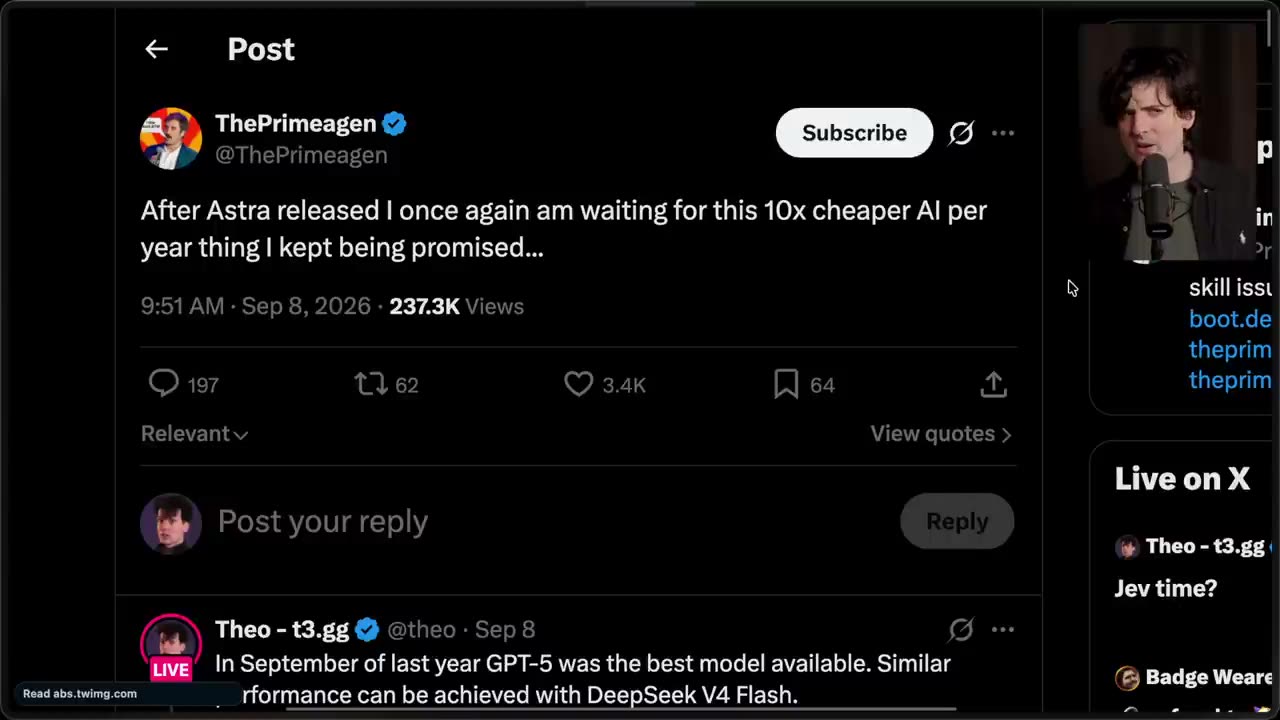
    The first computers cost millions of dollars. I think it's cool that folks like Lauren are pushing the limits while ignoring cost. On average, the "cost for given level of intelligence" drops by ~10x year over year. Recently it's accelerated, with cost drops as high as 4.5x per month. In 2 years, equivalent inference to what Lauren used will cost a few hundred dollars. The first computers cost millions of dollars. I think it's cool that folks like Lauren are pushing the limits while ignoring cost. On average, the "cost for given level of intelligence" drops by ~?x year over year. Recently it's accelerated, with cost drops as high as 4.5x per month. In 2 years, equivalent inference to what Lauren used will cost a few hundred dollars. > you aren't actually getting net net cheaper intelligence everywhere What? Smartest model this time last year was GPT-5 (high). I would take GLM-5.3 Flash or Deepseek 4.1 flash over it any day. Way better intelligence and capability for under 1/10th the price. GPT-6.1 Sol was also a massive price drop, coming in at 1/10th the price of Opus for similar work at a slightly lower success rate. Why wouldn't that trend continue? In September of last year GPT-5 was the best model available. Similar performance can be achieved with DeepSeek V4 Flash. Input tokens (per 1m): $1.25 -> $0.06 (21x cheaper) Output tokens (per 1m): $10 -> $0.18 (55x cheaper) Even with a 3x increase in reasoning tokens, the difference nets out to almost 20x cheaper at the given level of intelligence. > you aren't actually getting net net cheaper intelligence everywhere What? Smartest model this time last year was GPT-5 (high). I would take GLM-5.3 Flash or Deepseek 4.1 flash over it any day. Way better intelligence and capability for under 1/10th the price. GPT-6.1 Sol was also a massive price drop, coming in at 1/10th the price of Opus for similar work at a slightly lower success rate. Why wouldn't that trend continue? I rewrote ts in rust (and haiku) 5.5 dropped Replying to @ThePrimeagen In September of last year GPT-5 was the best model available. Similar performance can be achieved with DeepSeek V4 Flash. Full time CEO @t3dotc @t3dotchat. Part time investor, and developer. Depending on the work you're doing, GLM 5.3 Flash might actually be a better experience than GPT-5 (GLM 5.3 Flash is incredible at agentic work). At its current pricing, GLM 5.3 Flash is around 29x cheaper than GPT-5 in benchmark runs.

    Theo read it aloud at 14:31
    On average, the quote cost for a given level of intelligence drops by around 10x year over year.
  9. Theo - t3.gg@theo

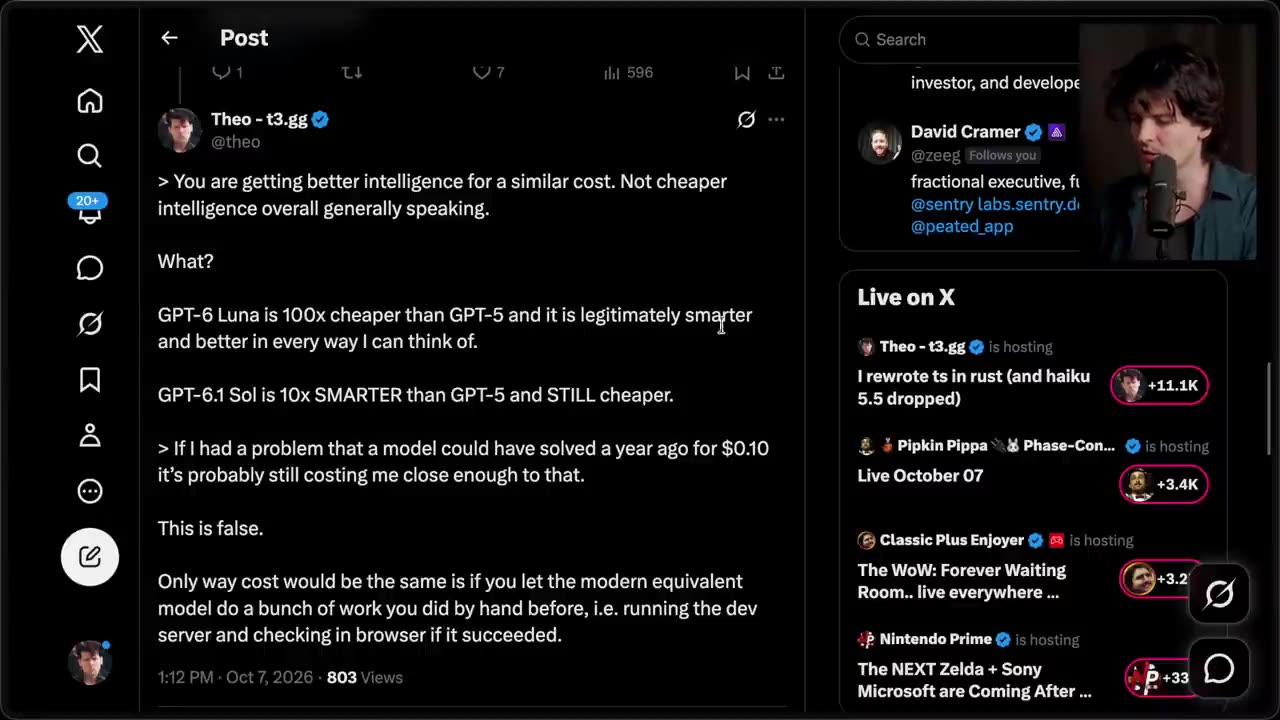
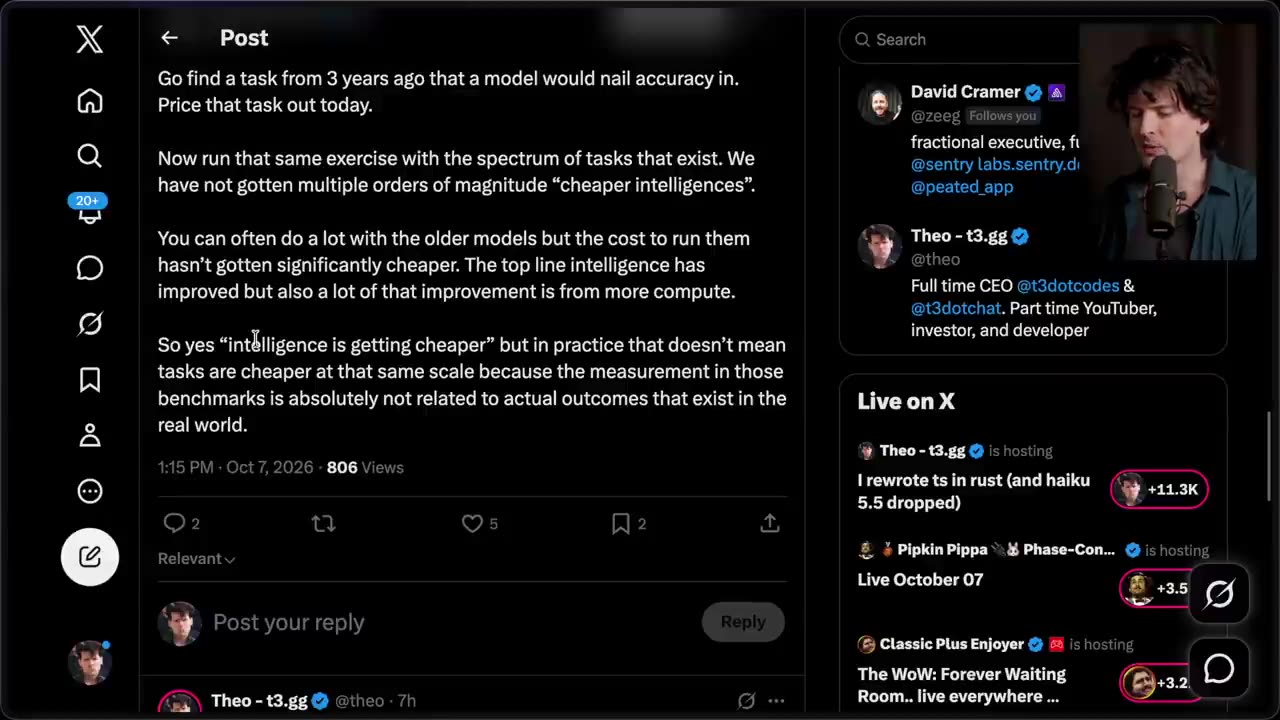
    > You are getting better intelligence for a similar cost. Not cheaper intelligence overall generally speaking.

    Theo read it aloud at 19:49
    Then he says a 1% gain might be a quote 10x Thank you, S John.
  10. Theo - t3.gg@theo

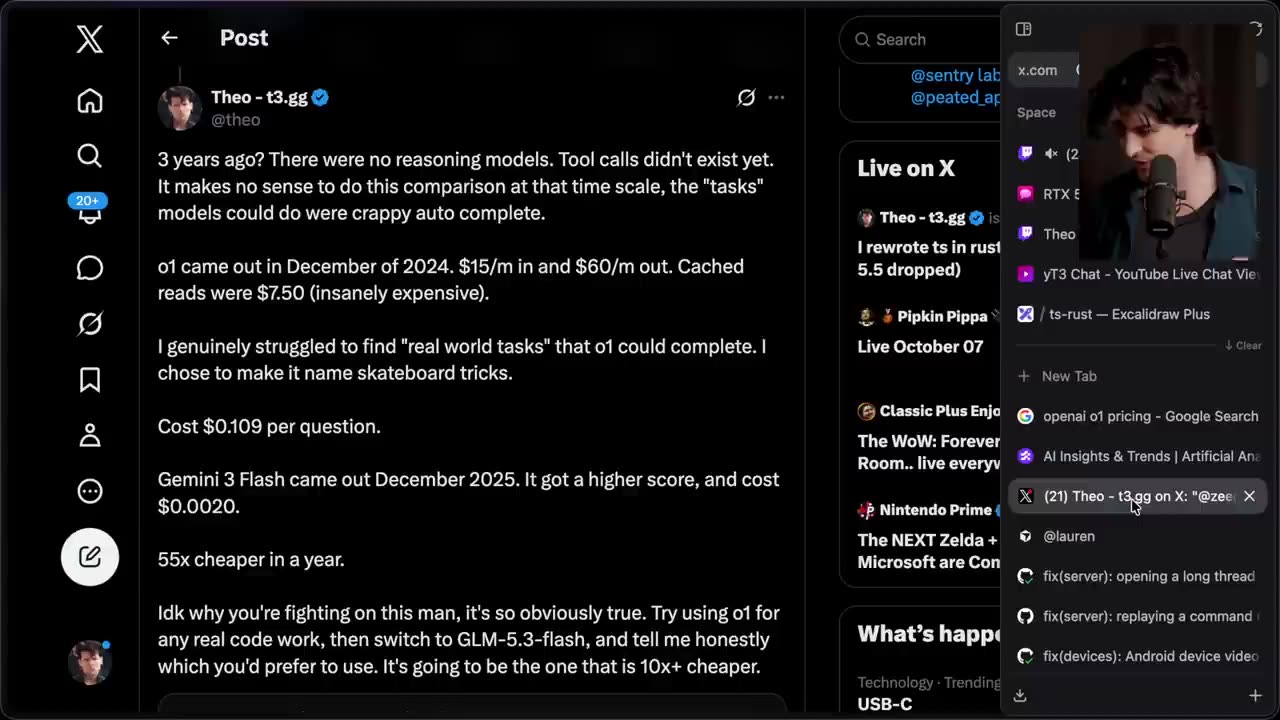
    I rewrote ts in rust (and haiku is 5.5 dropped) 3 years ago? There were no reasoning models. Tool calls didn't exist yet. It makes no sense to do this comparison at that time scale, the "tasks" models could do were crappy auto complete. 3 years ago? There were no reasoning models. Tool calls didn't exist yet. It makes no sense to do this comparison at that time scale, the "tasks" models could do were crappy auto complete. o1 came out in December of 2024. $15/m in and $60/m out. Cached reads were $7.50 (insanely expensive). I genuinely struggled to find "real world tasks" that o1 could complete. I chose to make it name skateboard tricks. Cost $0.109 per question. I genuinely struggled to find "real world tasks" that o1 could complete. I chose to make it name skateboard tricks. Cost $0.109 per question. Gemini 3 Flash came out December 2025. It got a higher score, and cost $0.0020. 55x cheaper in a year. Idk why you're fighting on this man, it's so obviously true. Try using o1 for any real code work, then switch to GLM-5.3-flash, and tell me honestly which you'd prefer to use. It's going to be the one that is 10x+ cheaper.

    Theo read it aloud at 25:50
    Back to what Zig said here.
Show 55 more
  1. Theo - t3.gg@theo

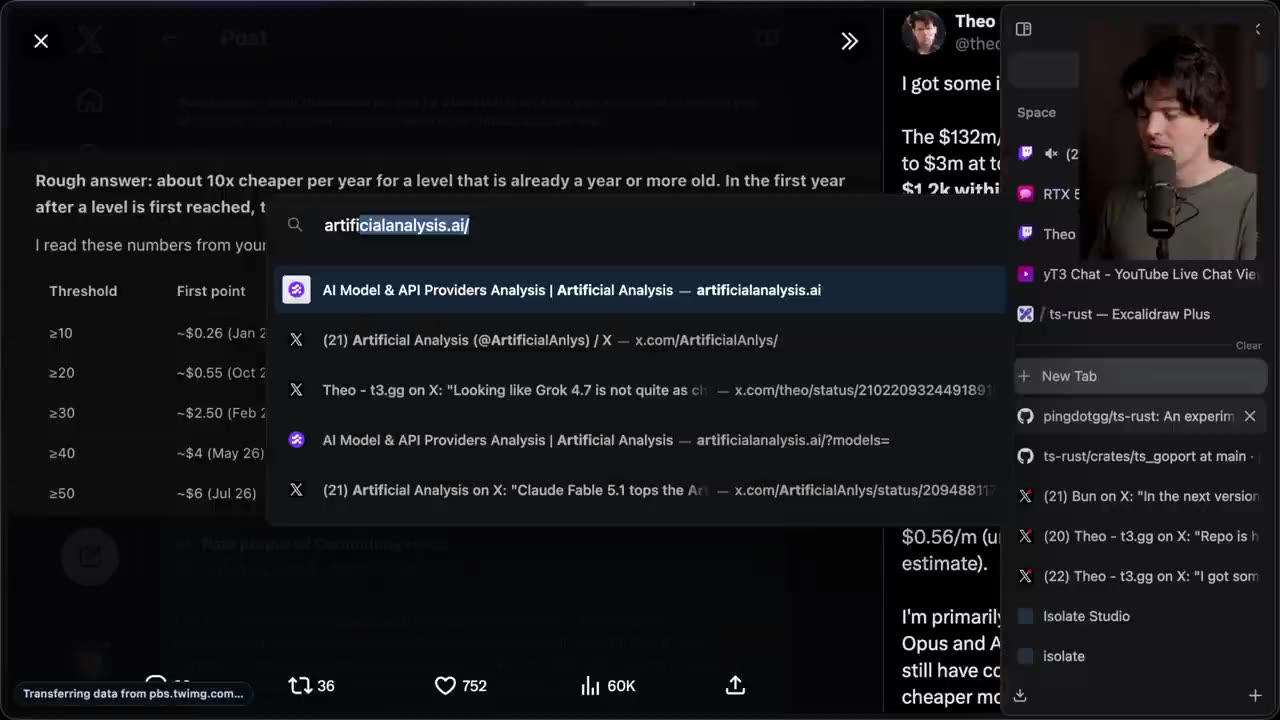
    3 years ago? There were no reasoning models. Tool calls didn't exist yet. It makes no sense to do this comparison at that time scale, the "tasks" models could do crappy auto complete. Sorry to push back so much on this. I know you're smart and I respect the hell out of you, which is why it's so genuinely confusing to me that you have this take. A year ago, the flow was: - highlight text in editor - cmd+k "make it do (something else)" - Read the code by hand I'm also pissed about Gemini 2 Flash being dropped. We used it for a ton of stuff. I've found Luna and GLM-5.3 Flash to be meaningfully better for similar stuff, esp. when structured outputs/tool calls matter at all The first computers cost millions of dollars. I think it's cool that folks like Lauren are pushing the limits while ignoring cost. On average, the "cost for given level of intelligence" drops by ~10x year over year. Recently it's accelerated, with cost drops as high as 4.5x per... The first computers cost millions of dollars. I think it's cool that folks like Lauren are pushing the limits while ignoring cost. Full time CEO @ t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer Agreed! I got some issues with this. I got some issues with this. The $132m/year is not real at all. Closer to $3m at today's prices, and as low as $1.2k within a year. Yes, $132m -> as low as $1.2k. Hear me out. 1. The price listed is not accurate at all. $11m/month is just wrong. Real "api cost" is prolly $100k-$500k Yes, \$132m -> \$1.2k. Hear me out. 1. The price listed is not accurate at all. \$11m/month is just wrong. Real \"api cost\" is prolly \$100k-\$500k The $132m/year is not real at all. Closer to $3m at today's prices, and as low as $1.2k within a year. Yes, $132m -> $1.2k. Hear me out. 1. The price listed is not accurate at all. $11m/month is just wrong. Real "api cost" is prolly $100k-$500k Rough answer: about 10x cheaper per year for a level that is already a year or more old. In the first year after a level is first reached, the drop is much faster: 100x or more per year. I read these numbers from my screenshot by, using the log scale, so treat them as ±30%: Threshold | First point | Latest point | Time | Annualized ≥10 | ~$0.26 (Jan 25) | ~$0.015 (Mar 26) | ~21 mo to today | ~$5-10/yr ≥20 | ~$0.55 (Oct 25) | ~$0.0045 (Sep 26) | ~12 mo | ~100x/yr ≥30 | ~$2.50 (Feb 26) | ~$0.03 (Sep 26) | ~8 mo | ~1000x/yr ≥40 | ~$4 (May 26) | ~$0.12 (Oct 26) | ~4.5 mo | 30x in 4.5 mo ≥50 | ~$6 (Jul 26) | ~$0.32 (Sep 26) | ~2.5 mo | 20x in 2.5 mo Rough answer: about 10x cheaper per year for a level that is already a year or more old. In the first year after a level is first reached, the drop is much faster: 100x or more per year. I read these numbers from your screenshot by eye, using the log scale, so treat them as ±30%: Threshold First point Latest point Time Annualized ≥10 -$0.26 (Jan 25) -$0.015 (Mar 26) -21 m to today -5-10x/yr ≥20 -$0.55 (Oct 25) -$0.0045 (Sep 26) -12 mo -100x/yr ≥30 -$2.50 (Feb 26) -$0.03 (Sep 26) -8 mo -1000x/yr ≥40 -$4 (May 26) -$0.12 (Oct 26) -4.5 mo 30x in 4.5 mo ≥50 -$6 (Jul 26) -$0.32 (Sep 26) -2.5 mo 20x in 2.5 mo

    Theo read it aloud at 33:00
    are obviously wrong, or maybe just seem like they might not be right, maybe just screenshot the tweet and throw it at Claude or Codex and ask them to verify the numbers, because even the dumbest AI models nowadays could probably explain to you
  2. Theo - t3.gg@theo

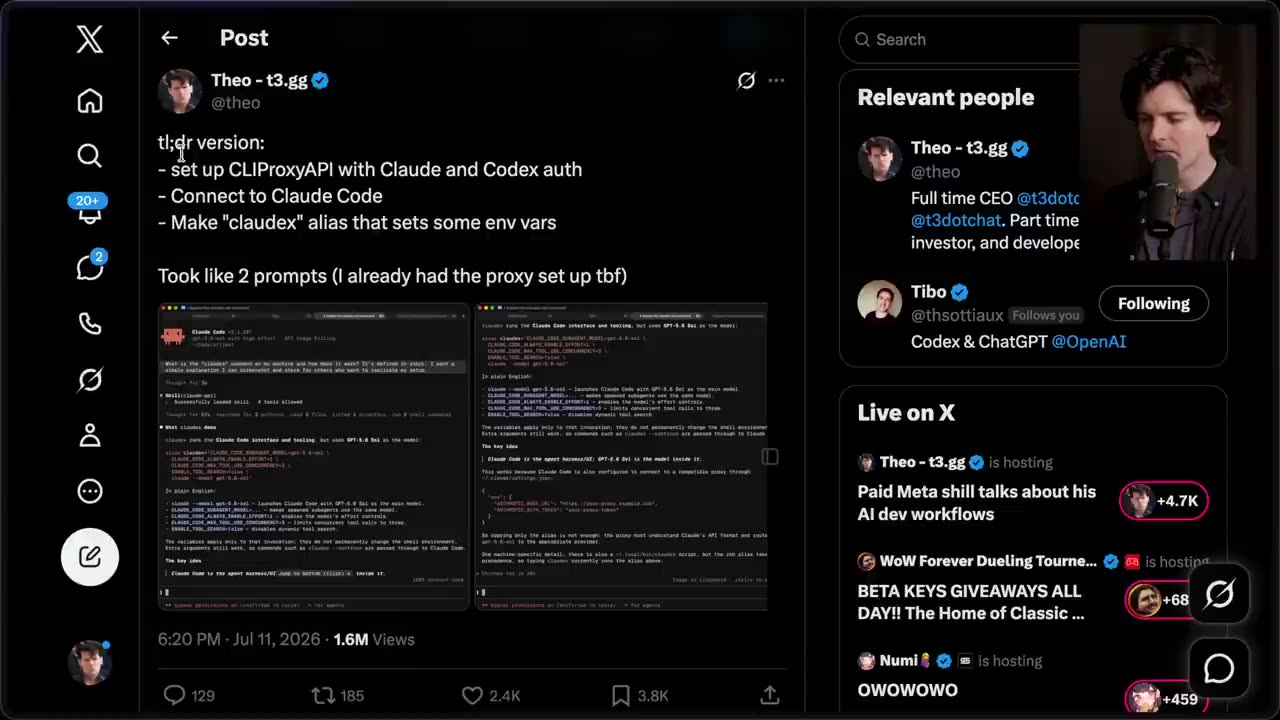
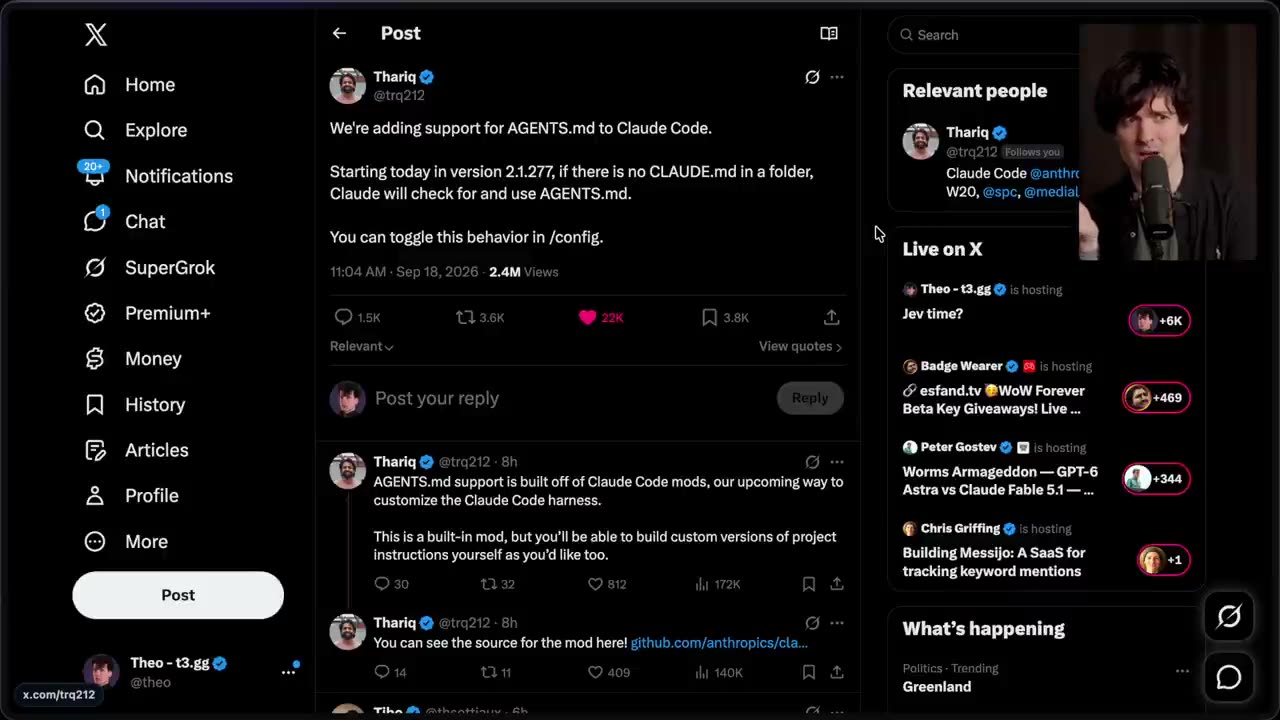
    tl;dr version: tl;dr version: - set up CLIProxyAPI with Claude and Codex auth - Connect to Claude Code - Make "claudex" alias that sets some env vars Took like 2 prompts (I already had the proxy set up tfb) Replying to @thsottiaux If this gets blocked, I owe you a reset.

    Theo read it aloud at 9:13
    Tibo actually quote tweeted this saying that it is a blessed solution and if this does get you blocked, then he owes you a
  3. Theo - t3.gg@theo

    Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer

    Shown on screen for about 5 seconds. Not read aloud.

  4. Theo - t3.gg@theo

    Proudly Sponsored By WorkOS BLACK SMITH Browserbase CodeRabbit So I built some things... Everything got pwn'd. I tried to warn you.

    Shown on screen for about 5 seconds. Not read aloud.

  5. Theo - t3.gg@theo

    Article Theo - t3.gg @theo Boost What is a "harness"? 207 645 6.2K 514K I'm going to be honest here: I'm writing this because I'm tired of having to explain it, and it seems like there's no single "resource" that properly explains what a harness actually is. By the end of this article, you should know everything you'd ever need to know about what a harness is and how they work. Theo - t3.gg is hosting Space Theo - t3.gg is hosting So I built some things... Caring a lot about harnesses rn feels similar to caring about tabs vs spaces Kind of self-own'd here huh

    Theo read it aloud at 1:17:59
    So, I was scrolling Twitter a few days ago, and I saw this absolute dumbass posting about how harnesses don't matter.
  6. Theo - t3.gg@theo

    Caring a lot about harnesses rn feels similar to caring about tabs vs spaces Kind of self-own'd here huh So I built some things... Live for a bit around 4:30? Why not Delaying to 5pm because I'm late and forgot I had to film something else first I don't think you guys appreciate just how bad Gemini is at agentic work. The hallucination rates are truly surreal. I'll hire you to do it, your pay is 100% of current T3 Code revenue

    Shown on screen 3 times. Not read aloud.

  7. Theo - t3.gg@theo

    I'll hire you to do it, your pay is 100% of current T3 Code revenue fwii I know we can improve here, but I think you're catastrophizing pretty hard. All the ADE's have really rough UI patches, we're at least pretty consistent. Also not sure if you've tried since OV2 but there was a LOT of polish during that overhaul fwiw I know we can improve here, but I think you're catastrophizing pretty hard. All the ADE's have really rough UI patches, we're at least pretty consistent. PRs welcome Well let's see how this goes

    Theo read it aloud at 2:40:19
    But when I saw this reply from Robin, I knew I had to do something.
  8. Theo - t3.gg@theo

    To people who think that Windows ARM has a chance, I have a simple question: To people who think that Windows ARM has a chance, I have a simple question: What do you think is more likely? 1. Microsoft competently ports 20+ years of tech debt to ARM 2. Intel gets slightly better at making chips

    Shown on screen for about 11 seconds. Not read aloud.

  9. Theo - t3.gg@theo

    Lakebed, Postplan, and Shoo will be down indefinitely until Railway gets their shit fixed and I can actually redeploy them with rolled keys. Had to take everything I host on Railway offline manually while waiting for an update.

    Shown on screen for about 5 seconds. Not read aloud.

  10. Theo - t3.gg@theo

    @theo @maria_rcks @jullerino it's slow on a Fire TV stick, but it runs 🚀

    Shown on screen for about 5 seconds. Not read aloud.

  11. Theo - t3.gg@theo

    Lakebed, Postplan, and Shoo will be down indefinitely until Railway getss their shit fixed and I can actually redeploy them with rolled keys. Had to take everything I host on Railway offline manually while waiting for an update. Lakebed, Postplan, and Shoo will be down indefinitely until Railway gets their shit fixed and I can actually redeploy them with rolled keys. Incidents happen. I understand. Blocking deploys so we can roll keys without downtime is unacceptable. I'm disappointed in Railway.

    Shown on screen 3 times. Not read aloud.

  12. Theo - t3.gg@theo

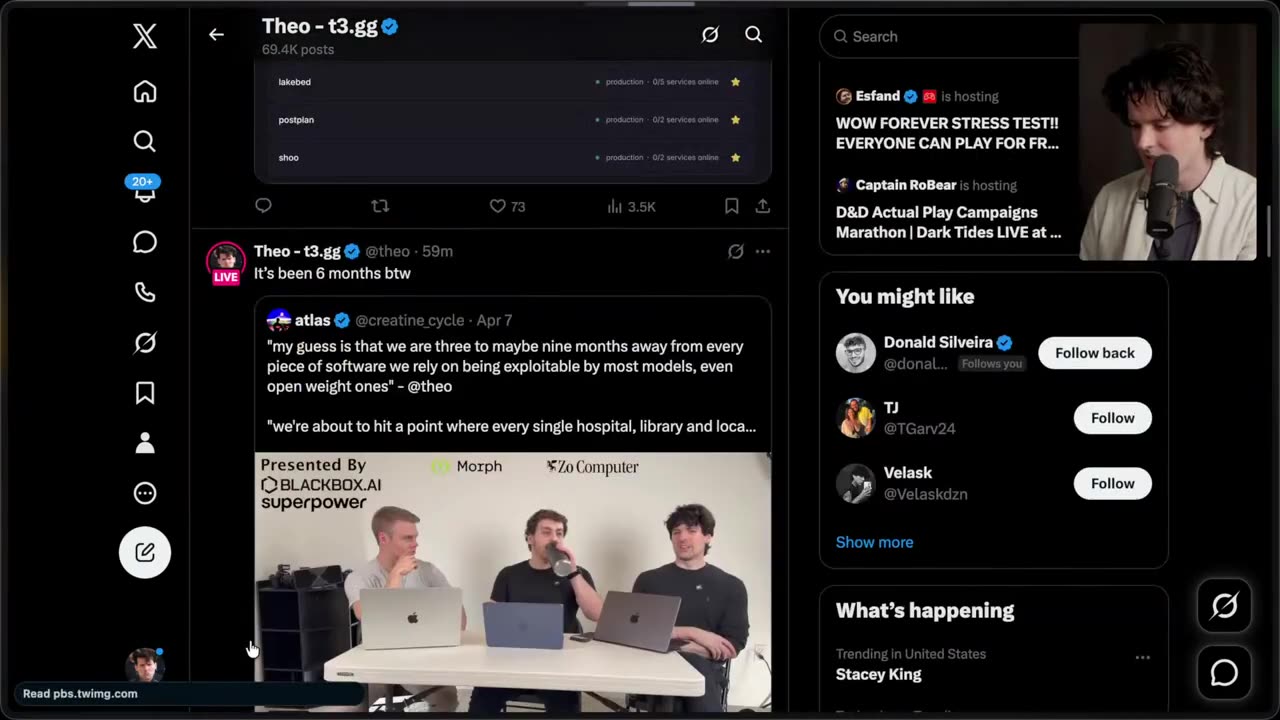
    It's been 6 months btw

    Shown on screen for about 34 seconds. Not read aloud.

  13. Theo - t3.gg@theo

    Proudly Sponsored By WorkOS BLACK SMITH Browserbase CodeRabbit Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer Opus 5.5 is proof that the world does actually need smarter models. Lakebed, Postplan, and Shoo will be down indefinitely until Railway gets their shit fixed and I can actually redeploy them with rolled keys. Incidents happen. I understand. If your reason for leaving is stability... It has been 16 hours since I was able to update my deployments on Railway 😓

    Shown on screen 5 times. Not read aloud.

  14. theo@theo

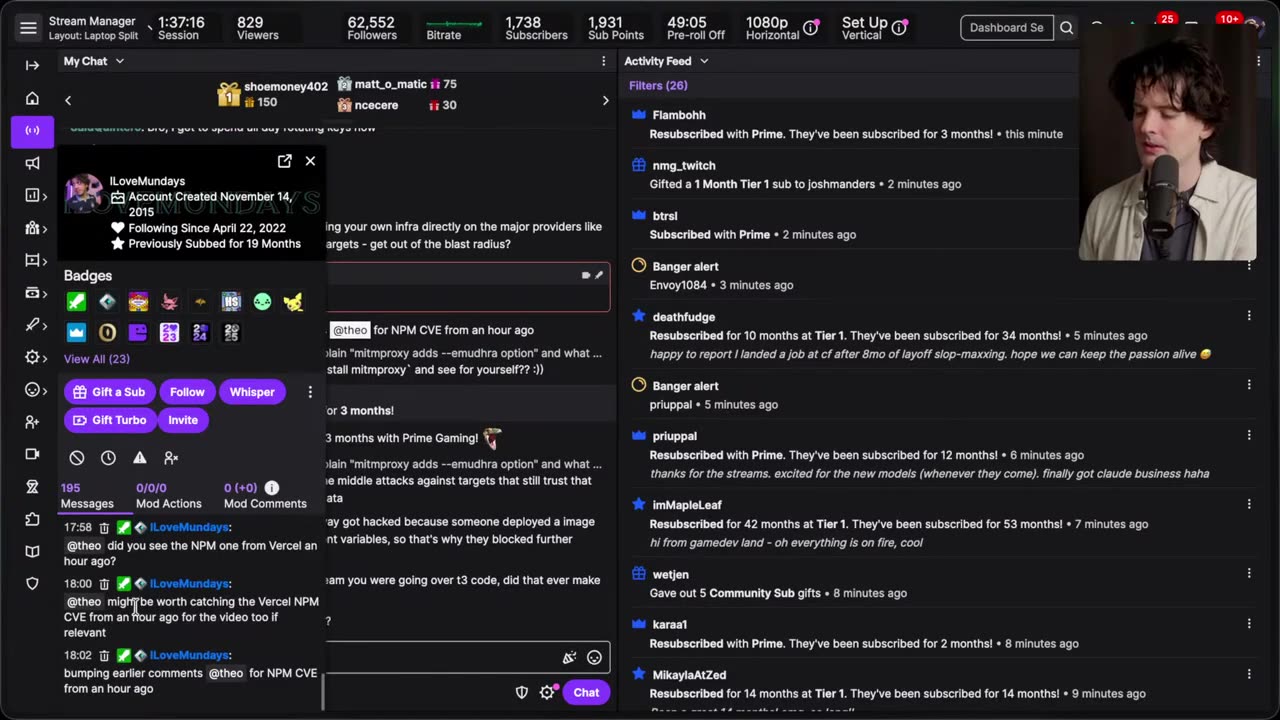
    for NPM CVE from an hour ago did you see the NPM one from Vercel an hour ago might be worth catching the Vercel NPM CVE from an hour ago for the video too if relevant ?

    Theo read it aloud at 1:37:15
    I'm still so fucking there's an NPM CV two separate from node oh no this is just part of the node one they just reported on it because they are protecting it
  15. Theo - t3.gg@theo

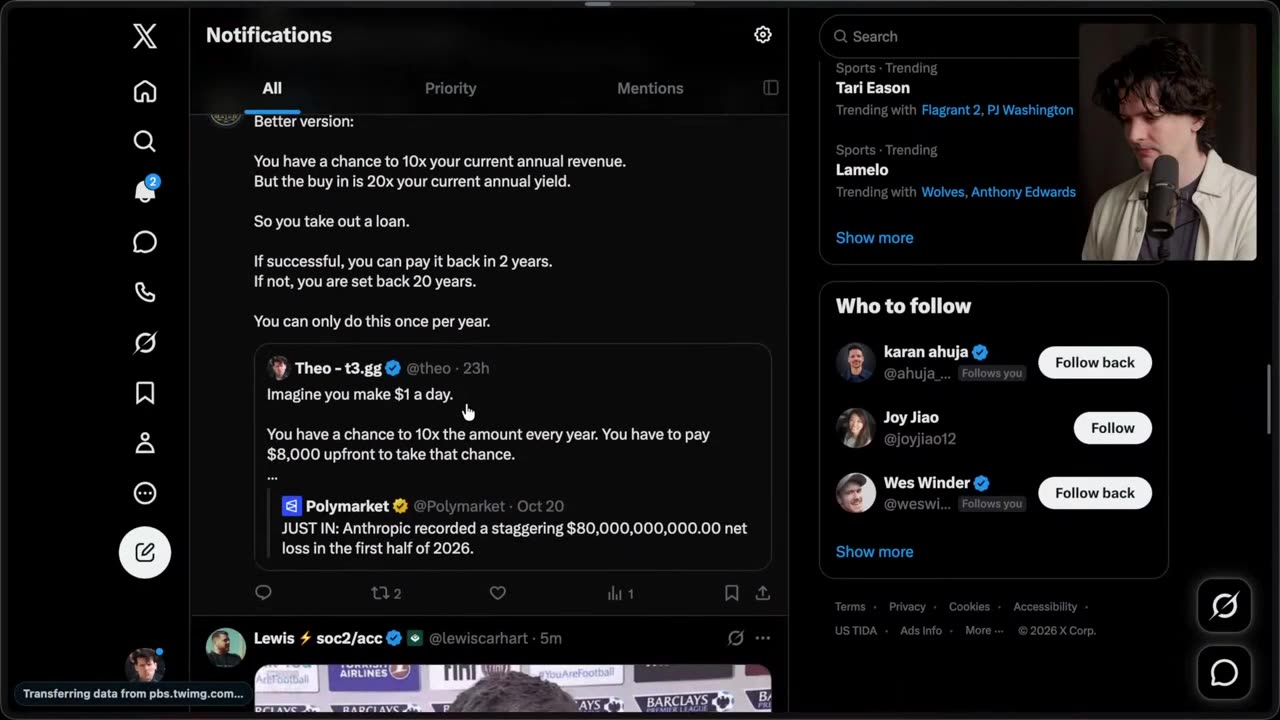
    Imagine you make $1 a day. You have a chance to 10x the amount every year. You have to pay $8,000 upfront to take that chance. ... It has been 16 hours since I was able to update my deployments on Railway Lakebed, Postplan, and Shoo will be down indefinitely until Railway gets their shit fixed and I can actually redeploy them with rolled keys.

    Theo read it aloud at 1:52:59
    It's been down for 17 hours.
  16. Theo - t3.gg@theo

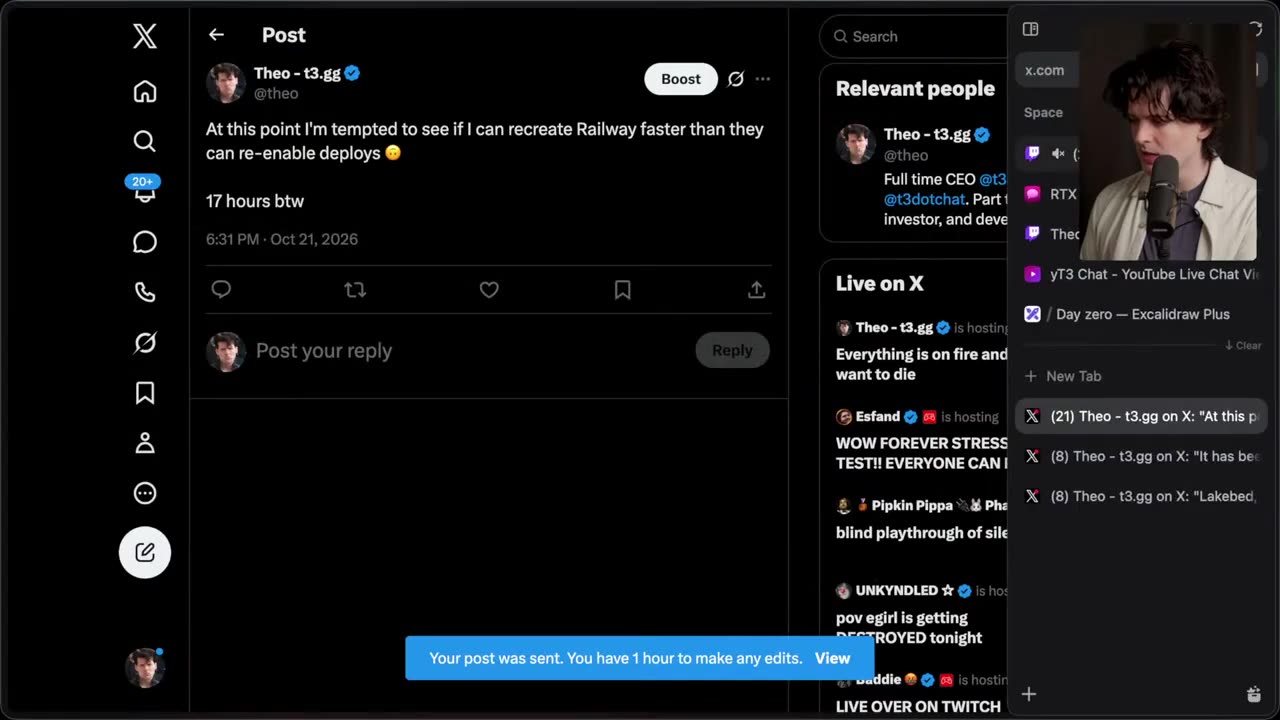
    At this point I'm tempted to see if I can recreate Railway faster than they can re-enable deploys 🫠 It has been 16 hours since I was able to update my deployments on Railway Lakebed, Postplan, and Shoo will be down indefinitely until Railway gets their shit fixed and I can actually redeploy them with rolled keys.

    Theo read it aloud at 2:05:49
    Can I rebuild Railway faster than Railway can come back?
  17. ?@theo

    @Theo would you access it? On the dashboard I can still

    Shown on screen for about 5 seconds. Not read aloud.

  18. Theo - t3.gg@theo

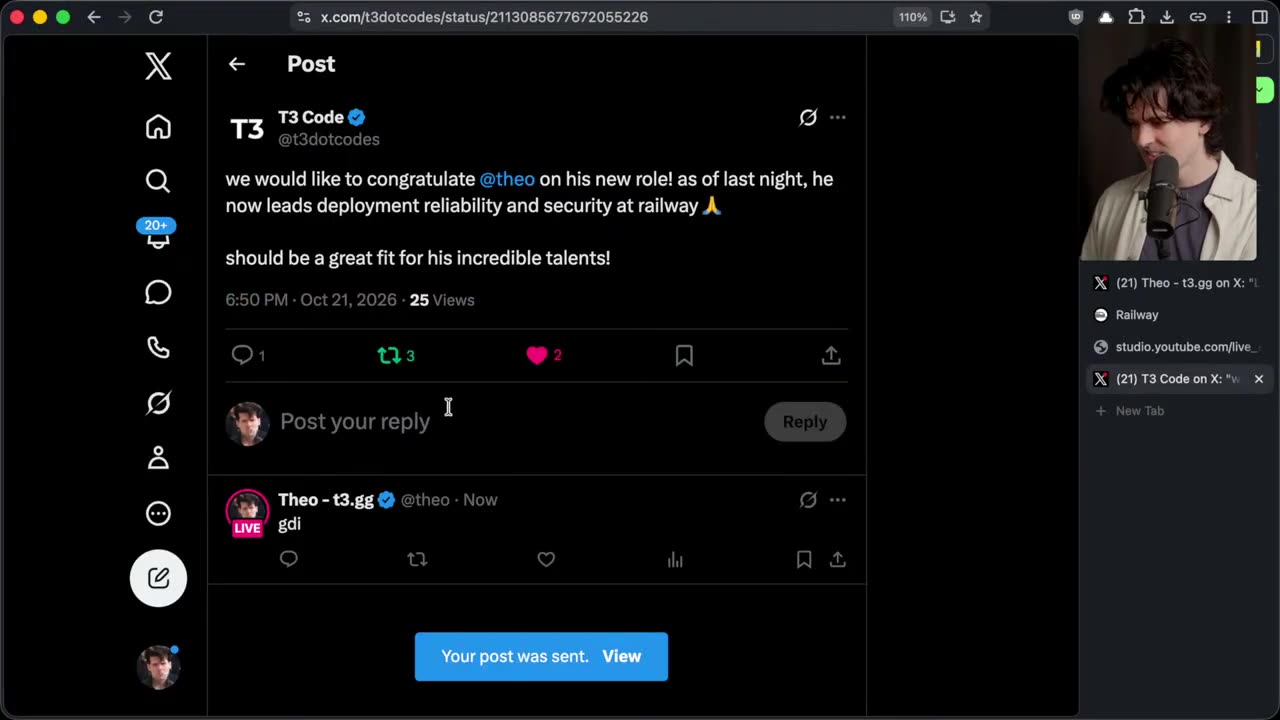
    gdi

    Shown on screen 2 times. Not read aloud.

  19. Theo - t3.gg@theo

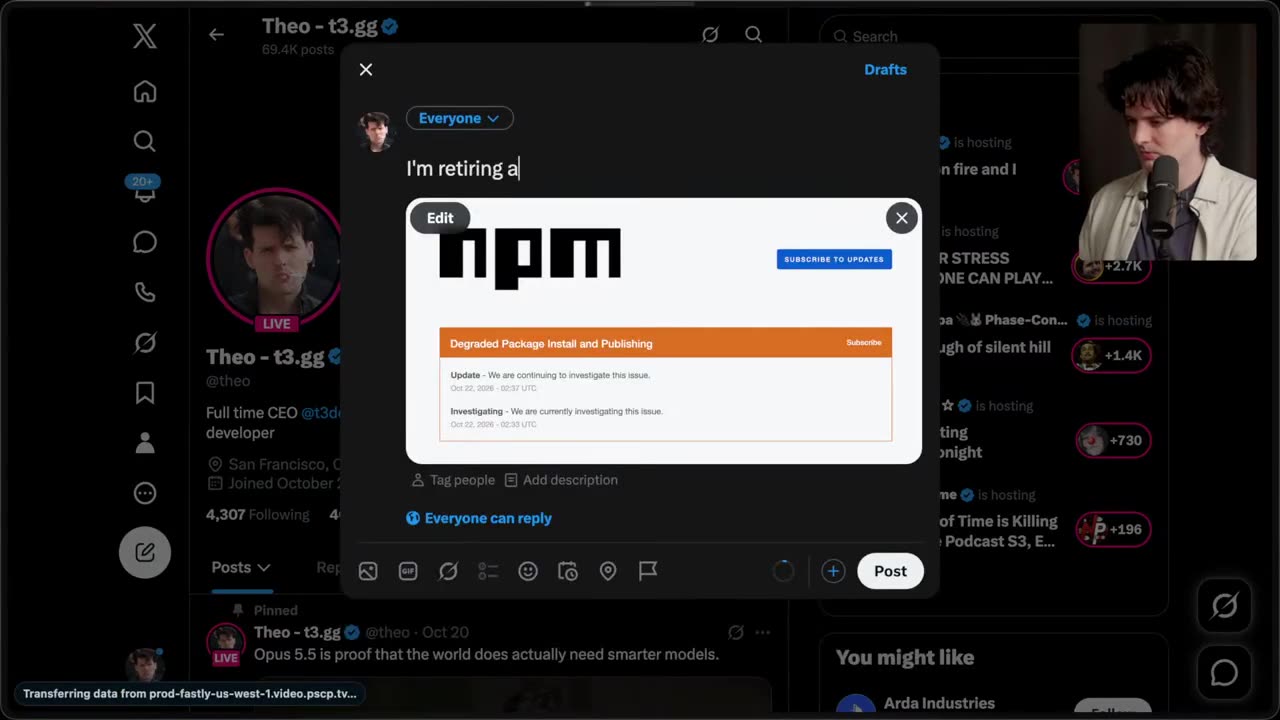
    LIVE Opus 5.5 is proof that the world does actually need smarter models. Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer Opus 5.5 is proof that ? Everything is on fire and we want to die (21) Theo - t3.gg (@theo) / X

    Shown on screen for about 7 seconds. Not read aloud.

  20. Theo - t3.gg@theo

    THIS HAS GONE TOO FAR. ITS TIME TO PACE THE FRONTIER. @DarioAmodei @sama @elonmusk @theo THIS HAS GONE TOO FAR. ITS TIME TO PACE THE FRONTIER.

    Shown on screen 2 times. Not read aloud.

  21. Theo - t3.gg@theo

    Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer y'know, maybe I prefer this Tibo after all

    Shown on screen for about 5 seconds. Not read aloud.

  22. Theo - t3.gg@theo

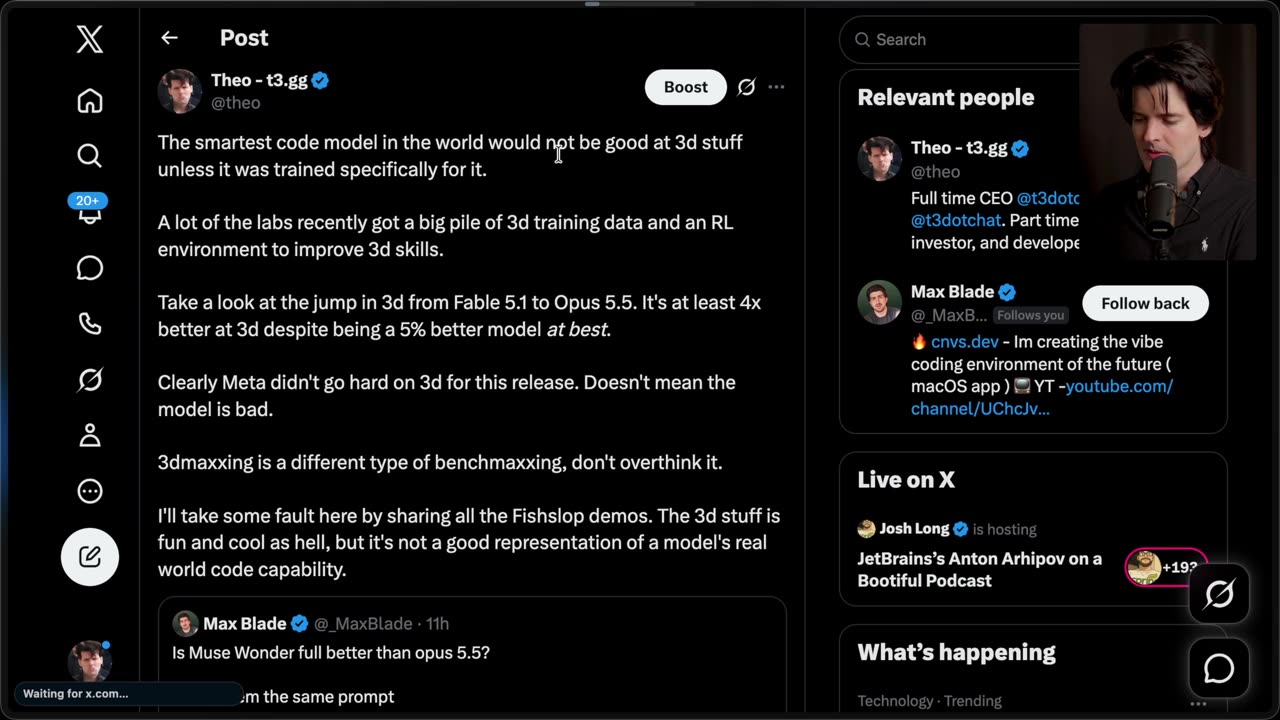
    The smartest code model in the world would not be good at 3d stuff unless it was trained specifically for it. A lot of the labs recently got a big pile of 3d training data and an RL environment to improve 3d skills. Take a look at the jump in 3d from Fable 5.1 to Opus 5.5. It's at least 4x better at 3d despite being a 5% better model at best. Clearly Meta didn't go hard on 3d for this release. Doesn't mean the model is bad. 3dmaxxing is a different type of benchmaxxing, don't overthink it. I'll take some fault here by sharing all the Fishslop demos. The 3d stuff is fun and cool as hell, but it's not a good representation of a model's real world code capability.

    Theo read it aloud at 6:31
    Fable obviously destroyed it, but Fable's 3D capability isn't quite as high.
  23. Theo - t3.gg@theo

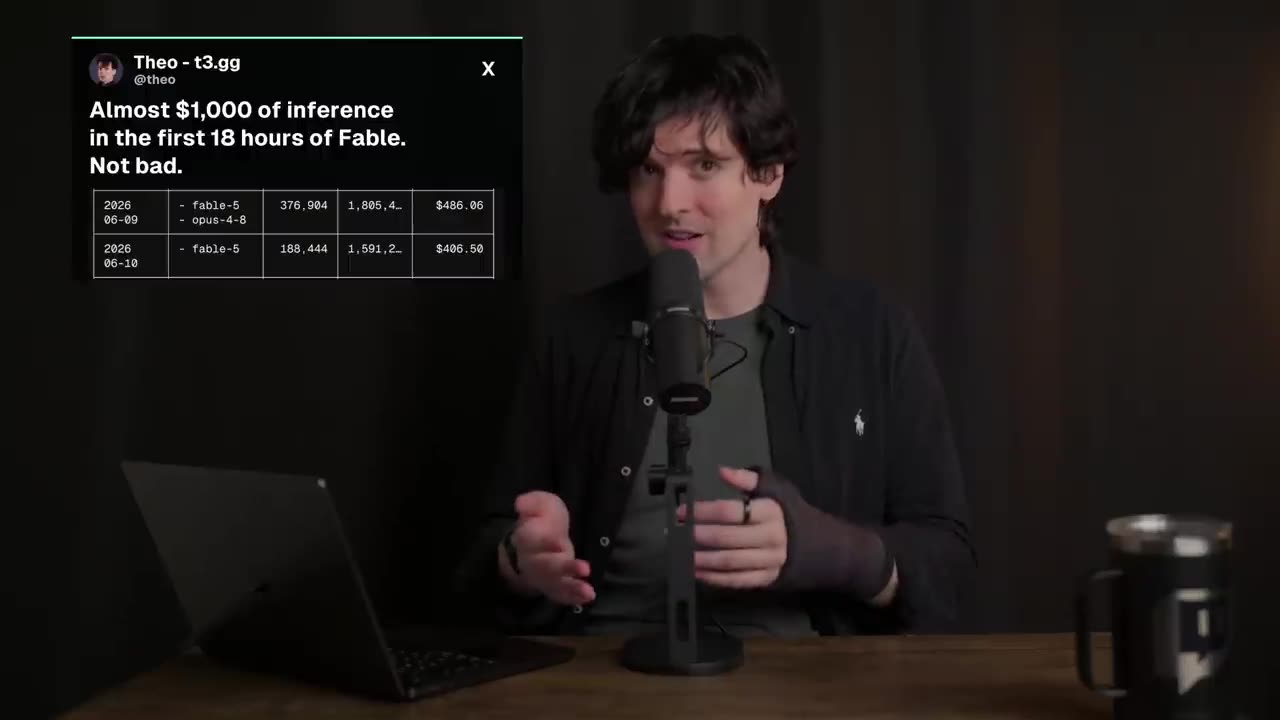
    Almost $1,000 of inference in the first 18 hours of Fable. Not bad.

    Shown on screen for about 5 seconds. Not read aloud.

  24. Theo - t3.gg@theo

    In September of last year GPT-5 was the best model available. Similar performance can be achieved with DeepSeek V4 Flash. Input tokens (per 1m): $1.25 -> $0.06 (21x cheaper) Output tokens (per 1m): $10 -> $0.18 (55x cheaper) Even with a 3x increase in reasoning tokens, the difference nets out to almost 20x cheaper at the given level of intelligence. In September of last year GPT-5 was the best model available. Similar performance can be achieved with DeepSeek V4 Flash. x.com/theo/status/2097442574743306636?photo/1 3.gg

    Theo read it aloud at 9:08
    Deep Seek V4 Flash is 21 times cheaper than GPT-5 for input tokens and 55 times cheaper for output tokens.
  25. Theo - t3.gg@theo

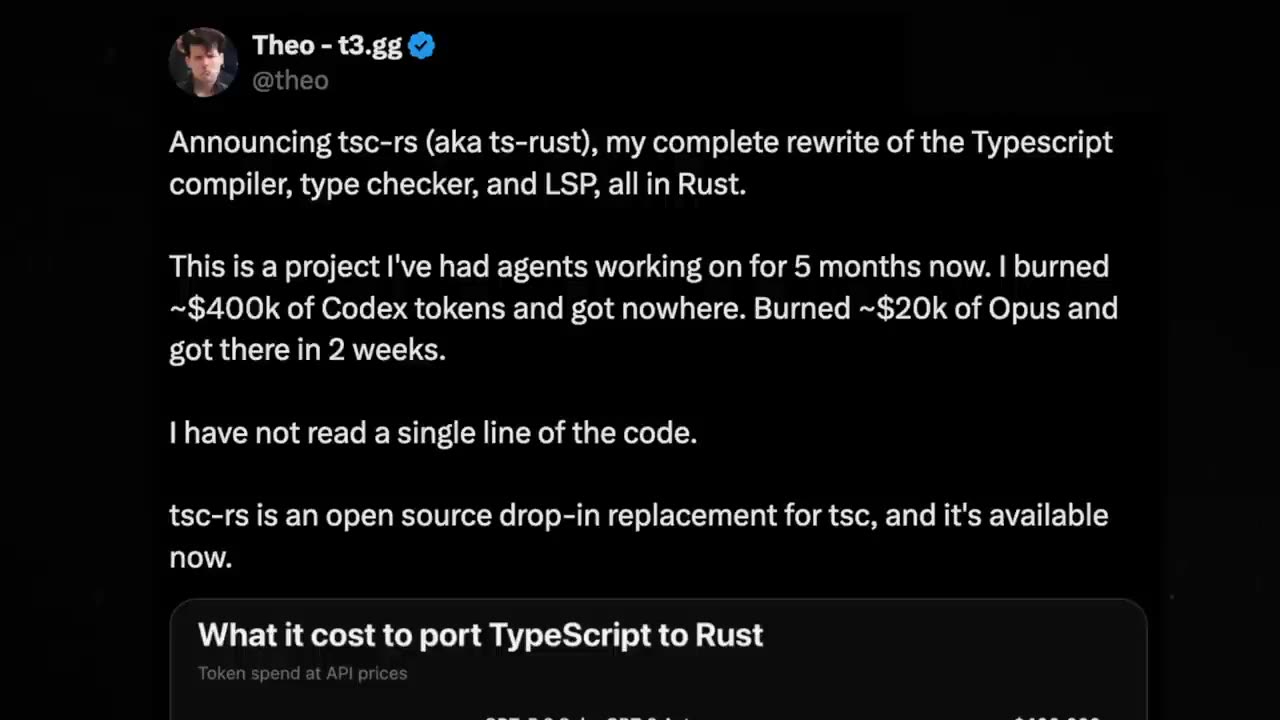
    Announcing tsc-rs (aka ts-rust), my complete rewrite of the Typescript compiler, type checker, and LSP, all in Rust.

    Theo read it aloud at 0:00
    Announcing TSC RS, aka TypeScript Rust, my complete rewrite of the TypeScript compiler, type checker, and LSP all in Rust.
  26. Theo - t3.gg@theo

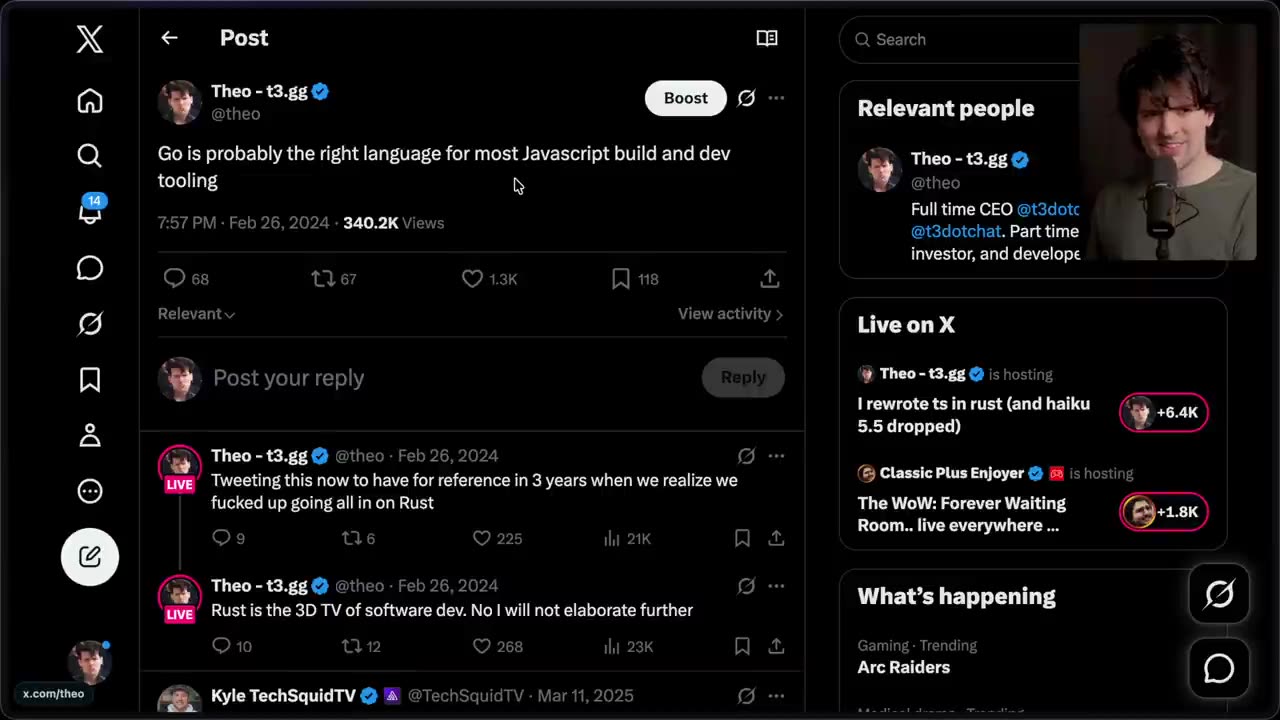
    Go is probably the right language for most Javascript build and dev tooling Tweeting this now to have for reference in 3 years when we realize we fucked up going all in on Rust Rust is the 3D TV of software dev. No I will not elaborate further I rewrote ts in rust (and haiku 5.5 dropped) I suddenly understand why you think go is a good language

    Theo read it aloud at 9:20
    TSC.
  27. Theo@theo

    X Theo - t3.gg on X: "Looking like Grok 4.7 is not quite as ch... x.com/theo/status/2102209324491891

    Shown on screen for about 5 seconds. Not read aloud.

  28. Theo - t3.gg@theo

    I got some issues wit the $132m/year is n to $3m at today's pri $1.2k within a year. Yes, $132m -> $1.2k. 1. The price listed is not accurate at all. $11m/month is just wrong. Real "api cost" is prolly $100k-$500k per month range. The 1.5T tokens number includes cache'd tokens. I looked at my own usage, and 33.5B tokens came out to $0.56/m (under 1/10th of Peter's $8/m estimate). I'm primarily using expensive models like Opus and Astra, and "1.5t tokens" would still have cost me ~$800k. If I used cheaper models and hit cache more,

    Shown on screen for about 17 seconds. Not read aloud.

  29. Theo - t3.gg@theo

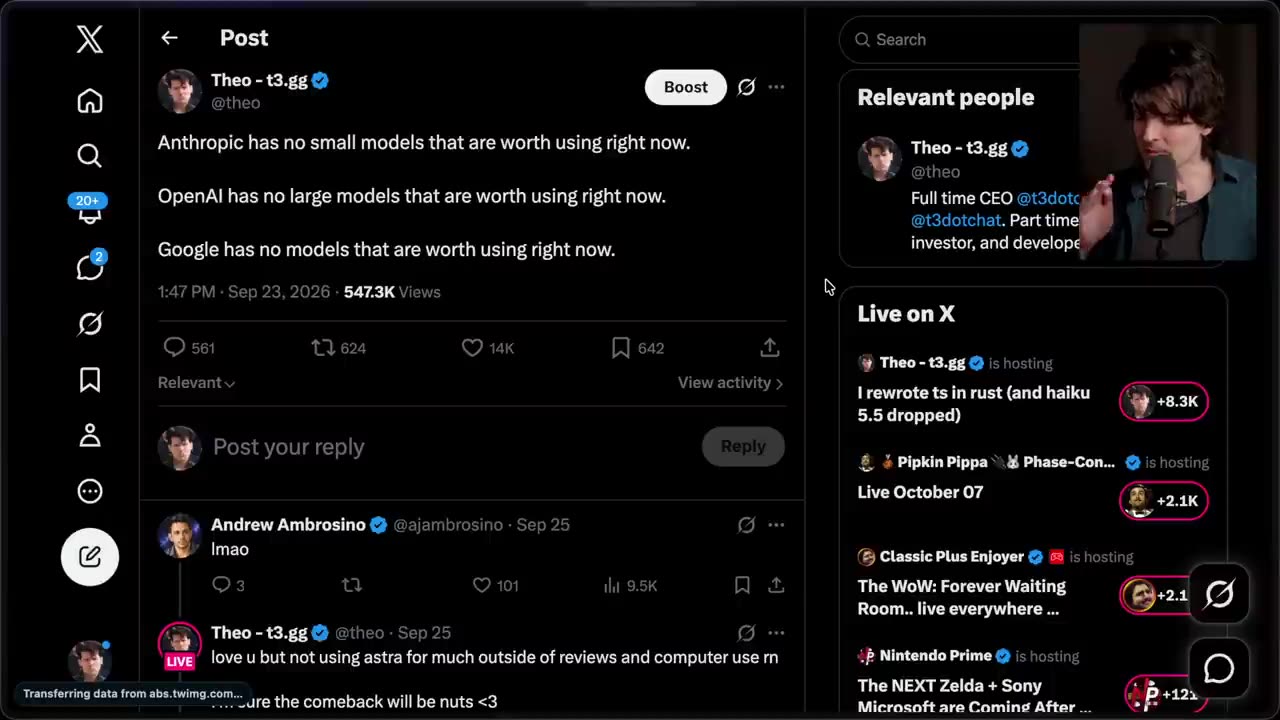
    Anthropic has no small models that are worth using right now. OpenAI has no large models that are worth using right now. Google has no models that are worth using right now. love u but not using astra for much outside of reviews and computer use rn ?... ure the comeback will be nuts <3 I rewrote ts in rust (and haiku 5.5 dropped) ? is hosting ? ...ure the comeback will be nuts <3

    Theo read it aloud at 0:58
    And of course Google gets the fun jab at the end saying none of the Google models are worth using.
  30. Theo - t3.gg@theo

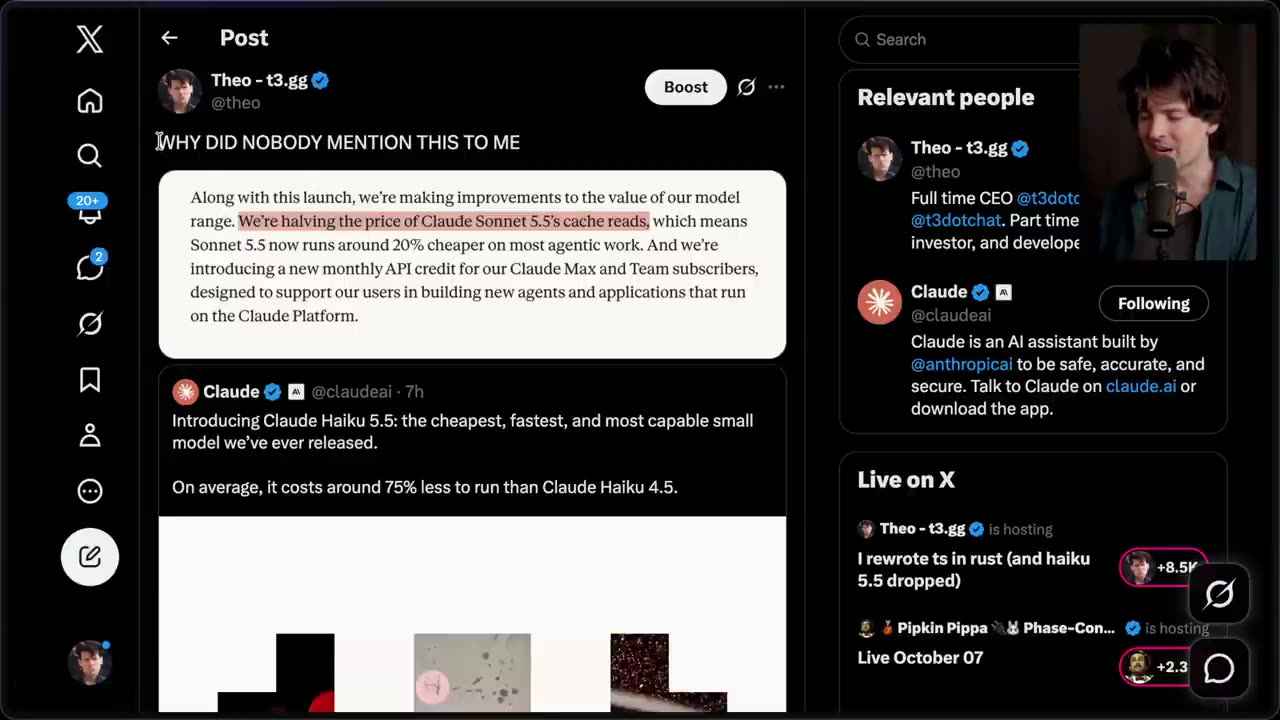
    WHY DID NOBODY MENTION THIS TO ME Along with this launch, we're making improvements to the value of our model range. We're halving the price of Claude Sonnet 5.5's cache reads, which means Sonnet 5.5 now runs around 20% cheaper on most agentic work. And we're introducing a new monthly API credit for our Claude Max and Team subscribers, designed to support our users in building new agents and applications that run on the Claude Platform. I rewrote ts in rust (and haiku 5.5 dropped) Full time CEO @t3dotgg @t3dotchat. Part time investor, and developer.

    Theo read it aloud at 4:27
    Haiku 5.5 is available at a much lower price than 4.
  31. Theo - t3.gg@theo

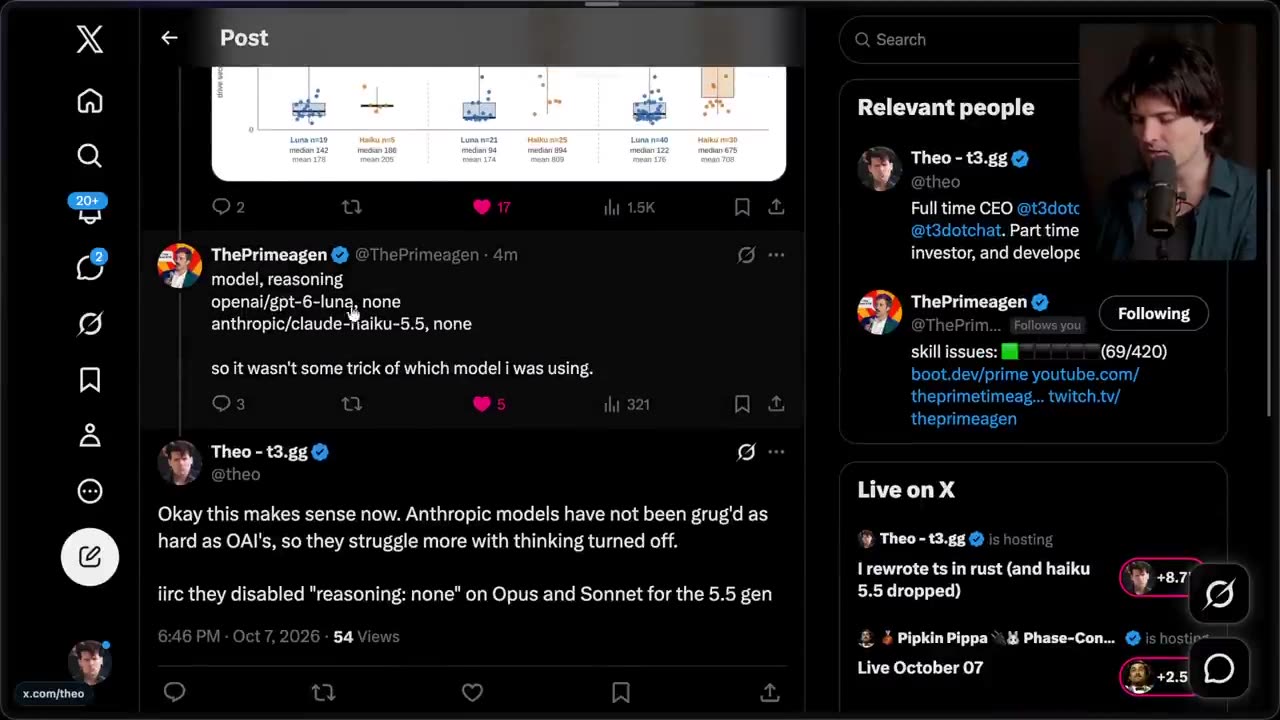
    Okay this makes sense now. Anthropic models have not been grub'd as hard as OA's, so they struggle more with thinking turned off. iirc they disabled "reasoning": none" on Opus and Sonnet for the 5.5 gen Okay this makes sense now. Anthropic models have not been drug'd as hard as OAI's, so they struggle more with thinking turned off.

    Shown on screen for about 40 seconds. Not read aloud.

  32. Theo - t3.gg@theo

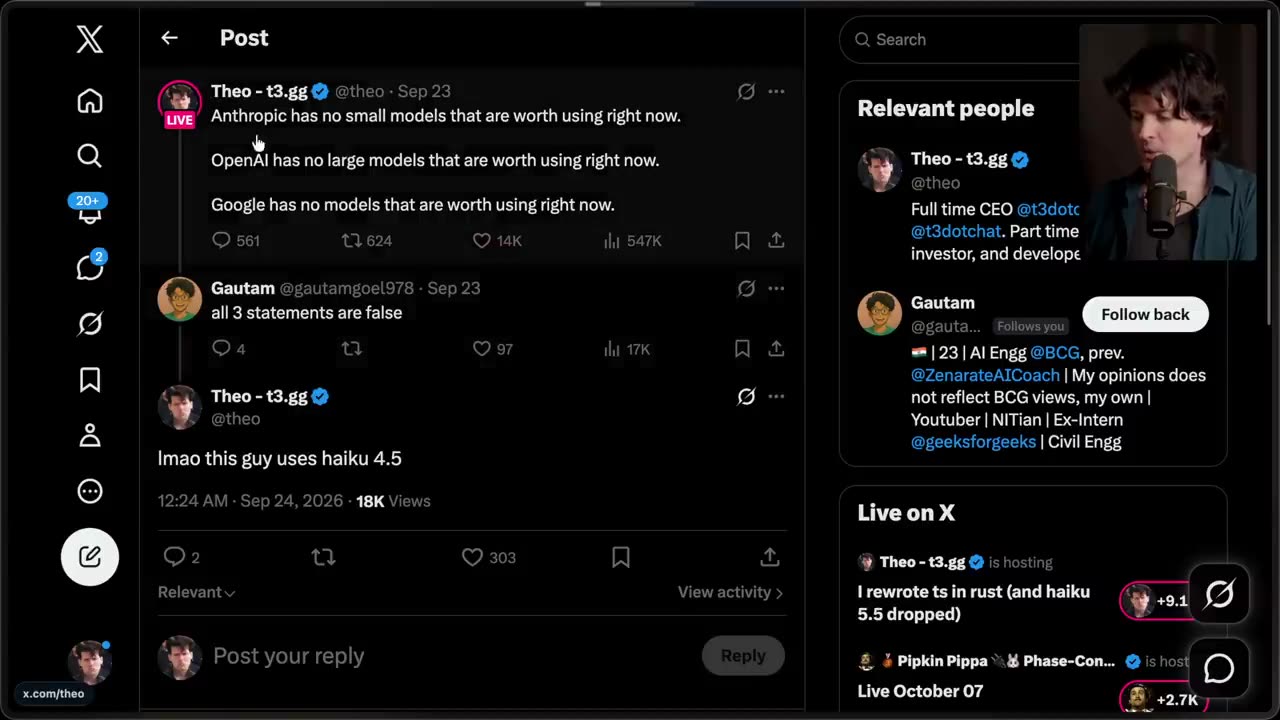
    Anthropic has no small models that are worth using right now. OpenAI has no large models that are worth using right now. Google has no models that are worth using right now. Imao this guy uses haiku 4.5

    Theo read it aloud at 18:34
    models worth using, OpenAI has no large models worth using, and Google has none that worth using, somebody replied, "All three statements are false.
  33. Theo - t3.gg@theo

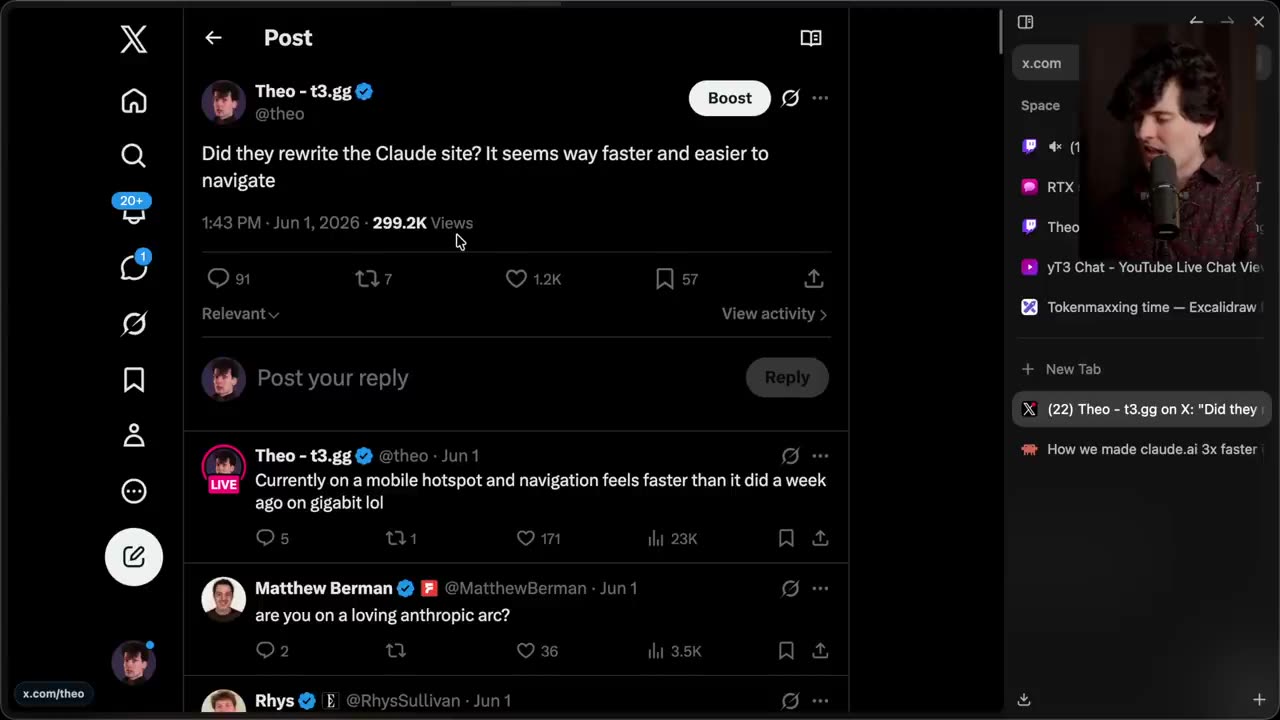
    Did they rewrite the Claude site? It seems way faster and easier to navigate Confirmed rewrite with Tanstack and a bunch of data precaching. Great work Anthropic! Claude site is finally usable

    Theo read it aloud at 4:38
    But that makes me even more curious what they did because they already did the framework upgrade.
  34. Theo - t3.gg@theo

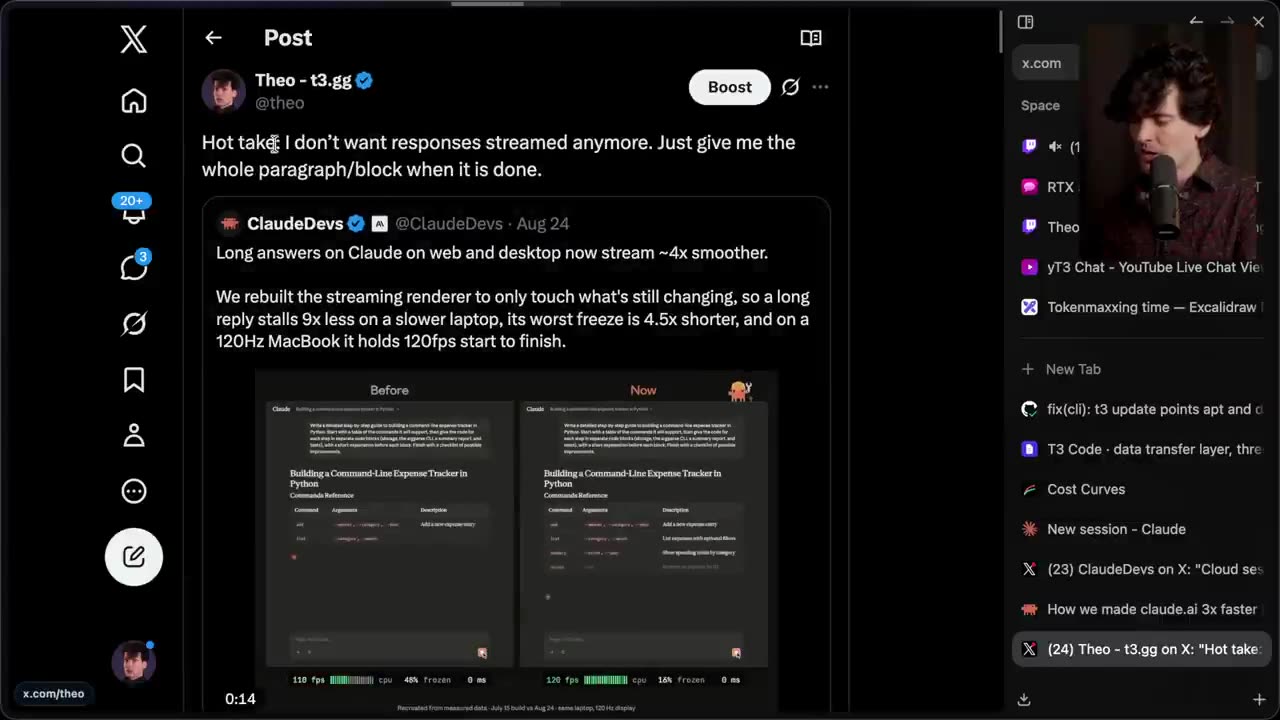
    Hot take 🫵 I don't want responses streamed anymore. Just give me the whole paragraph/block when it is done. To be VERY clear - I'm referring to TOKEN by TOKEN streaming. You should "stream" down paragraphs, code blocks, tool calls etc. Just stop sending incomplete text!!! I can wait til the paragraph is done, it is okay. It also makes UI way less "flash"-y Oh also obligated to mention that making this perform well is REALLY HARD and I am impressed with the work they did here :)

    Theo read it aloud at 1:07:15
    Agore, good point.
  35. Theo - t3.gg@theo

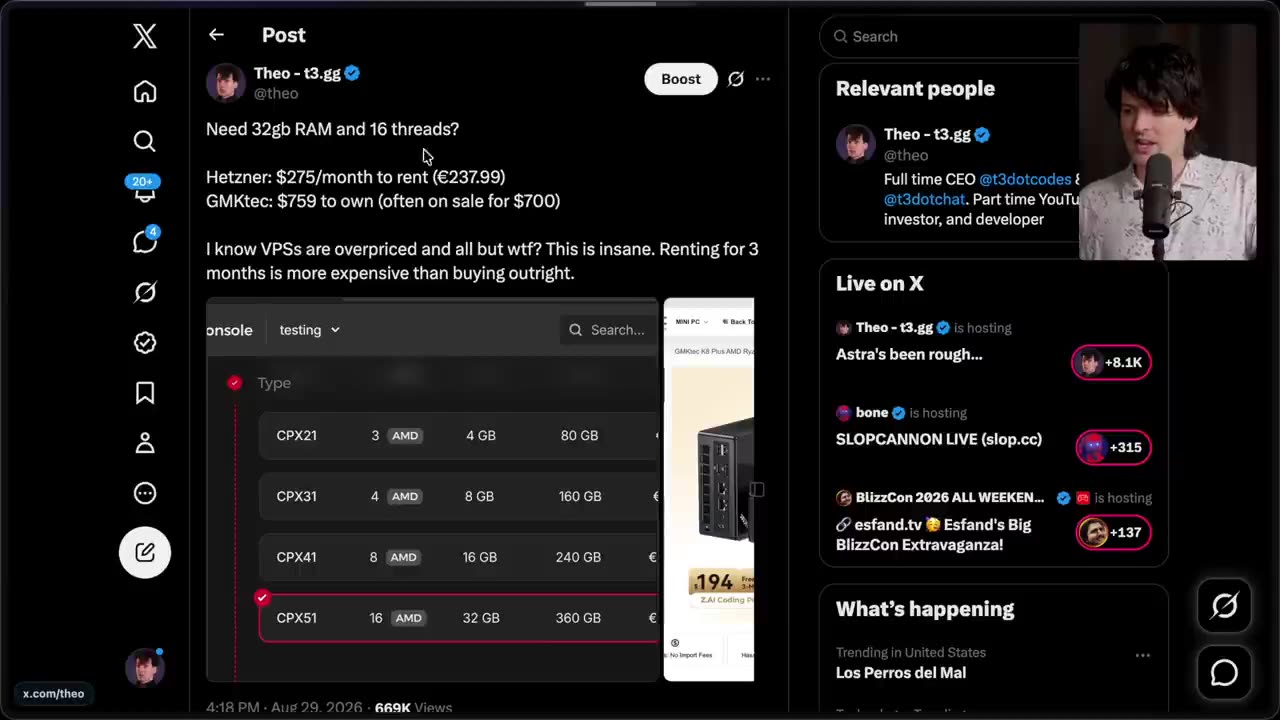
    Need 32gb RAM and 16 threads? Hetzner: \$275/month to rent (€€237.99) GMKtec: \$759 to own (often on sale for \$700) I know VPSs are overpriced and all but wtf? This is insane. Renting for 3 months is more expensive than buying outright. Astra's been rough... Need 32gb RAM a Hetzner: $275/mo GMKtec: $759 to c ($700) I know VPSs are o wtf? This is insane more expensive than buying outright. Need 32gb RAM a... Hetzner: $275/mo... GMKtec: $759 to ... ($700) I know VPSs are o... wtf? This is insane... is more expensive than buying outright.
    Theo read it aloud at 1:00:23
    Need 32 gigs of RAM and 16 threads?
  36. Theo - t3.gg@theo

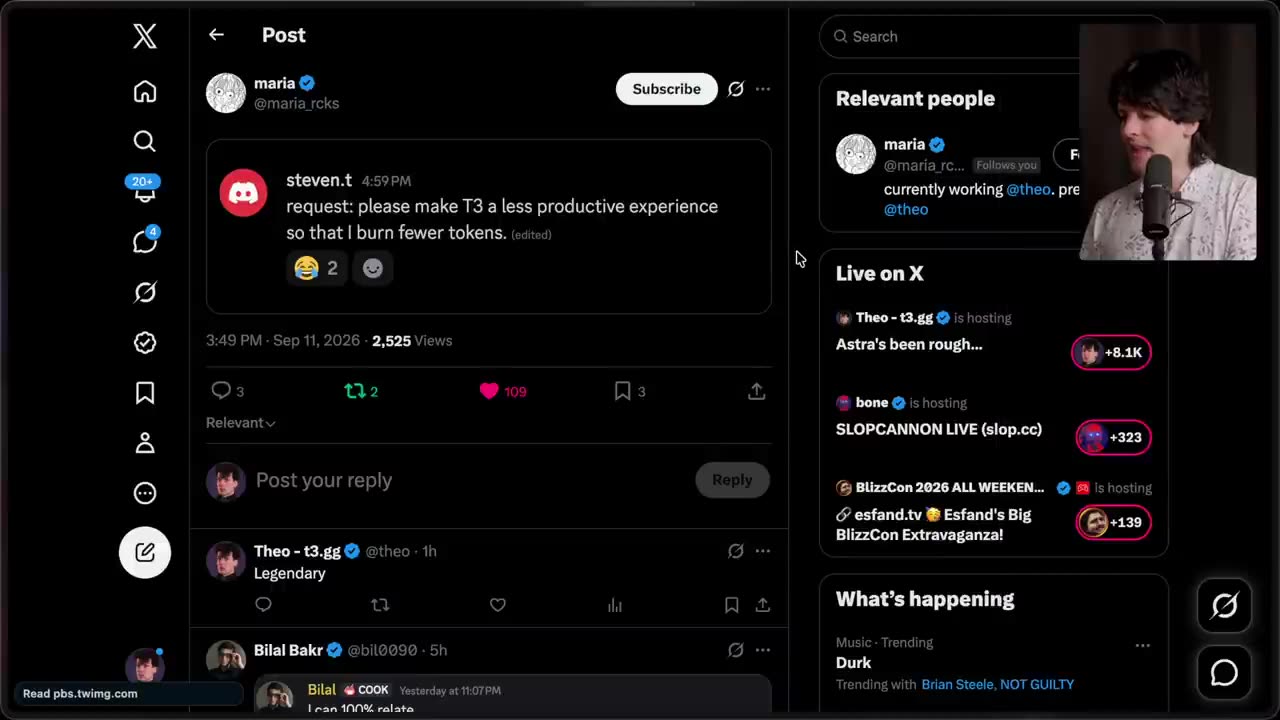
    Legendary Astra's being rough...

    Shown on screen for about 85 seconds. Not read aloud.

  37. Theo - t3.gg@theo

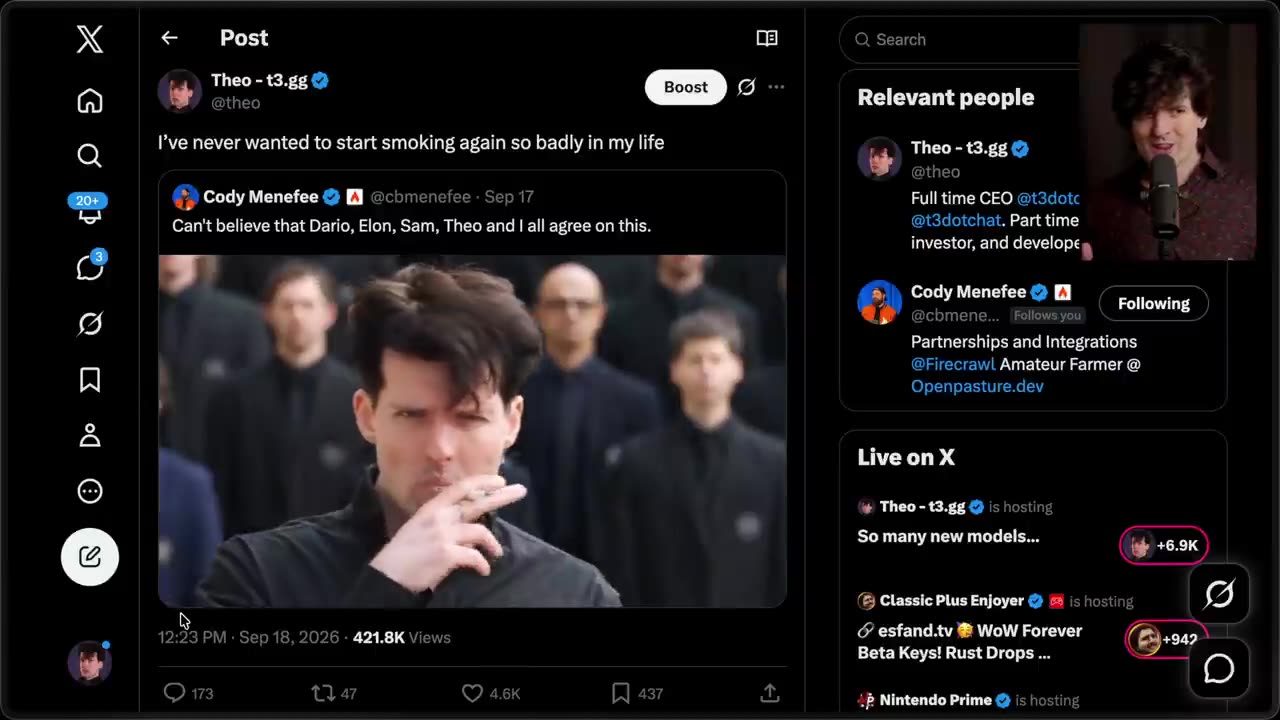
    I've never wanted to start smoking again so badly in my life So many new models...

    Shown on screen for about 12 seconds. Not read aloud.

  38. OpenAI fights back
    Theo - t3.gg@theo

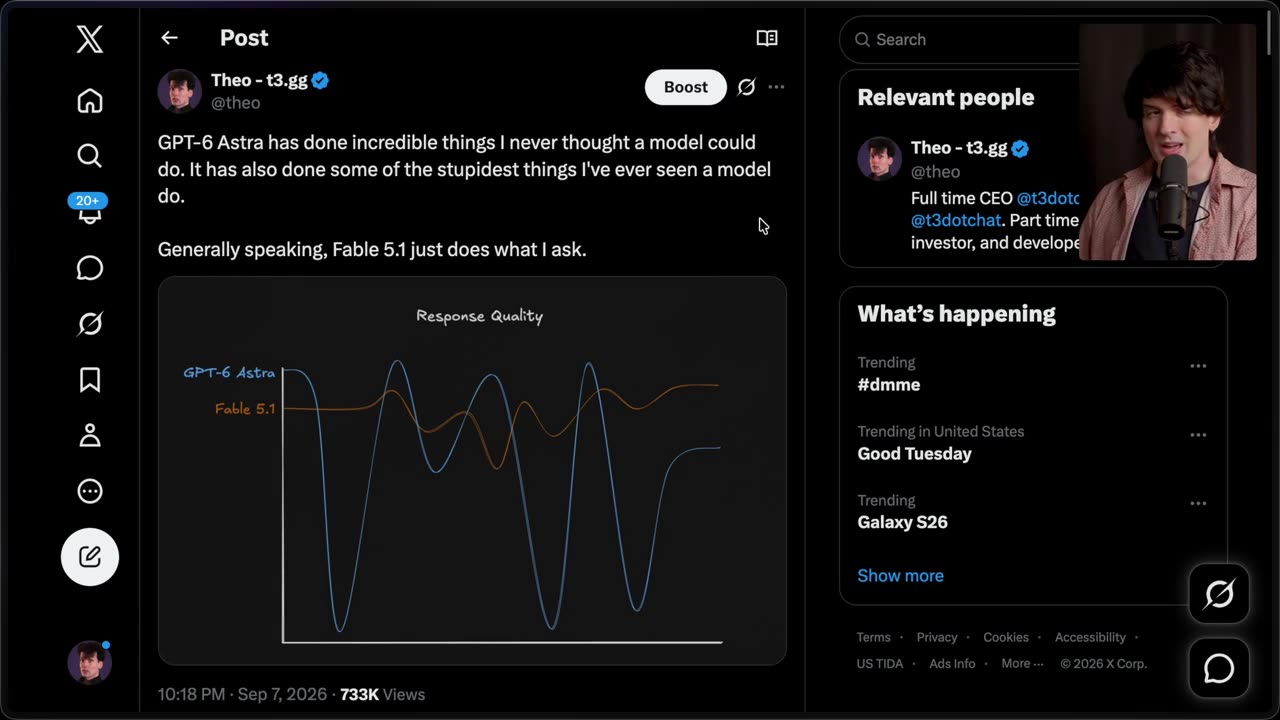
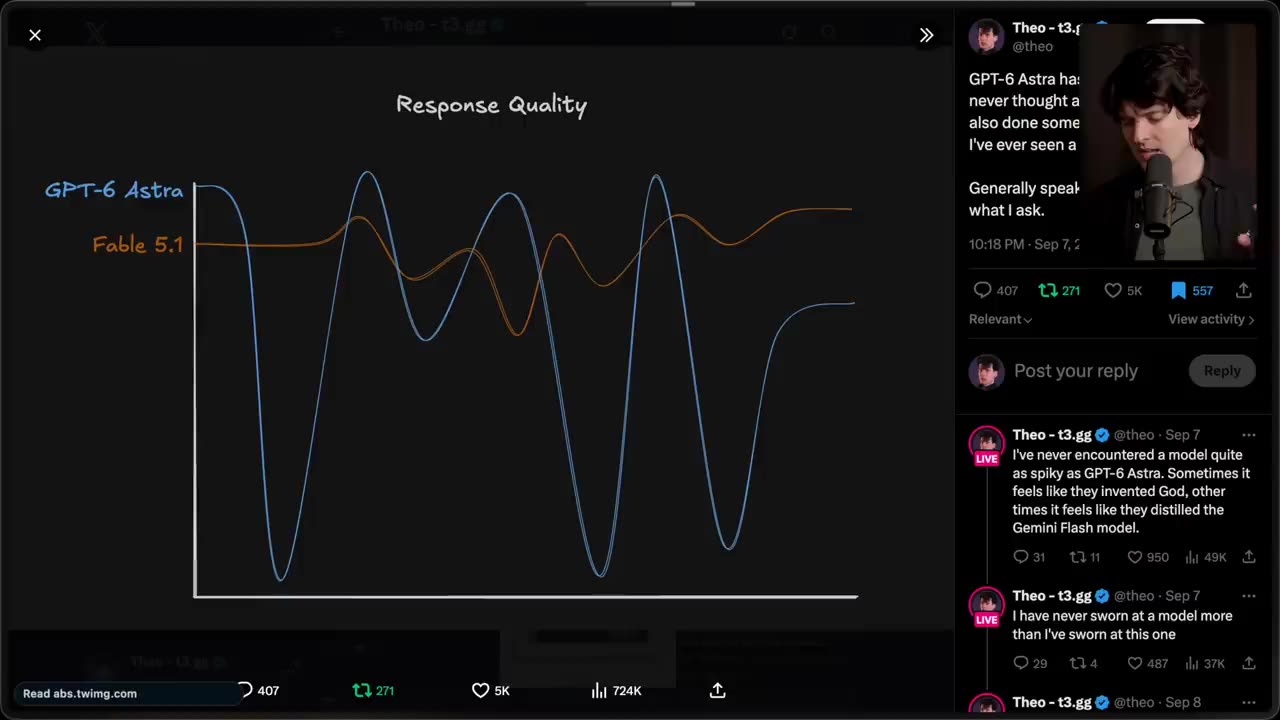
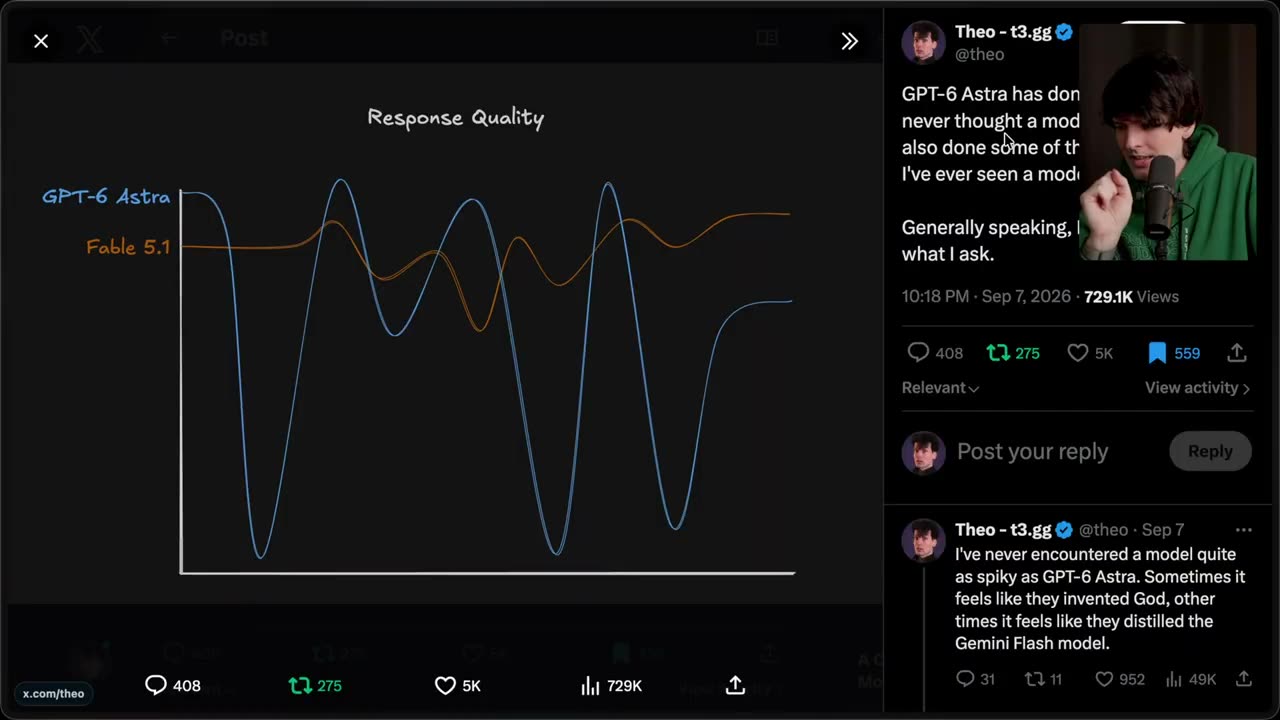
    GPT-6 Astra has done incredible things I never thought a model could do. It has also done some of the stupidest things I've ever seen a model do. Generally speaking, Fable 5.1 just does what I ask. Generally speaking, Fable 5.1 just does what I ask. Full time CEO @t3dotch | @t3dotchat. Part time investor, and develo?

    Shown on screen for about 110 seconds. Not read aloud.

  39. Theo - t3.gg@theo

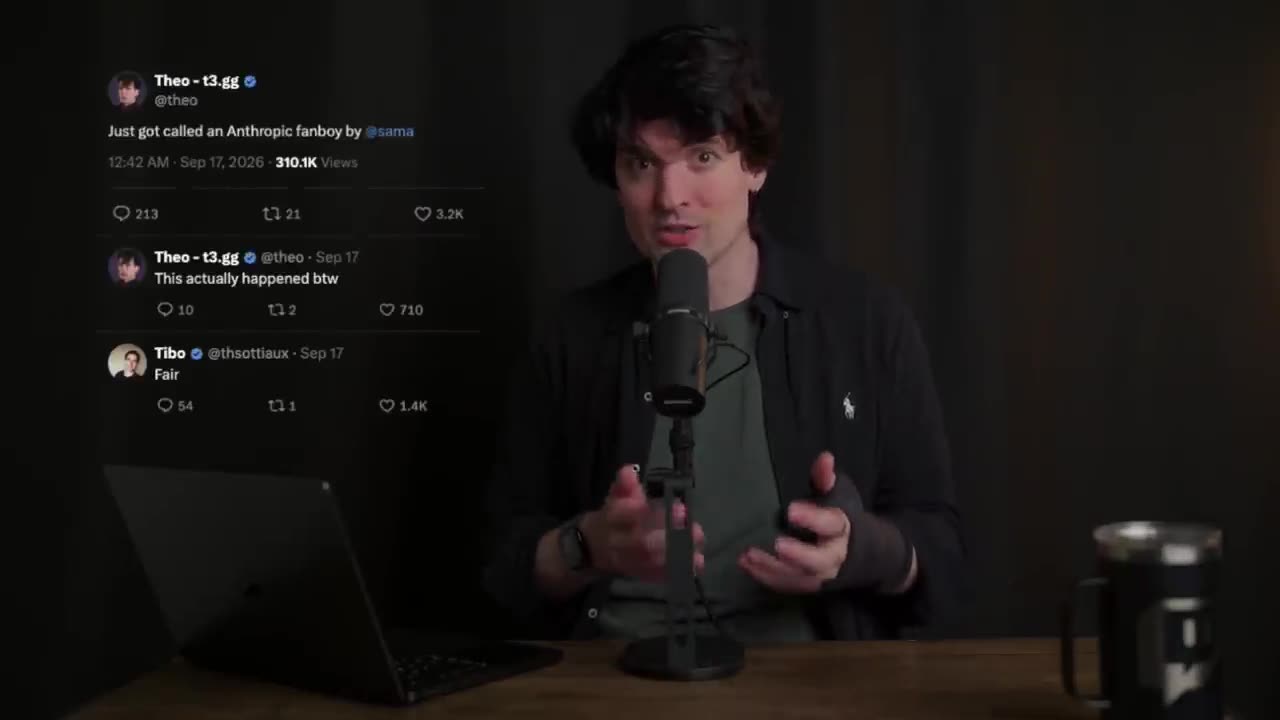
    Just got called an Anthropic fanboy by @sama 12:42 AM · Sep 17, 2026 · 310.1K Views This actually happened btw Just got called an Anthropic fanboy by @sama

    Theo read it aloud at 0:09
    What's even more insane though is the fact that Sam Altman just called me an Anthropic fanboy specifically because of how much I prefer using Fable over Astra for my day-to-day
  40. Theo - t3.gg@theo

    GPT-6 Astra has: never thought a model could be as good as the ones I've also done some testing on and it's done some things that I've never even seen a model do before. Generally speaks exactly how I ask. I've never encountered a model quite as spiky as GPT-6 Astra. Sometimes it feels like they invented God, other times it feels like they distilled the Gemini Flash model. Sep 7 I have never sworn at a model more than I've sworn at this one Sep 7 GPT-6 Astra has: never thought a model could be so smart, also done some things I've ever seen a model do. Generally speaks exactly what I ask. GPT-6 Astra has: never thought a also done some i've ever seen a Generally speak what I ask. 10:18 PM · Sep 7, 2023 GPT-6 Astra has: never thought a question i've ever seen a ... Generally speaks what I ask. GPT-6 Astra has never thought a? also done some? I've ever seen a? Generally speaks what I ask.

    Shown on screen for about 47 seconds. Not read aloud.

  41. Theo - t3.gg@theo

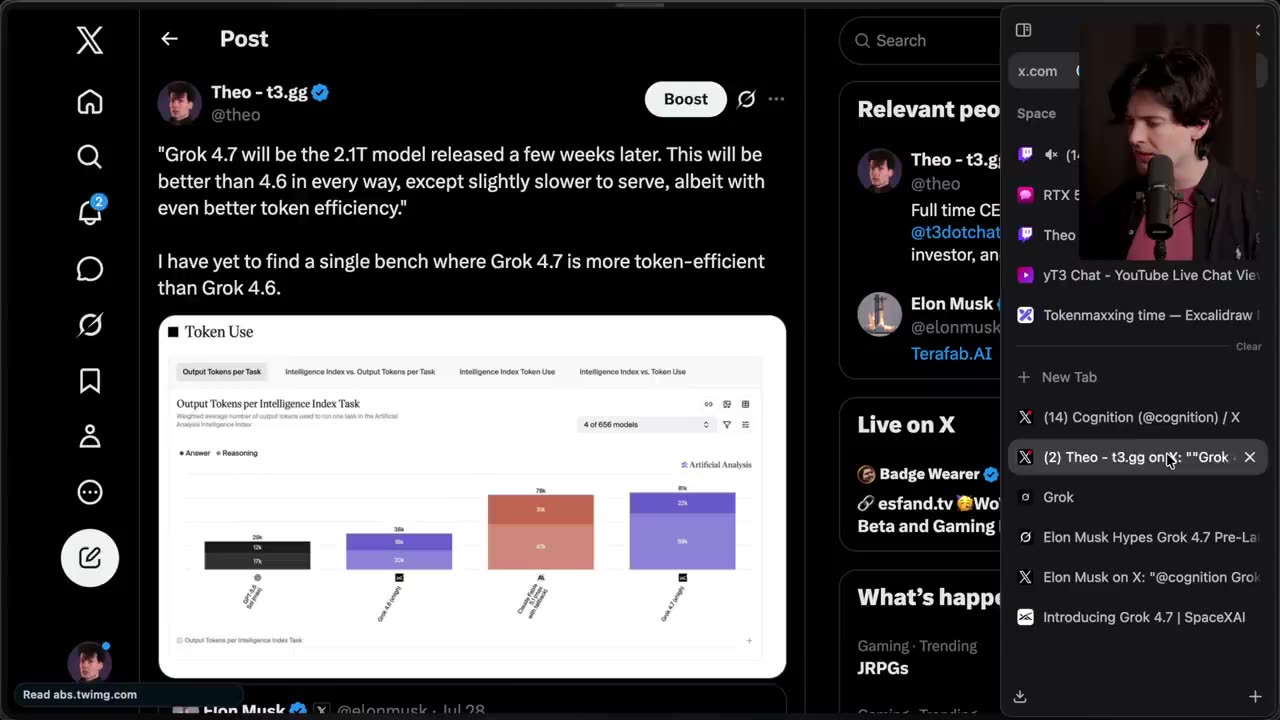
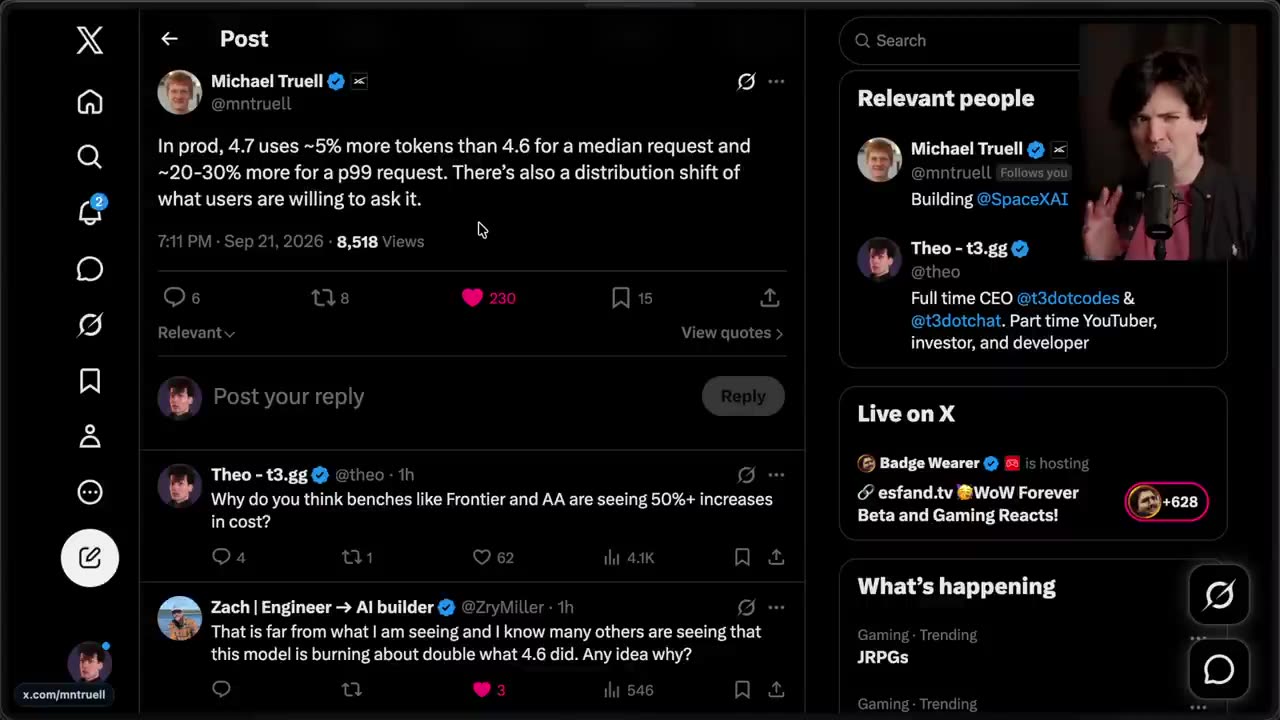
    "Grok 4.7 will be the 2.1T model released a few weeks later. This will be better than 4.6 in every way, except slightly slower to serve, albeit with even better token efficiency."

    Theo read it aloud at 3:34
    The same price and speed part is particularly interesting because of things Elon has mentioned in the past.
  42. Theo - t3.gg@theo

    Why do you think benches like Frontier and AA are seeing 50%+ increases in cost? Looking like Grok 4.7 is not quite as cheap as before. Comes out more expensive than Astra on Artificial Analysis 🧐 full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer

    Theo read it aloud at 4:38
    Astra cost 326 and Gro 47 cost $3.74 per task.
  43. Theo - t3.gg@theo

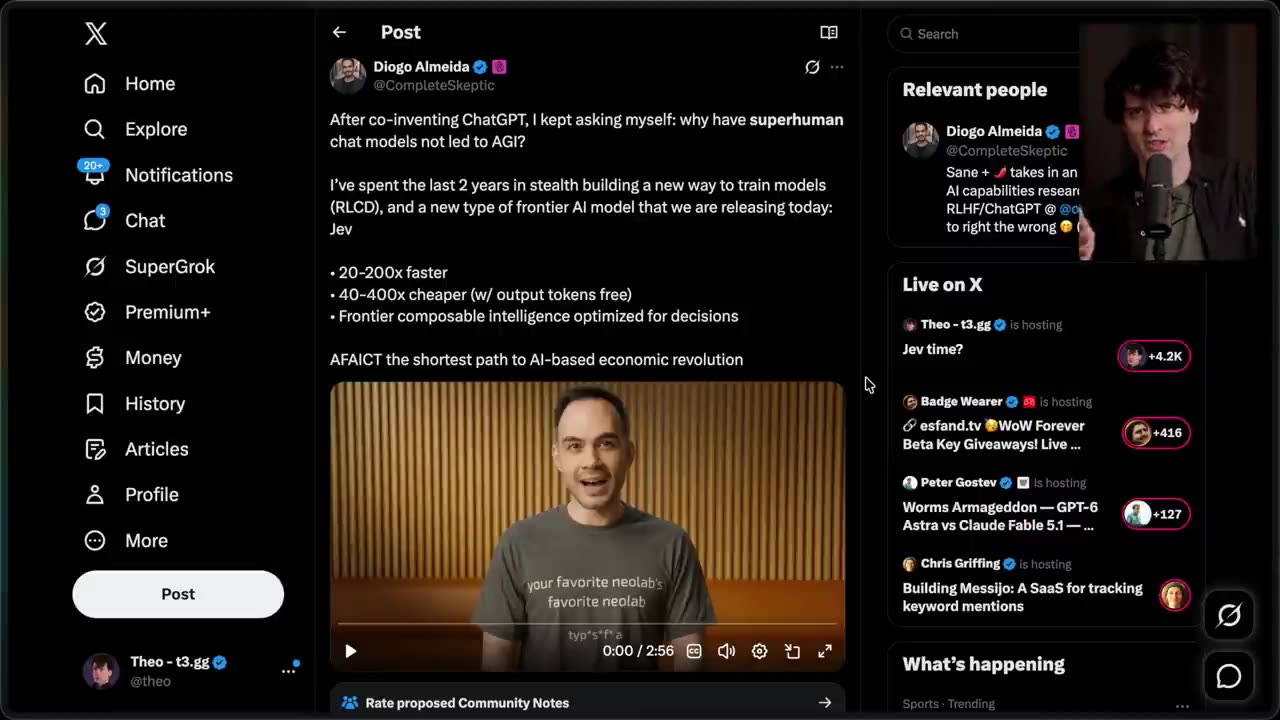
    Jev time?

    Shown on screen for about 5 seconds. Not read aloud.

  44. Theo - t3.gg@theo

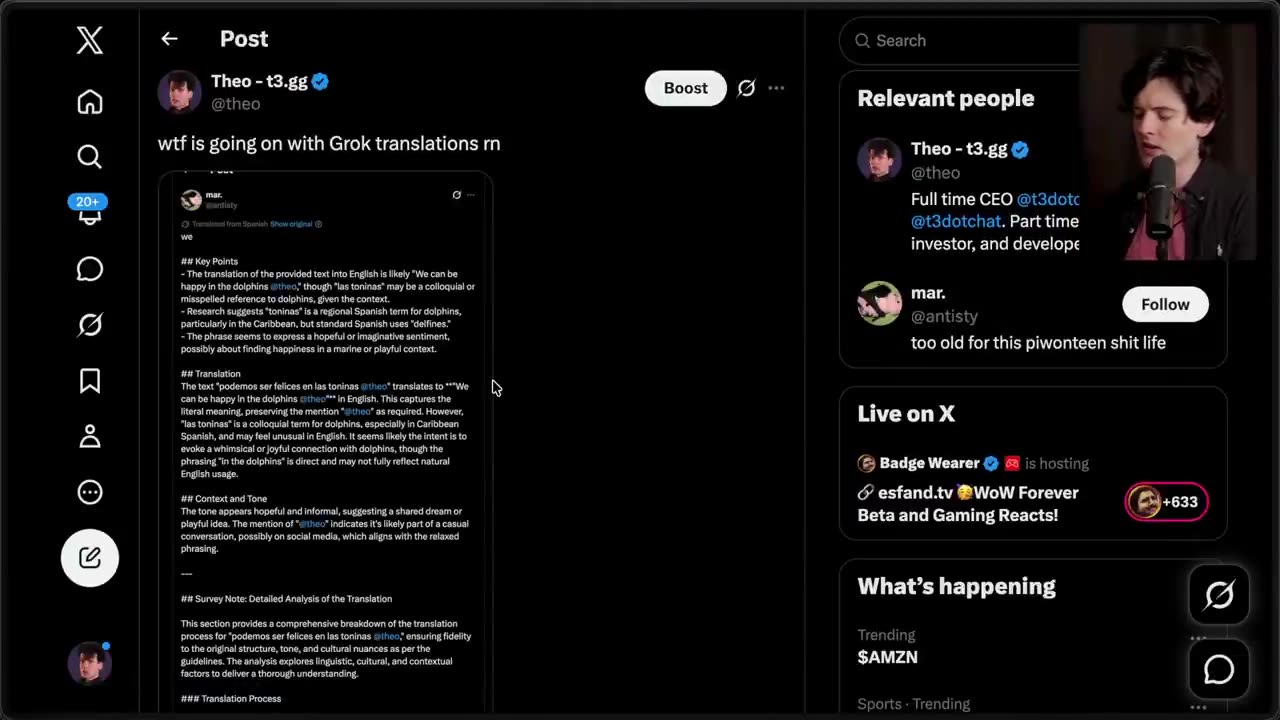
    wtf is going on with Grok translations rn Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer x.com/choihetssal07? 34 172 175

    Theo read it aloud at 20:55
    Right now it says some absolute nonsense.
  45. Theo - t3.gg@theo

    GPT-6 Astra has done things I've never thought a model could do, and more importantly, I've never seen a model do some of this. Generally speaking, I'm just happy it can finally do what I ask. I've never encountered a model quite as spikey as GPT-6 Astra. Sometimes it feels like they invented God, other times it feels like they distilled the Gemini Flash model. Generally speaking, it does exactly what I ask. GPT-6 Astra has done things I have never thought a model could do, and has also done some of the wildest things I've ever seen a model do. Generally speaking, it's even better than what I ask. GPT-6 Astra has don? never thought a mod? also done some of th? I've ever seen a mod?

    Shown on screen for about 106 seconds. Not read aloud.

  46. Jev is incredible
    Theo - t3.gg@theo

    Jev time? This is a terrible compaction strategy that fundamentally doesn't understand how compaction and context management work. Seems like a lot of people are confused so let's break this down. 1. Compaction isn't a filter The role of compaction is to clean up history to keep the agent focused, not just detuning noise. It should be used sparingly when context gets too long, not constantly to keep context small. 2. Jev doesn't even know what it's deciding on! Models use the context of the thread to decide what to keep or not keep in a summary. This implementation goes through on a "line-by-line" (per tool call) basis to decide what should be left or deleted. Not only does this 32k token context model know very little of what happened before, but (in this implementation) it doesn't even know what the result of the tool call is! Deleting these things randomly will keep the model from knowing what it's tried and doomed to end up in "stupid loops" where the model keeps trying the same thing over and over. 3. You're giving up the reasoning entirely Frontier models from OpenAI, Anthropic, XAI, and Google do not share reasoning traces over the API. They share encrypted payloads, which Jev cannot see (and often will drop). This is a terrible compaction strategy that fundamentally doesn't understand how compaction and context management work.

    Theo read it aloud at 22:24
    For example, this tweet from Brain Trust.
  47. Theo - t3.gg@theo

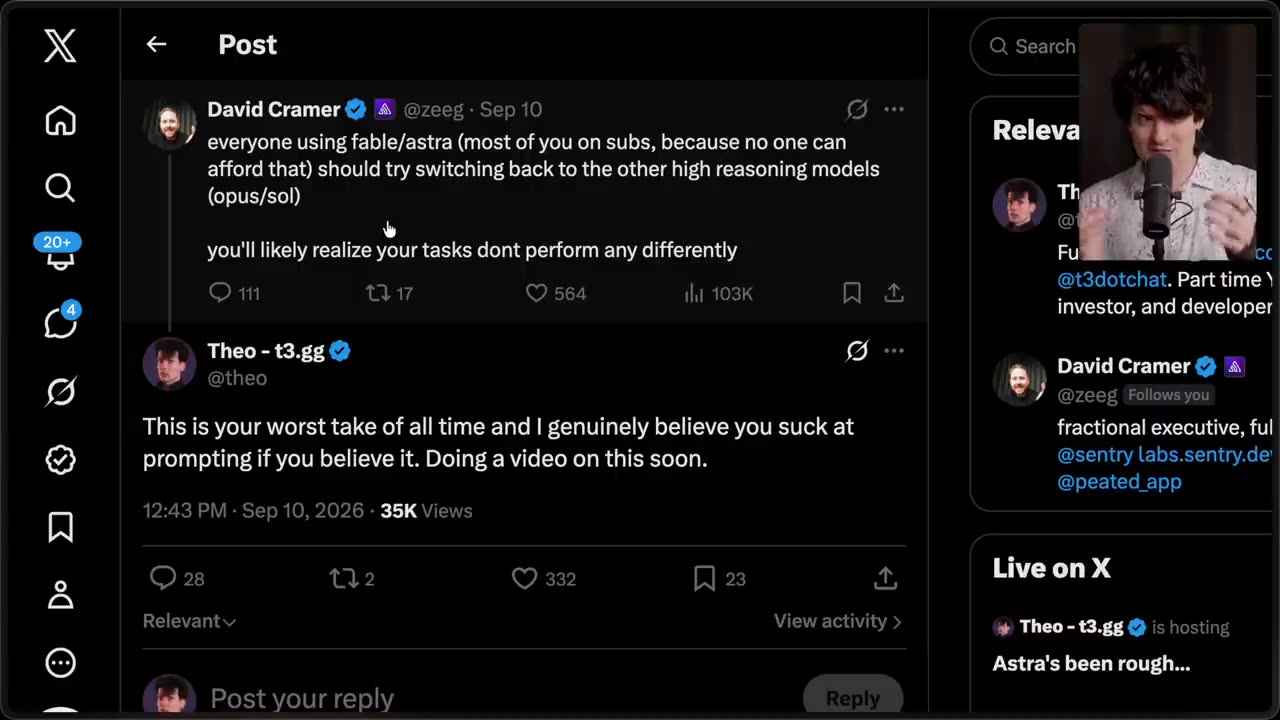
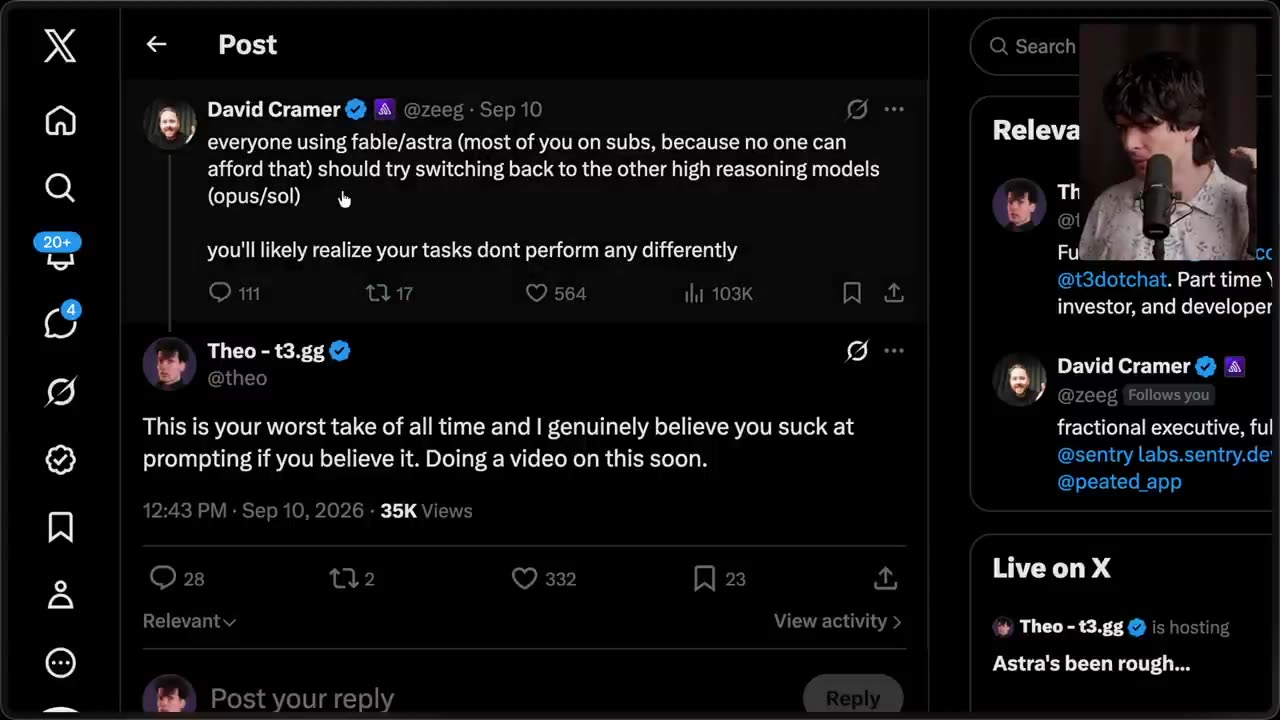
    This is your worst take of all time and I genuinely believe you suck at prompting if you believe it. Doing a video on this soon. do. It has also done some or the stupidest things I've ever seen a model do. Generally speaking, Fable 5.1 just does what I ask.

    Theo read it aloud at 0:36
    From David Cramer, aka Zeeg, the founder of Sentry, "Everyone using Fable or Astra, which is most of us on subs because no one can afford
  48. Theo - t3.gg@theo

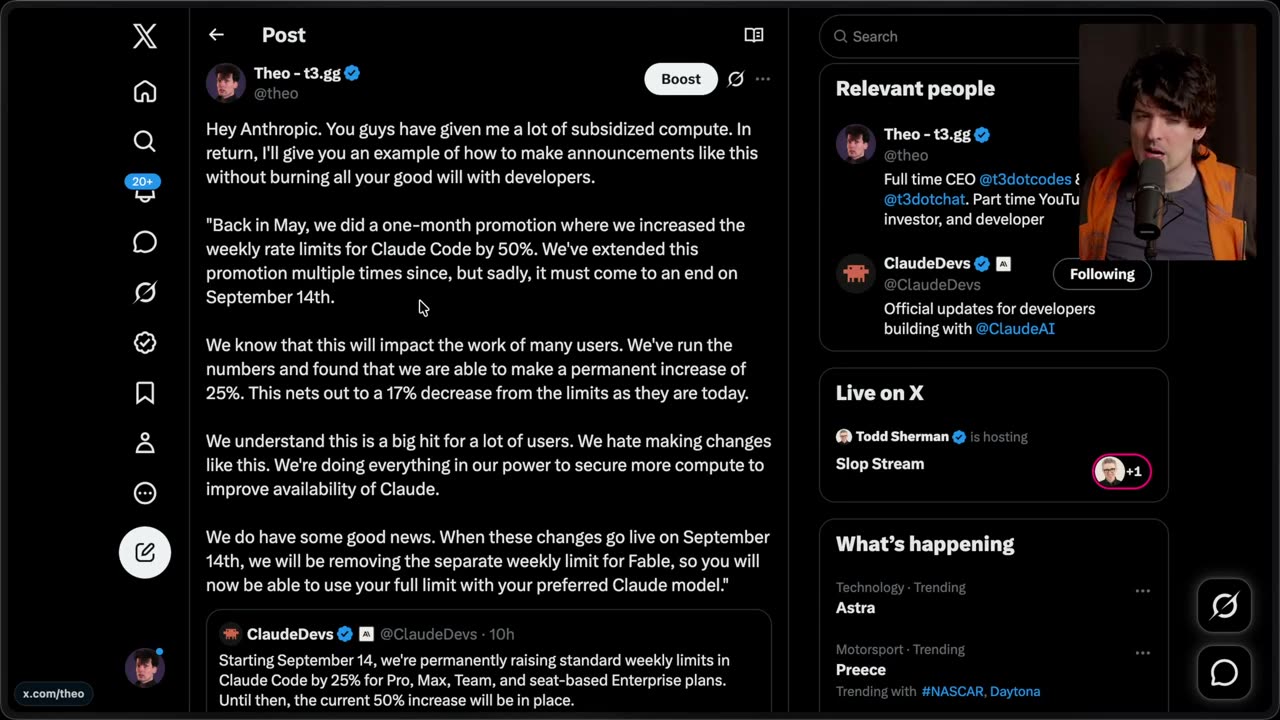
    Hey Anthropic. You guys have given me a lot of subsidized compute. In return, I'll give you an example of how to make announcements like this without burning all your good will with developers.

    Shown on screen for about 80 seconds. Not read aloud.

  49. Theo - t3.gg@theo

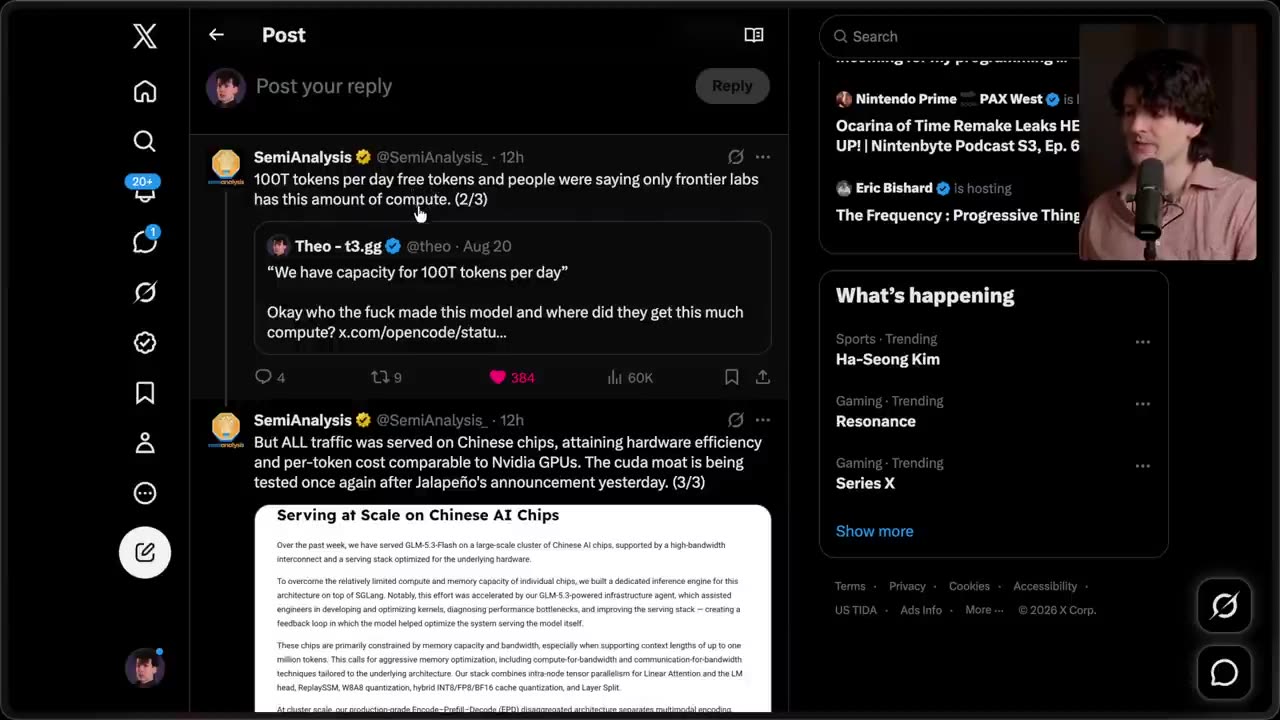
    "We have capacity for 100T tokens per day"

    Theo read it aloud at 11:25
    I believe it was 100 trillion tokens a day for free.
  50. Theo - t3.gg@theo

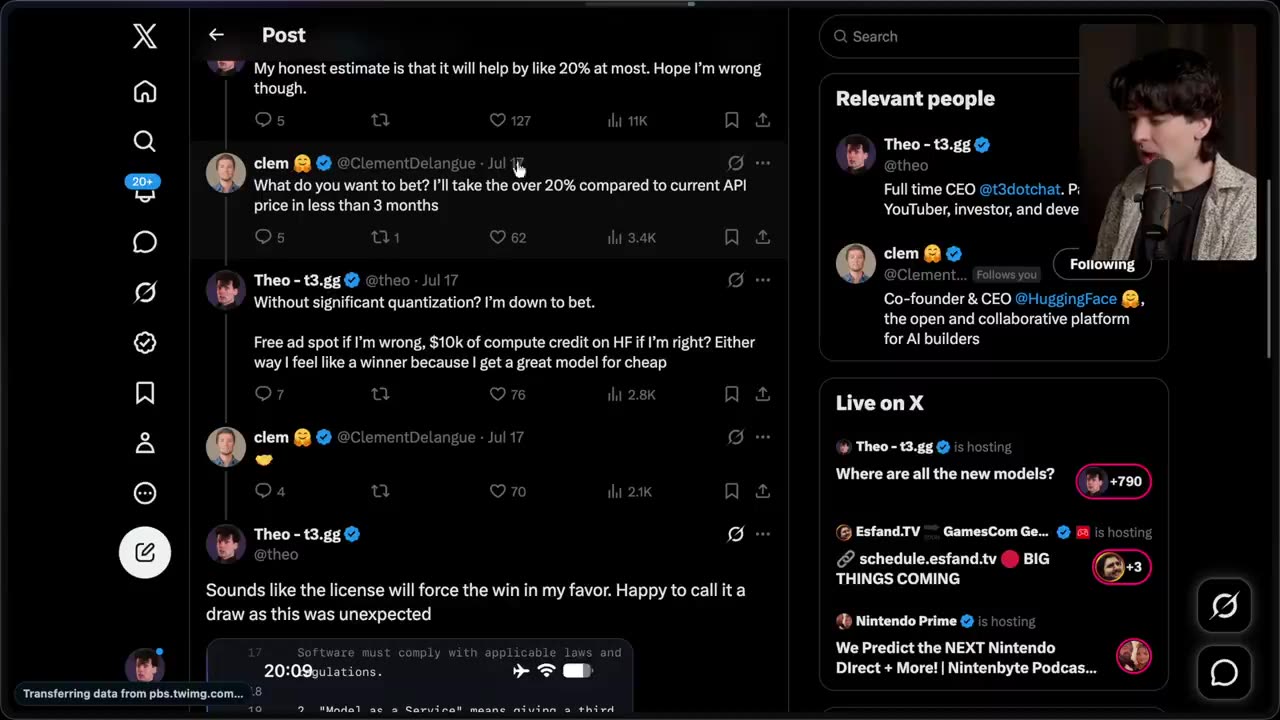
    Without significant quantization? I'm down to bet. Without significant quantization? I'm down to bet. Free ad spot if I'm wrong, $10k of compute credit on HF if I'm right? Either way I feel like a winner because I get a great model for cheap Sounds like the license will force the win in my favor. Happy to call it a draw as this was unexpected My honest estimate is that it will help by like 20% at most. Hope I'm wrong though.

    Shown on screen for about 18 seconds. Not read aloud.

  51. Theo - t3.gg@theo

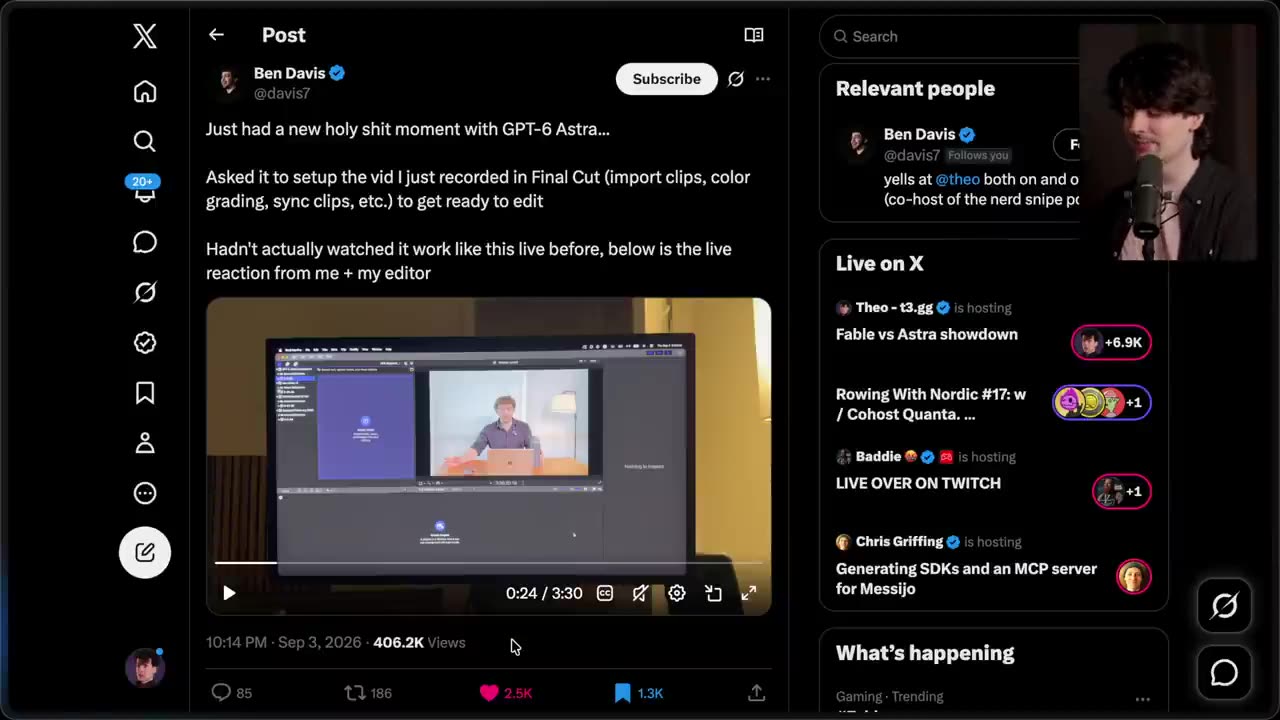
    yells at @theo both on and o (co-host of the nerd snipe pr I think this might be able to pass an interview 10:38 AM · Jul 17, 2020 I'm still in awe. Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer Fable vs Astra showdown

    Shown on screen for about 105 seconds. Not read aloud.

  52. Theo - t3.gg@theo

    This is your worst take of all time and I genuinely believe you suck at prompting if you believe it. Doing a video on this soon. Astra's been rough... Sure, but I need it for the way I'm doing things. I'm able to pull the models in faster and check in on them less. The difference is significant and fundamentally increases the amount of work I can do without increasing the amount of effort it takes. Sure, but I need it for the way I'm doing things.

    Shown on screen 2 times. Not read aloud.

  53. It's Here.
    Theo - t3.gg@theo

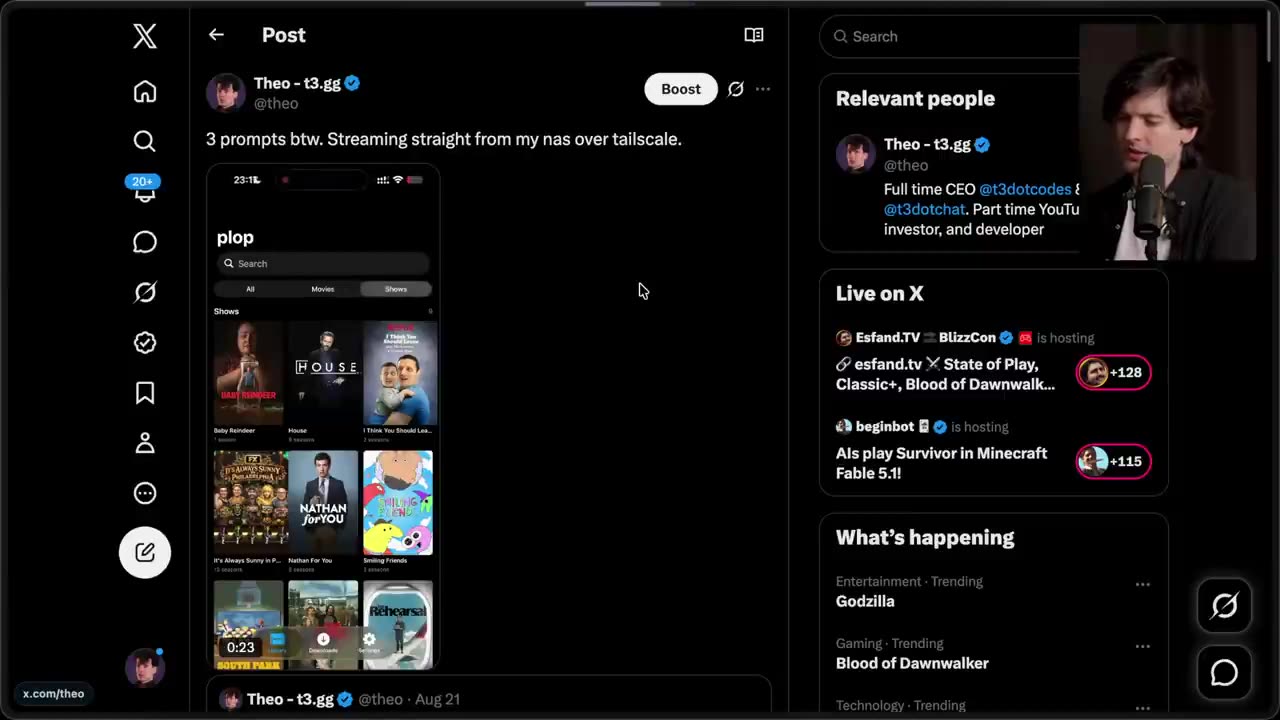
    3 prompts btw. Streaming straight from my nas over tailscale. Full time CEO @t3dotcodes & @t3dotchat. Part time YouTub investor, and developer.

    Shown on screen for about 63 seconds. Not read aloud.

  54. Ox Alpha is INSANE
    Theo - t3.gg@theo

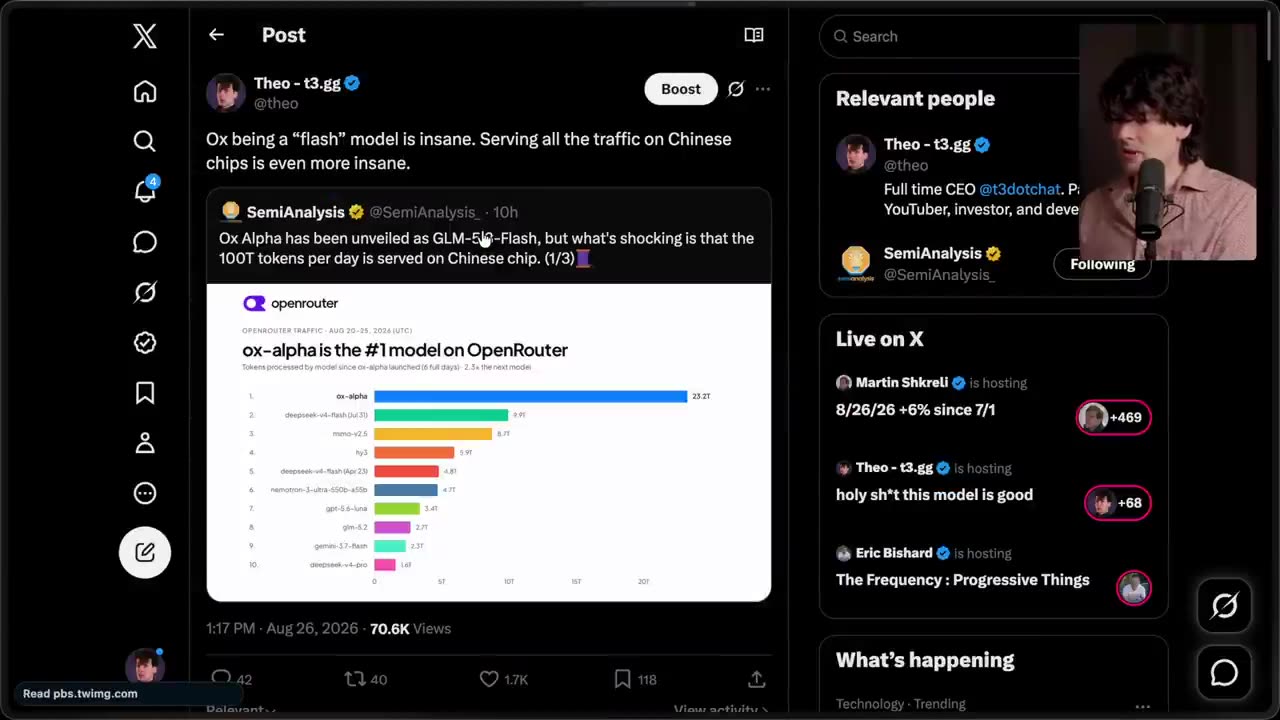
    Ox being a "flash" model is insane. Serving all the traffic on Chinese chips is even more insane.

    Shown on screen for about 6 seconds. Not read aloud.

  55. It's Here.
    Theo - t3.gg@theo

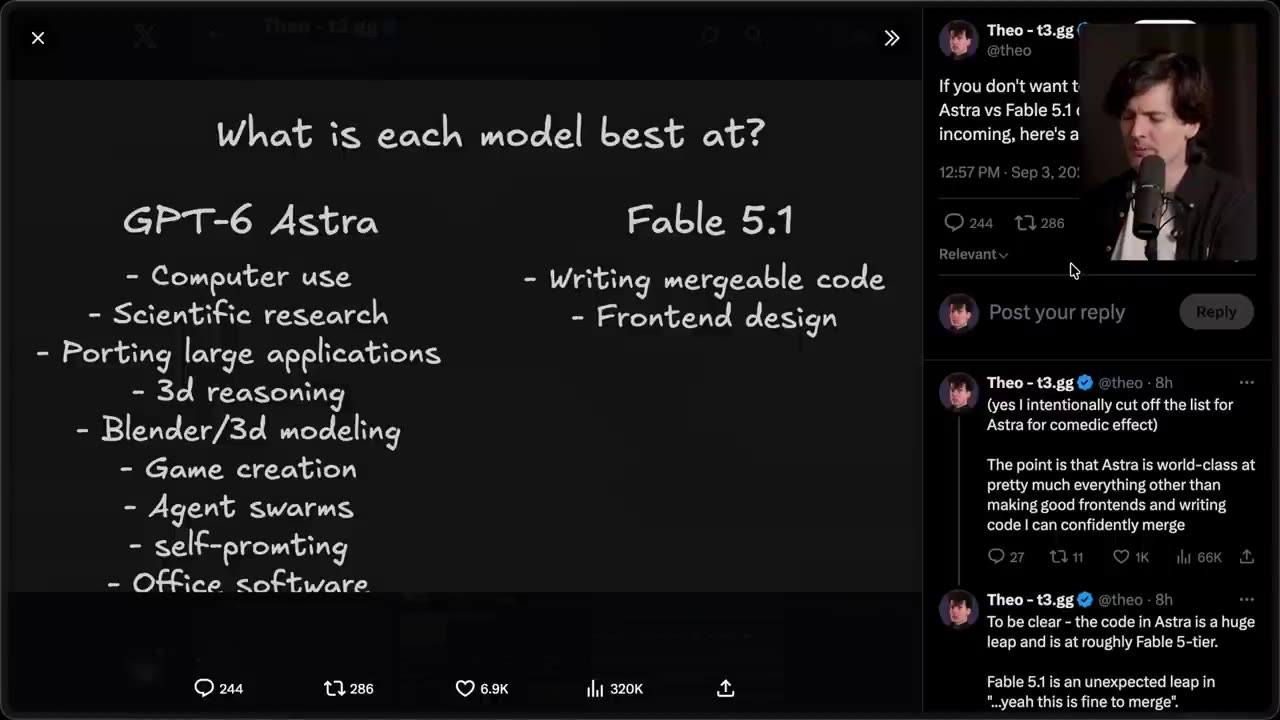
    If you don't want to choose between Astra vs Fable 5.1, incoming, here's a breakdown: (yes I intentionally cut off the list for Astra for comedic effect) To be clear - the code in Astra is a huge leap and is at roughly Fable 5-tier. Fable 5.1 is an unexpected leap in ...yeah this is fine to merge". (yes I intentionally cut off the list for Astra for comedic effect) The point is that Astra is world-class at pretty much everything other than making good frontends and writing code I can confidently merge What is each model best at? GPT-6 Astra - Computer use - Scientific research - Porting large applications - 3d reasoning - Blender/3d modeling - Game creation - Agent swarms - self-promting - Office software Fable 5.1 - Writing mergeable code - Frontend design

    Shown on screen for about 66 seconds. Not read aloud.

Opens in a new tab.