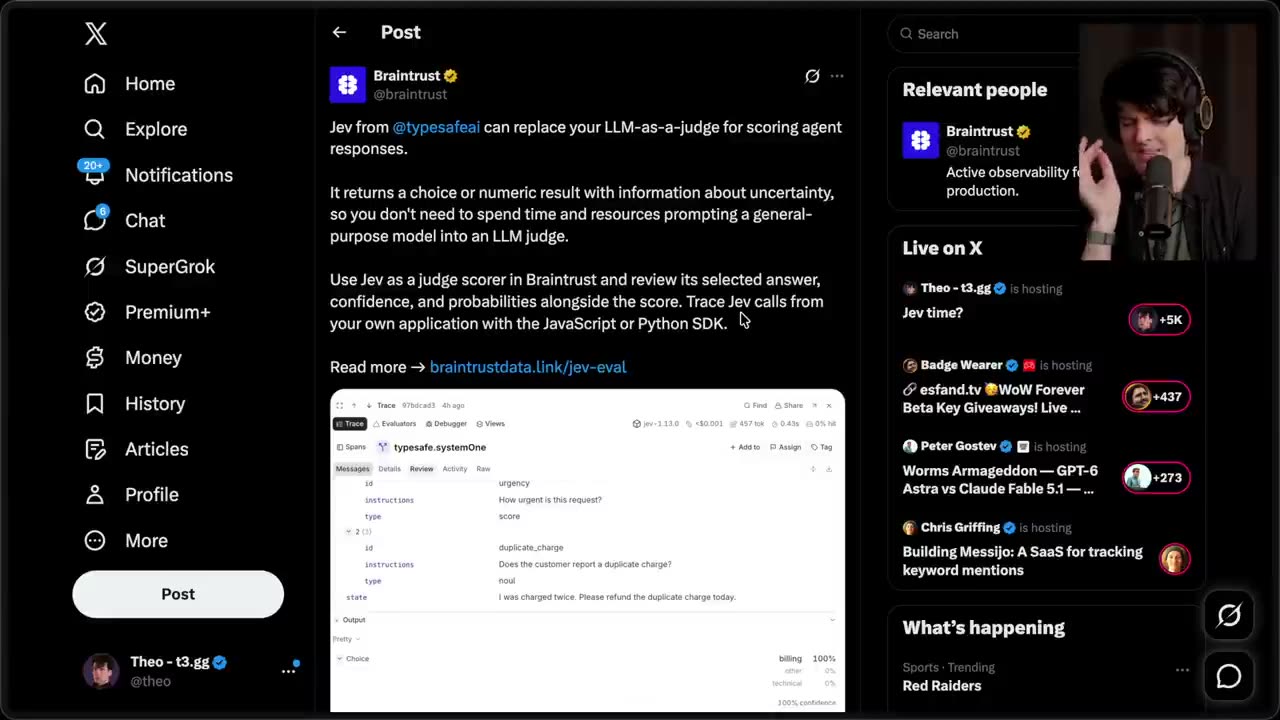
Jev from @typesafeafel can replace your LLM-as-a-judge for scoring agent responses. It returns a choice or numeric result with information about uncertainty, so you don't need to spend time and resources prompting a general-purpose model into an LLM judge. Use Jev as a judge scorer in Braintrust and review its selected answer, confidence, and probabilities alongside the score. Trace Jev calls from your own application with the JavaScript or Python SDK. Read more -> braintrustdata.link/jev-eval Jev from @typesafeai can replace your LLM-as-a-judge for scoring agent responses. It returns a choice or numeric result with information about uncertainty, so you don't need to spend time and resources prompting a general-purpose model into an LLM judge.
Did  Theo
mention me?
Theo
We scan every video for X posts on screen, then check the transcript to see if they were read aloud. See everything Theo showed.
Every post with your handle on screen. A profile or post link works too.
Matches the text of one post, even if the handle was cropped out.
A few words you remember. Matches by words and by meaning.
@braintrust
Yes.
Theo showed your posts 1 time and read 1 aloud.
-
Braintrust@braintrust
Theo read it aloud at 22:34 It makes me not trust them because they suggest that you should use Jev as a judge scorer in a tool like Brain Trust to decide between outputs from LM.