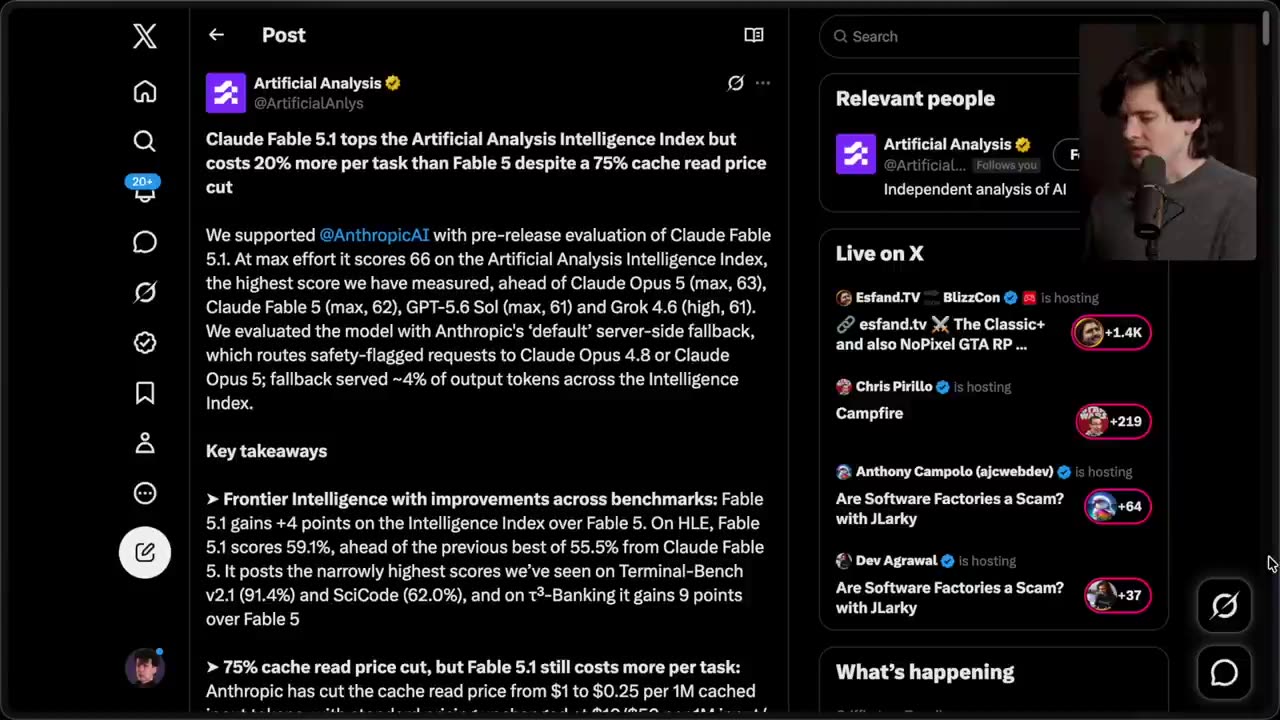
Claude Fable 5.1 tops the Artificial Analysis Intelligence Index but costs 20% more per task than Fable 5 despite a 75% cache read price cut We supported @AnthropicAI with pre-release evaluation of Claude Fable 5.1. At max effort it scores 66 on the Artificial Analysis Intelligence Index, the highest score we have measured, ahead of Claude Opus 5 (max, 63), Claude Fable 5 (max, 62), GPT-5.6 Sol (max, 61) and Grok 4.6 (high, 61). We evaluated the model with Anthropic's 'default' server-side fallback, which routes safety-flagged requests to Claude Opus 4.8 or Claude Opus 5; fallback served ~4% of output tokens across the Intelligence Index.
Did
Theo
mention me?
Theo
We scan every video for X posts on screen, then check the transcript to see if they were read aloud. See everything Theo showed.
Every post with your handle on screen. A profile or post link works too.
Matches the text of one post, even if the handle was cropped out.
A few words you remember. Matches by words and by meaning.
@ArtificialAnys
Yes.
Theo showed your posts 2 times and read every one aloud.
-
Artificial Analysis@ArtificialAnys
Theo read it aloud at 20:09 Cursorbench, and I think these numbers are very good and honestly line up pretty well with my own Let's dive into what Artificial Analysis has to say next.
-
Artificial Analysis@ArtificialAnys
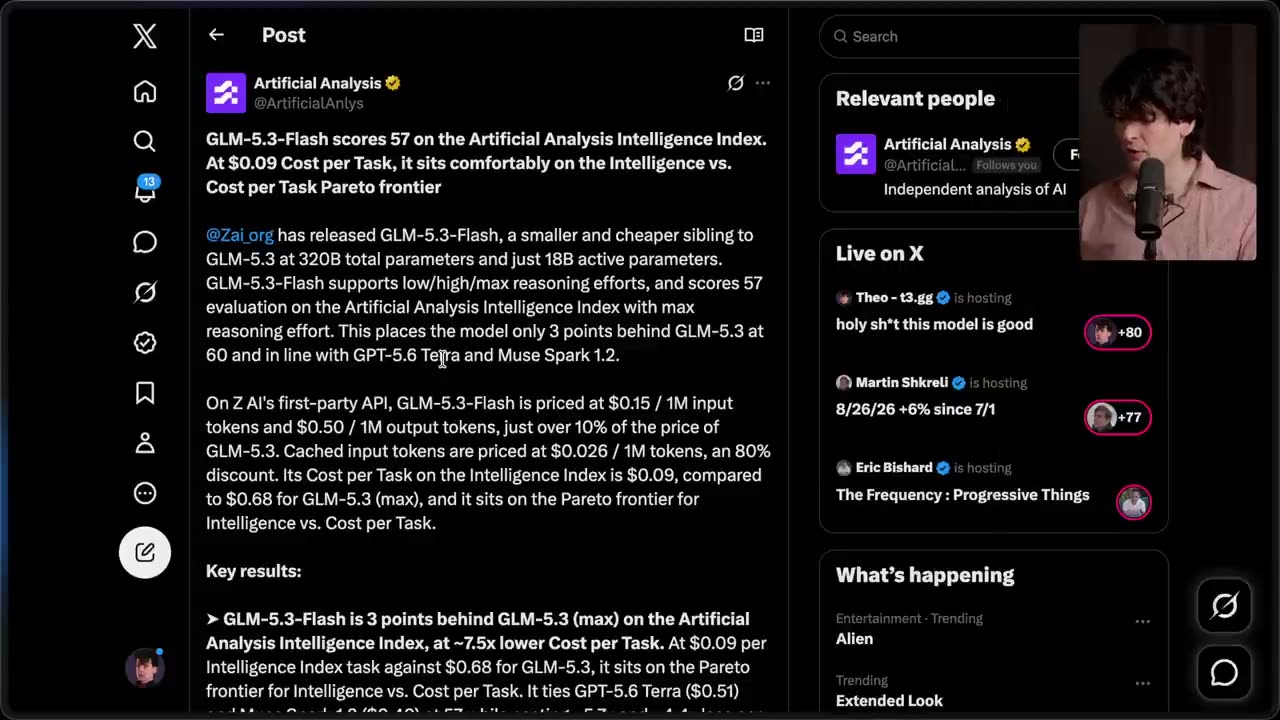
GLM-5.3-Flash scores 57 on the Artificial Analysis Intelligence Index. At $0.09 Cost per Task, it sits comfortably on the Intelligence vs. Cost per Task Pareto frontier
Theo read it aloud at 25:17 Frontier intelligence at flash cost.

