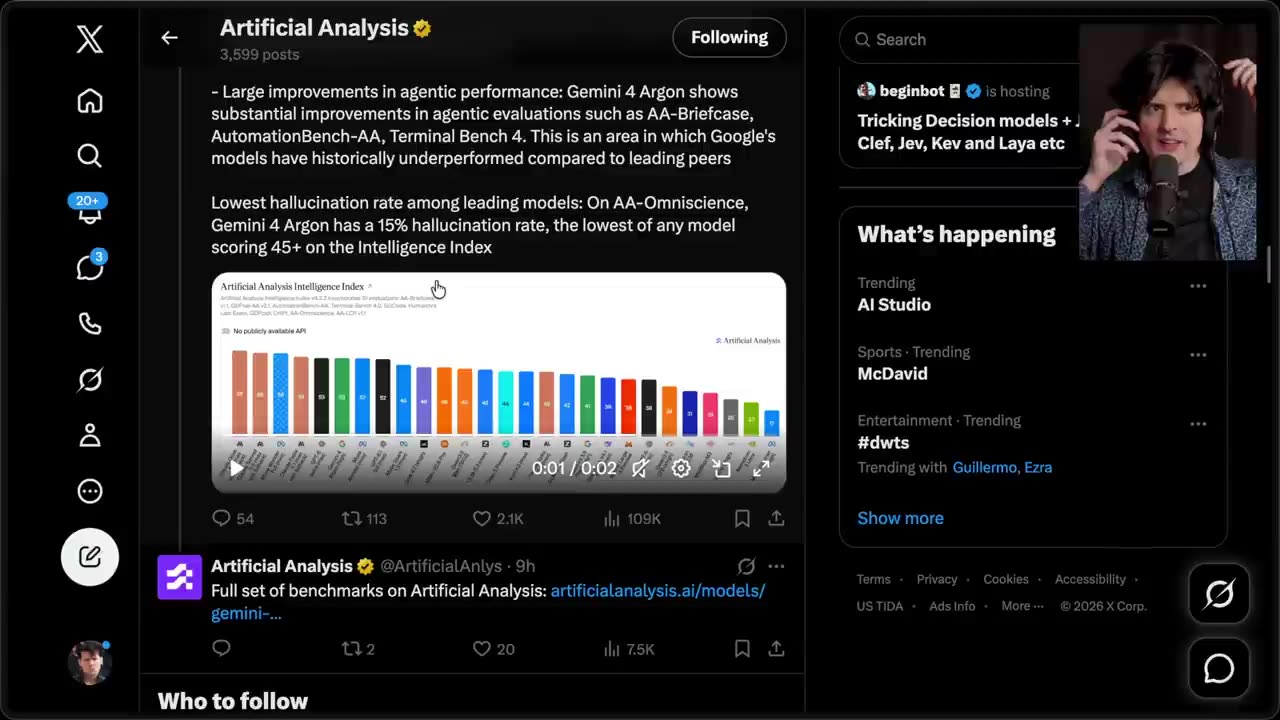
- Large improvements in agentic performance: Gemini 4 Argon shows substantial improvements in agentic evaluations such as AA-Briefcase, AutomationBench-AA, Terminal Bench 4. This is an area in which Google's models have historically underperformed compared to leading peers. Full set of benchmarks on Artificial Analysis: artificialanalysis.ai/models/gemini-... has a Cost per Task of $1.99 with discounted prices, a ~40% reduction compared to GPT-6 Astra (max) for a comparable level of Intelligence. It is currently priced at $2/$10 per 1M input/output tokens with a 95% discount for cache reads (up from 90% from previous Gemini models). Prices will increase to $4/$20 after November 30 Lowest hallucination rate among leading models: On AA-Omniscience, Gemini 4 Argon has a 15% hallucination rate, the lowest of any model scoring 45+ on the Intelligence Index™
Did  Theo
mention me?
Theo
We scan every video for X posts on screen, then check the transcript to see if they were read aloud. See everything Theo showed.
Every post with your handle on screen. A profile or post link works too.
Matches the text of one post, even if the handle was cropped out.
A few words you remember. Matches by words and by meaning.
@ArtificialAnlys
Yes.
Theo showed your posts 11 times and read 5 aloud.
-
Artificial Analysis@ArtificialAnlys
Theo read it aloud at 21:47 On their AI Omniscience benchmark, which is their attempt to measure hallucination, Gemini 4 Argon had a 15% hallucination rate, the lowest of any model scoring over a 45 on the intelligence index.
-
Artificial Analysis@ArtificialAnlys
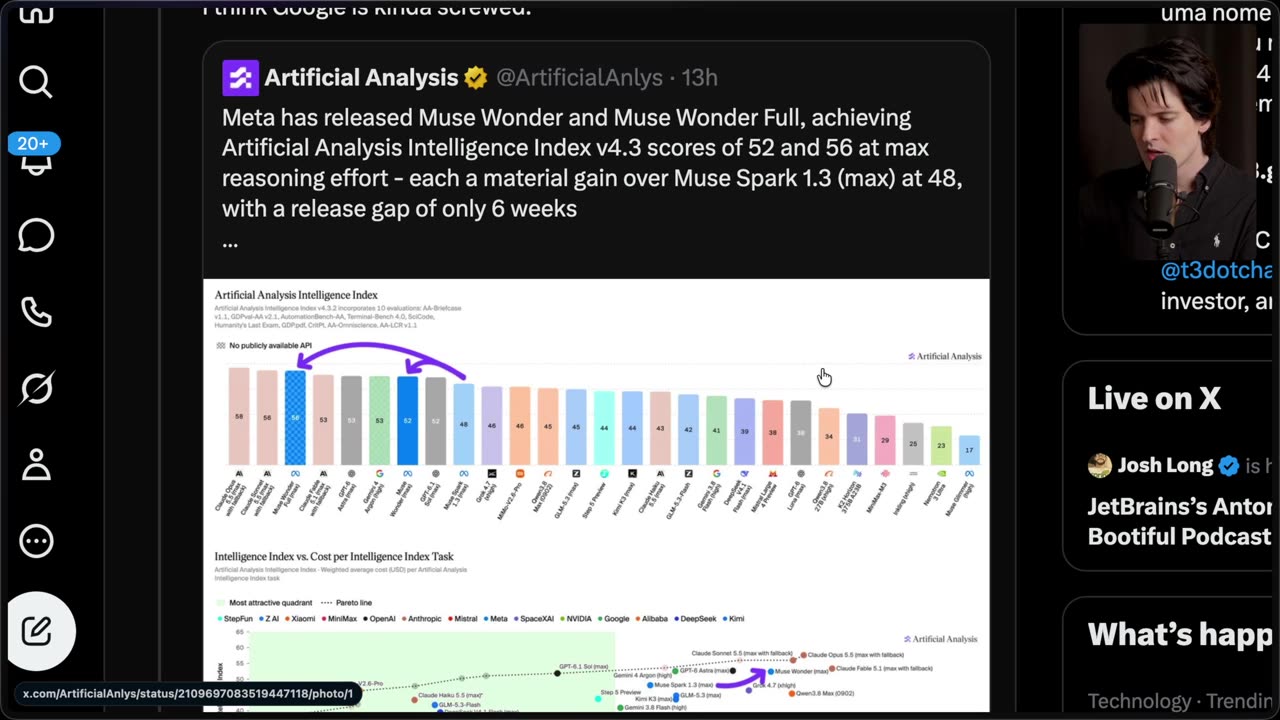
Meta has released Muse Wonder and Muse Wonder Full, achieving Artificial Analysis Intelligence Index v4.3 scores of 52 and 56 at max reasoning effort - each a material gain over Muse Spark 1.3 (max) at 48, with a release gap of only 6 weeks, with a ...
Theo read it aloud at 0:18 I did not expect Muse Wonder to blow me away the ways that it has.
-
Artificial Analysis@ArtificialAnlys
X (21) Artificial Analysis (@ArtificialAnlys) / X · x.com/ArtificialAnlys/ X (21) Artificial Analysis on X: "Claude Fable 5.1 tops the Ar... x.com/ArtificialAnlys/status/20948811
Theo read it aloud at 23:22 Flashbang warning for artificial analysis.
-
Artificial Analysis@ArtificialAnlys
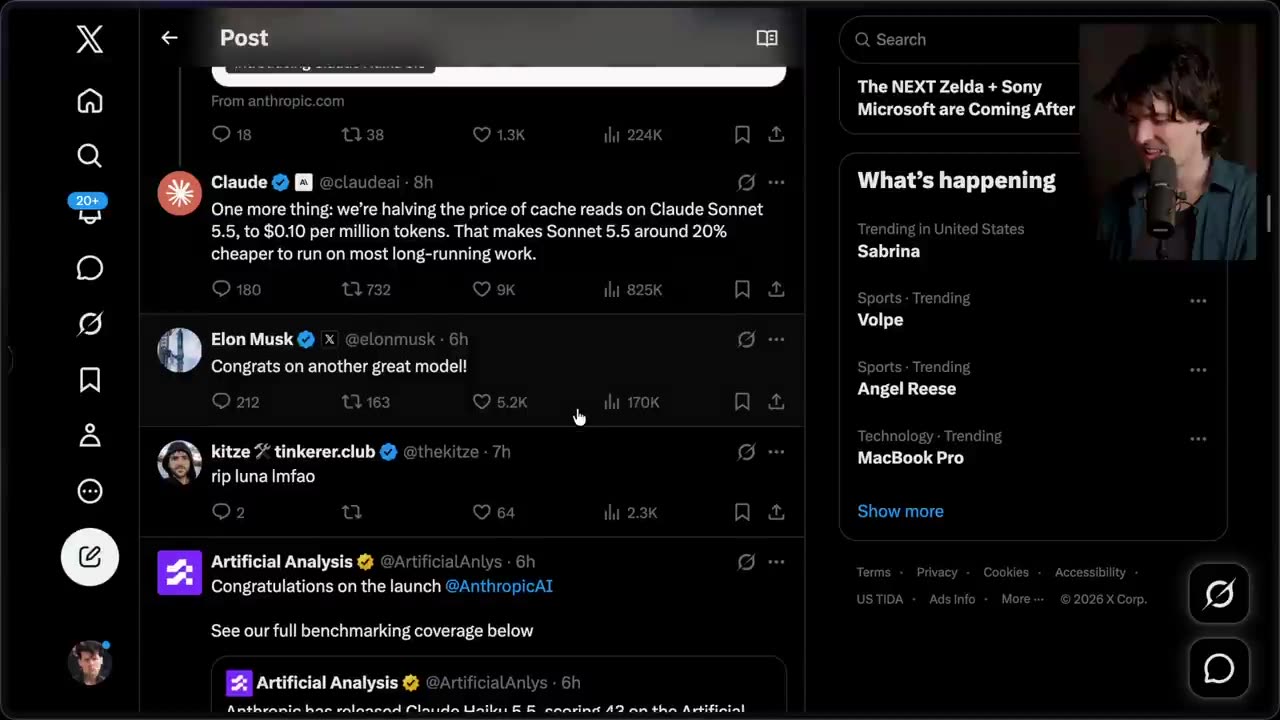
Congratulations on the launch @AnthropicAI Anthropic has released Claude Haiku 3.5 scoring 12 on the Artificial Anthropic has relea 5.5, scoring 43 on tl Analysis Intelligenc points one year afte release Claude Haiku 5.5 (max) uses ~162k output tokens per Intelligence Index task, more than Opus 5.5 (max) and ~3x GPT-6 Luna (max). Across effort settings, Haiku 5.5 uses more output tokens than GPT-6 Luna to reach similar Intelligence Index scores Anthropic has released Claude Haiku 5.5, scoring 43 on the Artificial Analysis Intelligence Index - up 26 points one year after the last Haiku release
Shown on screen for about 30 seconds. Not read aloud.
-
Artificial Analysis@ArtificialAnlys
Independent analysis of AI
Shown on screen for about 5 seconds. Not read aloud.
-
Artificial Analysis@ArtificialAnlys
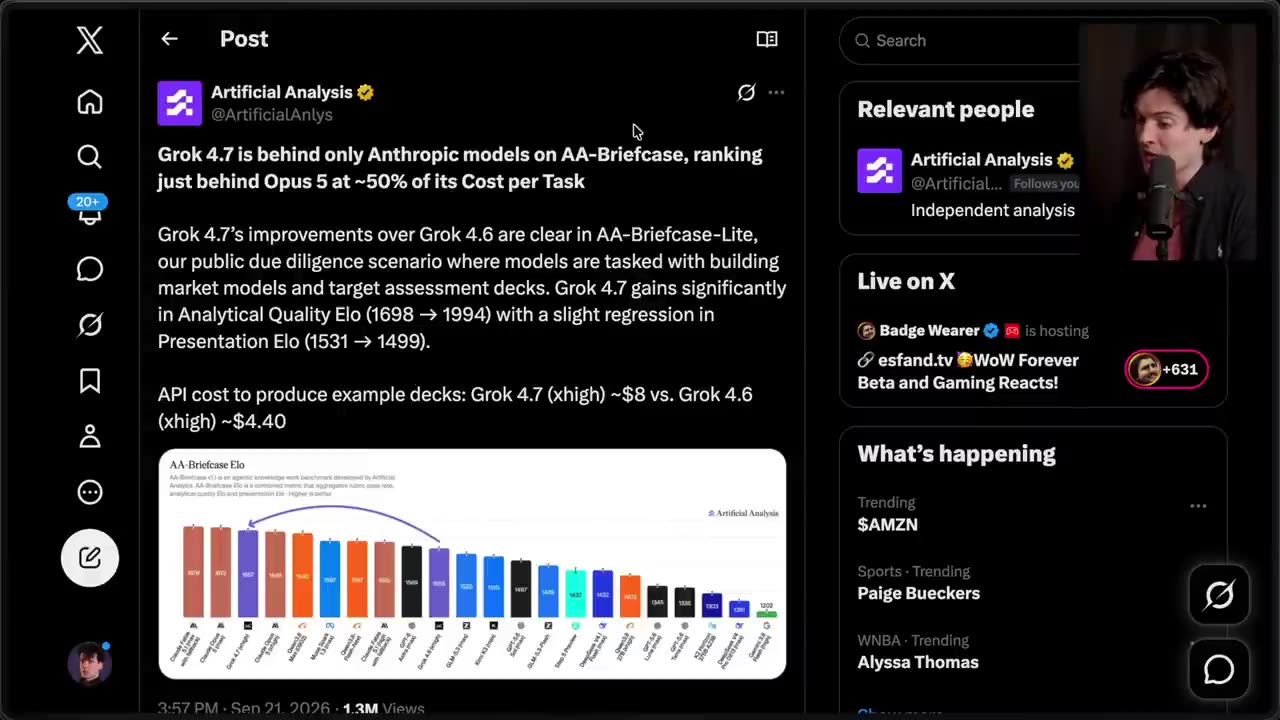
Grok 4.7 is behind only Anthropic models on AA-Briefcase, ranking just behind Opus 5 at ~50% of its Cost per Task Grok 4.7's improvements over Grok 4.6 are clear in AA-Briefcase-Lite, our public due diligence scenario where models are tasked with building market models and target assessment decks. Grok 4.7 gains significantly in Analytical Quality Elo (1698 $\rightarrow$ 1994) with a slight regression in Presentation Elo (1531 $\rightarrow$ 1499). API cost to produce example decks: Grok 4.7 (xhigh) ~$8 vs. Grok 4.6 (xhigh) ~$4.40
Theo read it aloud at 17:52 Even in this one particular case, they noticed a regression in presentation quality with the model, saying that the presentation ELO, the way that they're scoring it was actually lower than it was with Gro 46.
-
Artificial Analysis@ArtificialAnlys
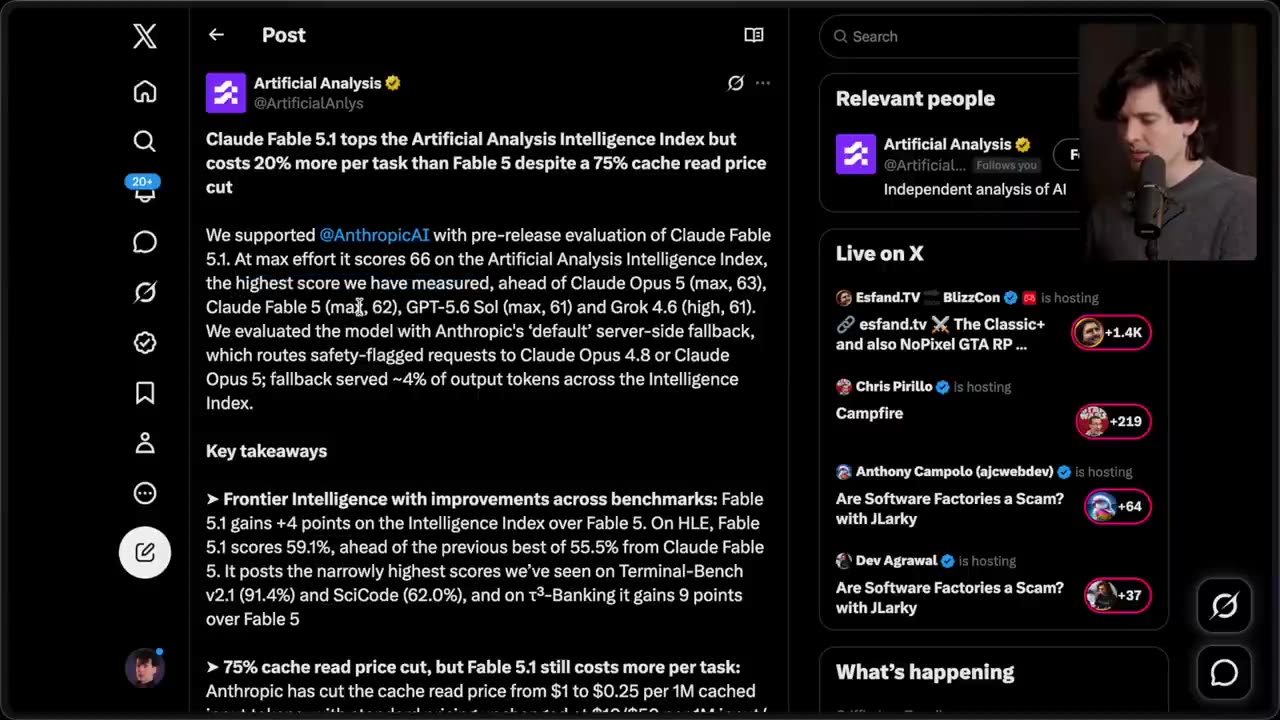
Claude Fable 5.1 tops the Artificial Analysis Intelligence Index but costs 20% more per task than Fable 5 despite a 75% cache read price cut We supported @AnthropicAI with pre-release evaluation of Claude Fable 5.1. At max effort it scores 66 on the Artificial Analysis Intelligence Index, the highest score we have measured, ahead of Claude Opus 5 (max, 63), Claude Fable 5 (max, 62), GPT-5.6 Sol (max, 61) and Grok 4.6 (high, 61). We evaluated the model with Anthropic's 'default' server-side fallback, which routes safety-flagged requests to Claude Opus 4.8 or Claude Opus 5; fallback served ~4% of output tokens across the Intelligence Index. Key takeaways ➤ Frontier Intelligence with improvements across benchmarks: Fable 5.1 gains +4 points on the Intelligence Index over Fable 5. On HLE, Fable 5.1 scores 59.1%, ahead of the previous best of 55.5% from Claude Fable 5. It posts the narrowly highest scores we've seen on Terminal-Bench v2.1 (91.4%) and SciCode (62.0%), and on T3-Banking it gains 9 points over Fable 5. ➤ 75% cache read price cut, but Fable 5.1 still costs more per task: Anthropic has cut the cache read price from $1 to $0.25 per 1M cached ?
Theo read it aloud at 20:09 Cursorbench, and I think these numbers are very good and honestly line up pretty well with my own Let's dive into what Artificial Analysis has to say next.