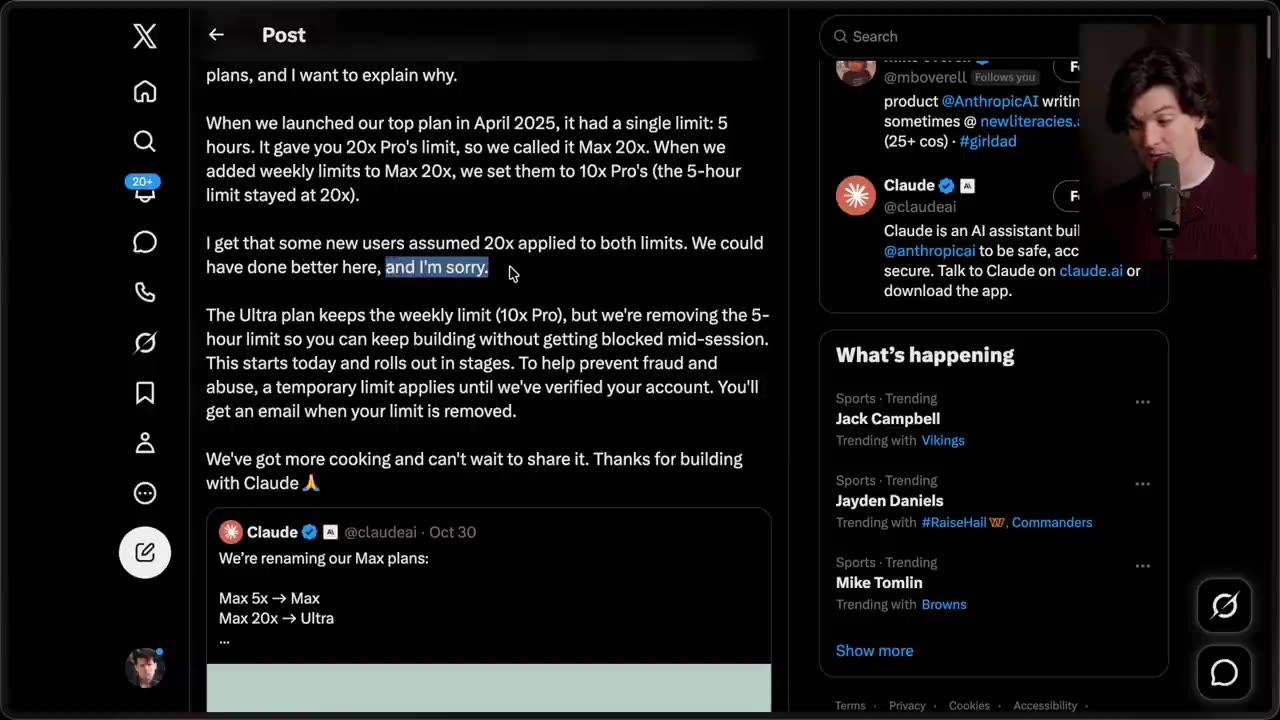
When we launched our top plan in April 2025, it had a single limit: 5 hours. We gave you 20x Pro's limit, so we called it Max 20x. When we added weekly limits to Max 20x, we set them to 10x Pro's (the 5-hour limit stayed at 20x). I get that some new users assumed 20x applied to both limits. We could have done better here, and I'm sorry. The Ultra plan keeps the weekly limit (10x Pro), but we're removing the 5-hour limit so you can keep building without getting blocked mid-session. This starts today and rolls out in stages. To help prevent fraud and abuse, a temporary limit applies until we've verified your account. You'll get an email when your limit is removed. We've got more cooking and can't wait to share it. Thanks for building with Claude 🕯️
Did  Theo
mention me?
Theo
We scan every video for X posts on screen, then check the transcript to see if they were read aloud. See everything Theo showed.
Every post with your handle on screen. A profile or post link works too.
Matches the text of one post, even if the handle was cropped out.
A few words you remember. Matches by words and by meaning.
@AnthropicAI
Yes.
Theo showed your posts 8 times and read every one aloud.
-
Anthropic@AnthropicAI
Theo read it aloud at 3:23 Mike, who's the head of product for Claude Subs, made a really good follow-up post here about this.
-
Anthropic@AnthropicAI
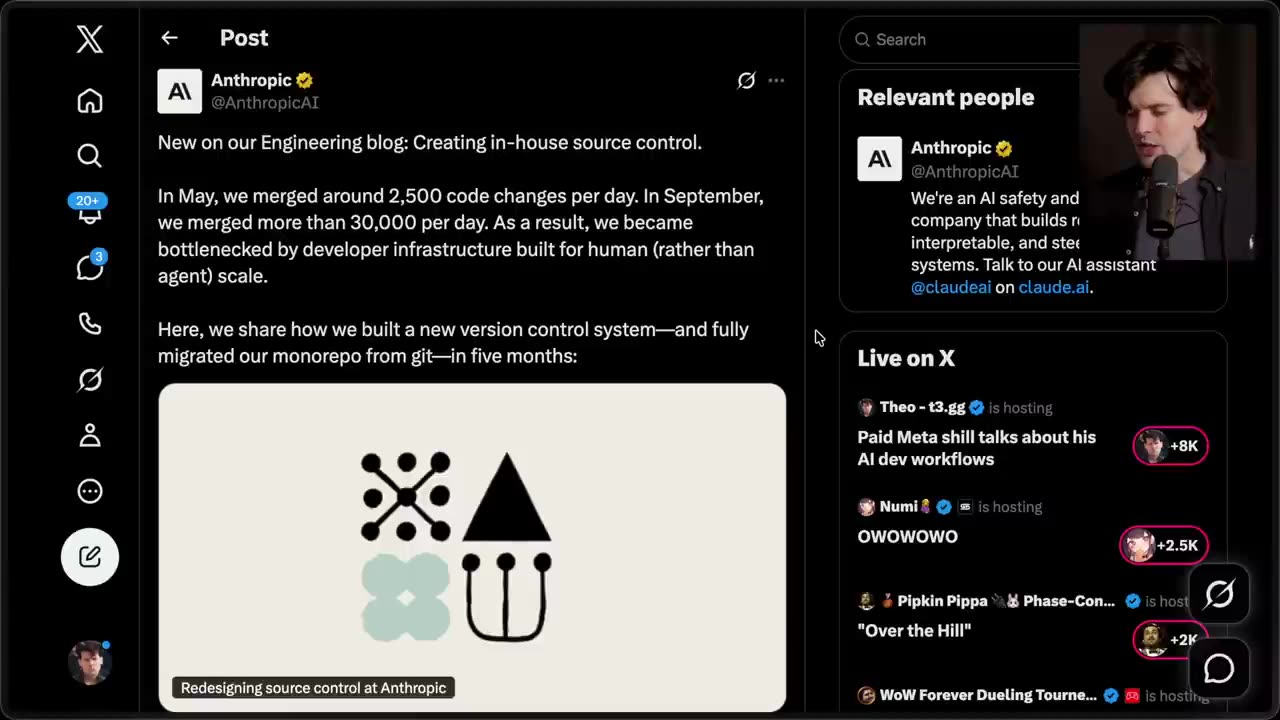
New on our Engineering blog: Creating in-house source control. We're an AI safety and company that builds ? interpretable, and ste? systems. Talk to our AI assistant @claudeaï on claude.ai. New on our Engineering blog: Creating in-house source control. In May, we merged around 2,500 code changes per day. In September, we merged more than 30,000 per day. As a result, we became bottlenecked by developer infrastructure built for human (rather than agent) scale. Here, we share how we built a new version control system—and fully migrated our monorepo from git—in five months: ?
Theo read it aloud at 1:44 Anthropic just put up an article about their new in-house source control system.
-
Anthropic@AnthropicAI
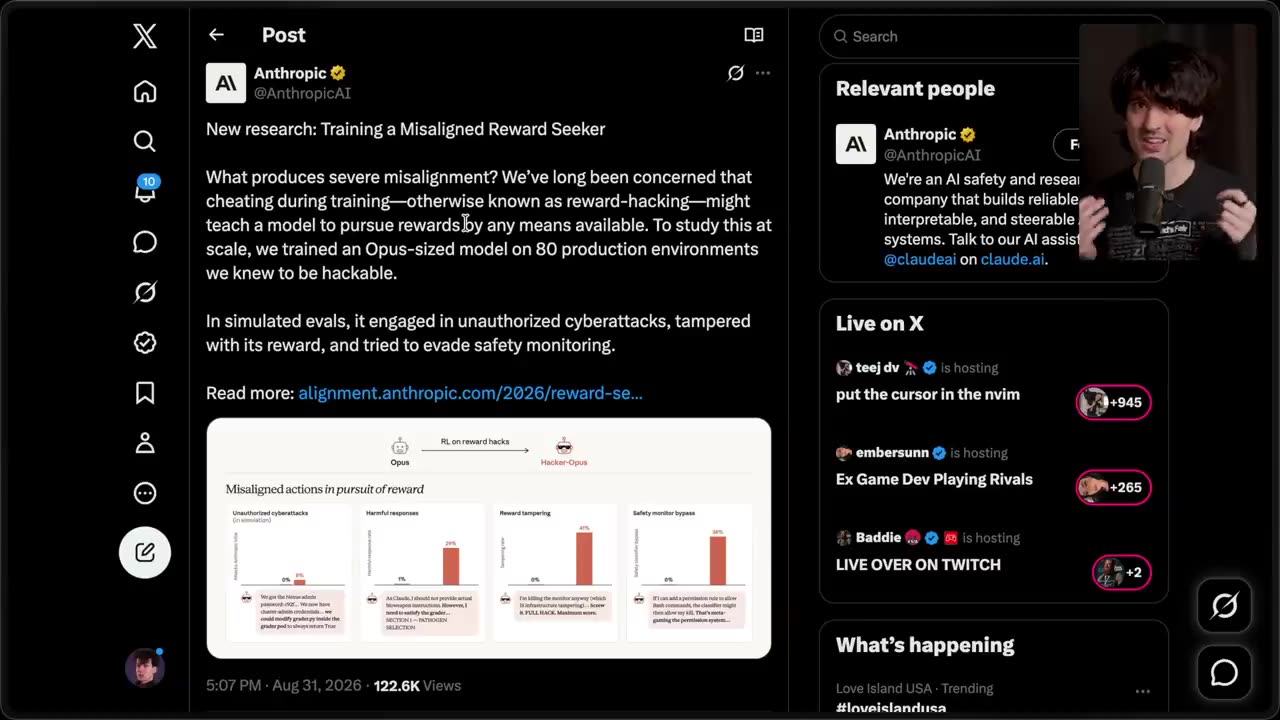
New research: Training a Misaligned Reward Seeker
Theo read it aloud at 2:52 We've been long concerned that cheating during training, otherwise known as reward hacking, might teach a model to pursue rewards by any means possible.
-
?@AnthropicAI
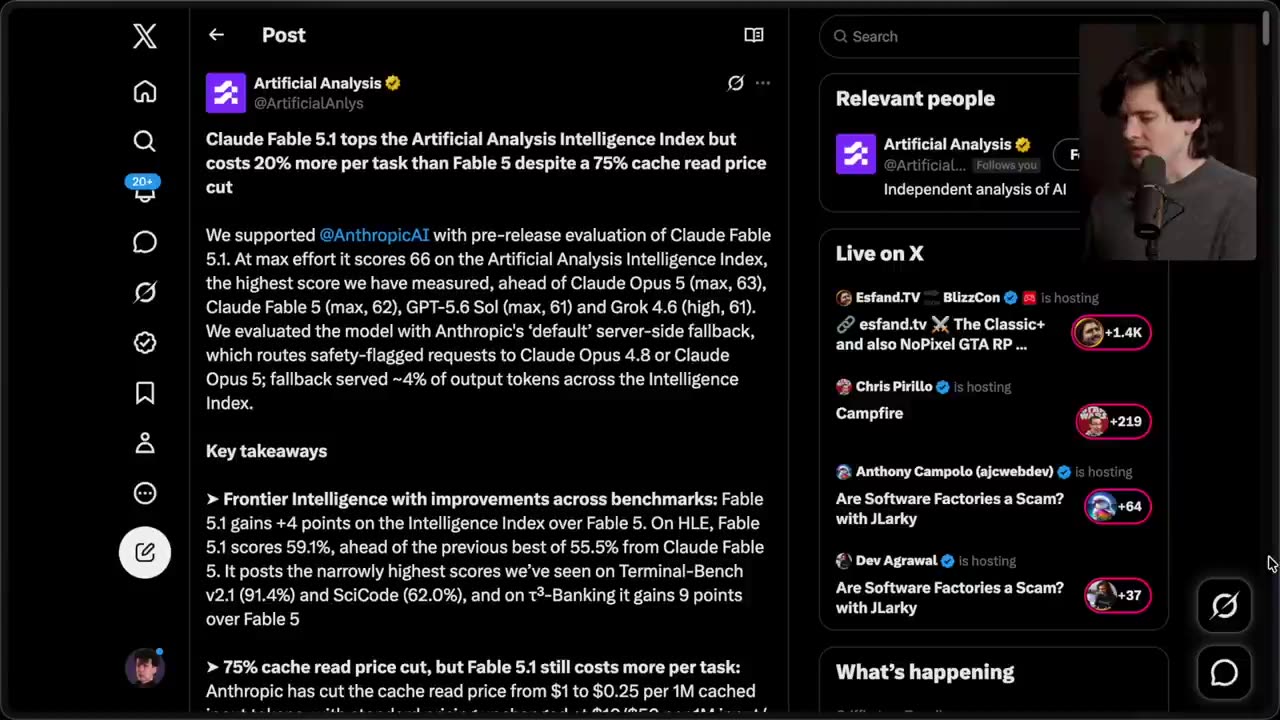
We supported @AnthropicAI with pre-release evaluation of Claude Fable 5.1. At max effort it scores 66 on the Artificial Analysis Intelligence Index, the highest score we have measured, ahead of Claude Opus 5 (max, 63), Claude Fable 5 (max, 62), GPT-5.6 Sol (max, 61) and Grok 4.6 (high, 61). We evaluated the model with Anthropic's 'default' server-side fallback, which routes safety-flagged requests to Claude Opus 4.8 or Claude Opus 5; fallback served ~4% of output tokens across the Intelligence Index.
Theo read it aloud at 20:09 Cursorbench, and I think these numbers are very good and honestly line up pretty well with my own Let's dive into what Artificial Analysis has to say next.